7Dense associative memory: the wall was never a law
Recommended reading
Core (~1 h).Krotov and Hopfield (2016) — the founding paper of modern Hopfield networks, and Hopfield’s own return to his 1982 model: the energy \(E = -\sum_\mu F(\xi^\mu \cdot s)\), the interaction function \(F\) as a capacity dial, and the polynomial capacity \(\sim N^{n-1}\). Read for the energy and the capacity claim; the derivation below makes the mechanism precise. Alongside it, Demircigil et al. (2017) — the exponential-interaction case and the proof that capacity can be exponential in \(N\); read the main theorems and the signal-to-noise core of the proof, which is Week 2’s argument with a sharper filter.
Optional background.Ramsauer et al. (2021) — the continuous-state modern Hopfield network; this is the next lecture’s paper, so skim the energy and the update rule only; Krotov and Hopfield (2021) for the unifying “general Hopfield network” framing; and Chapter 4 of this script, whose signal-to-crosstalk machinery is re-used wholesale today.
Prerequisite reminder. All of Week 2 — the Hopfield energy, the overlap \(m\), the load \(\alpha = P/N\), the signal-plus-crosstalk split of Section 3.5, the CLT-Gaussian crosstalk of variance \(\alpha\), and \(\alpha_c \approx 0.138\) — plus the Gaussian-tail estimates of Chapter 2. New today: the interaction function \(F\) as a capacity dial, the amplification of signal over crosstalk by \(F'\), and the polynomial and exponential capacity laws.
7.1 The wall was never a law
Recall where Week 2 left associative memory. A network of \(N\) neurons and \(N^2\) Hebbian couplings stores \(\alpha_c N \approx 0.138\,N\) patterns; past that load, retrieval does not degrade but ceases to exist (Section 4.4, Equation 4.6). The number was often read as a verdict on the whole idea: associative memory appeared fundamentally inefficient, with a hundred and thirty-eight memories from a million synapses.
The \(0.138\,N\) wall is, however, a property of the particular energy function Hopfield wrote down. Networks with higher-order couplings were already studied in the 1980s and were known to store more, and Gardner showed that freely chosen pairwise couplings reach \(2N\)(Gardner 1988). In 2016, Krotov and Hopfield (Hopfield returning to his own model thirty-four years on) recast the idea as an energy with a tunable interaction function and showed that sharpening it lifts the capacity to \(N^{n-1}\) for any degree \(n\)(Krotov and Hopfield 2016); a year later, Demircigil et al. (2017) proved that an exponential interaction stores a number of patterns exponential in \(N\), with basins of attraction that remain macroscopic. What set the wall was the shape of the energy function.
Capacity is determined by how sharply each stored pattern’s contribution to the energy is peaked around that pattern. There is a function — the interaction function\(F\) — whose steepness controls this: degree two gives linear capacity, polynomial degree \(n\) gives \(N^{n-1}\), and an exponential gives \(2^{cN}\).
We are still in Module 1, and we have returned to the cold: today’s network is Week 2’s retrieval machine — deterministic, \(T = 0\), couplings written rather than learned, no probabilities and no \(Z\) (the partition function, central in Week 3, plays no role this week). In the next lecture the scaled-up retrieval rule will turn out to sit at the center of the architecture that now dominates machine learning. Week 3’s \(2^N\) counted the states in \(Z\); this week’s exponential counts storable patterns, and the ledger of Section 7.6 compares the two.
Take-home 1
The \(0.138\,N\) capacity is a property of the quadratic Hopfield energy. In the generalized energy \(E = -\sum_\mu F(\xi^\mu \cdot s)\), the steepness of \(F'\) sets how strongly the matching pattern dominates the crosstalk, and hence the capacity.
7.2 The model: an energy with a dial
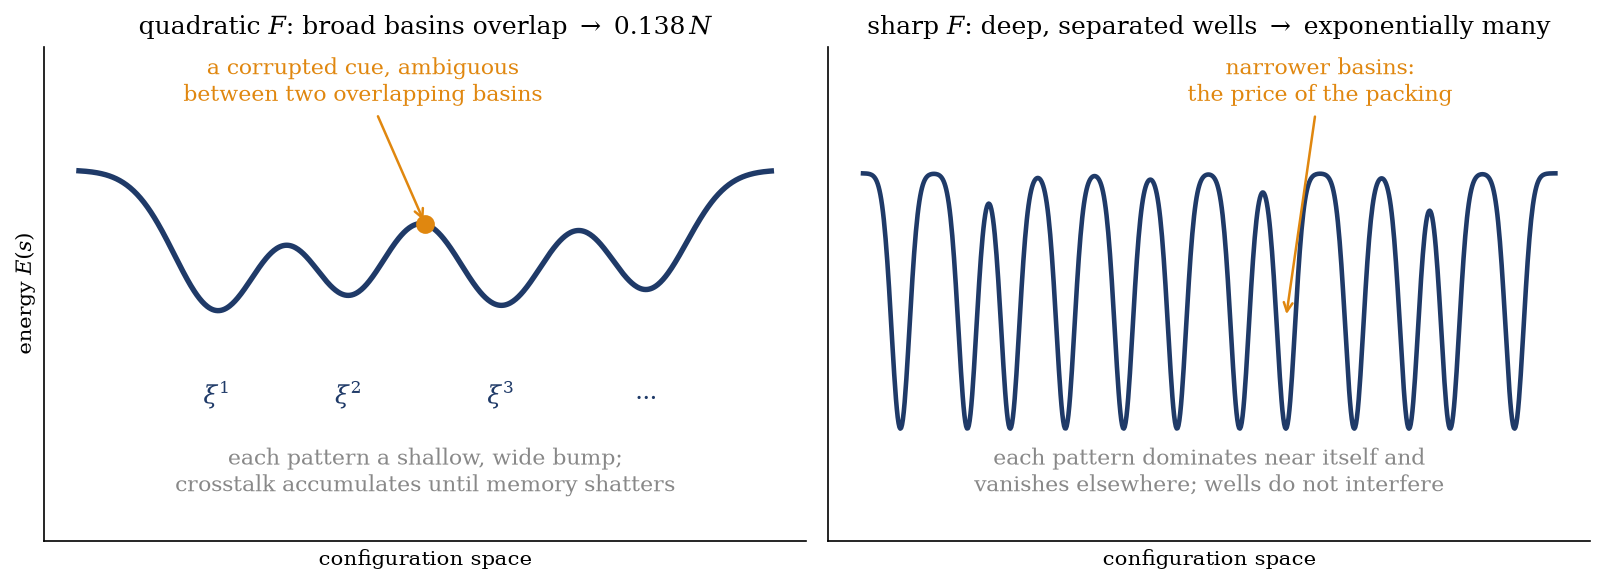
Figure 7.1 contrasts two landscapes before any formula. In the classical landscape (quadratic energy), each stored pattern contributes a broad, shallow basin. Broad basins overlap; overlapping basins interfere; and Week 2 quantified the interference — a CLT-Gaussian crosstalk of variance \(\alpha\) that drowns the unit signal at \(\alpha_c\) (Equation 4.1). In the dense landscape (sharp interaction), each pattern contributes a deep, narrow well that dominates near itself and dies off elsewhere. Narrow wells do not overlap, so vastly more of them fit before they interfere — and the count will turn out to be exponential. In short: capacity is basin geometry, and the interaction function sets the geometry.
Figure 7.1: Capacity as basin geometry. Left: the quadratic energy of Week 2 — every stored pattern a broad, shallow bump; basins overlap, crosstalk accumulates, and at \(\alpha_c \approx 0.138\) retrieval collapses. A corrupted cue sits ambiguously between neighbors. Right: a sharp interaction function — each pattern a deep, narrow, well-separated well that dominates near itself and vanishes elsewhere; exponentially many fit before they interfere. The drawback is visible: narrower wells mean smaller basins of attraction, the tradeoff quantified below.
The dense-memory energy. Following Krotov and Hopfield (2016), keep everything from Week 2 — \(N\) binary neurons \(s_i = \pm 1\), \(P\) random stored patterns \(\xi^\mu\), the overlap as the natural variable — and change one thing: how the overlap enters the energy. Define
where \(\xi^\mu \cdot s = \sum_i \xi_i^\mu s_i\) and \(F\) is a smooth, rapidly growing interaction function (Krotov and Hopfield also say separation function, since it separates the matching pattern from the rest). This \(F\) is not the free energy\(F = -T\log Z\) of Weeks 1 and 3; the collision is standard and confined to this week.
The classical model is the quadratic special case: with \(F(x) = x^2/(2N)\),
Week 2’s Hopfield energy Equation 3.2 up to a constant (the diagonal term, since \(s_i^2 = 1\)). Everything Week 2 proved and computed is the \(F \propto x^2\) row of a bigger table.
The update rule. In Week 2 the energy is linear in each spin, \(E = -s_i h_i + (\text{terms without } s_i)\), so aligning \(s_i\) with its field and setting \(s_i\) to the sign of lower energy are one and the same rule (Section 3.4). For a general \(F\) the energy is no longer linear in \(s_i\), no field is defined in advance, and only the second reading carries over. We therefore set neuron \(i\) to whichever sign gives the lower energy,
asynchronously, one neuron at a time. Two consistency checks follow. First, for the quadratic case the bracket collapses (each term is a difference of squares) to \(\propto \sum_\mu \xi_i^\mu \sum_{j \neq i} \xi_j^\mu s_j\) — exactly the local field of Equation 3.1: the classical rule falls out unchanged (Demircigil et al. 2017). Second, the Lyapunov argument of Section 3.4 survives verbatim for any\(F\): the rule flips only when the flip lowers \(E\), configuration space is finite, so the dynamics descends and halts in a local minimum. The landscape picture is a theorem here too.
For smooth \(F\) the bracket linearizes — the two arguments differ by \(\pm 2\xi_i^\mu\) — and the update reads \(s_i \leftarrow \operatorname{sign}(h_i)\) with the effective field
— the central object of the analysis. The field is a vote of the stored patterns, exactly as in Week 2 — but now each pattern votes with weight \(F'(\text{its current overlap})\). A steep \(F'\) means the pattern the state currently resembles dominates the vote, and every other pattern barely registers. The interaction function is a filter on the vote, and capacity is decided by how sharply that filter discriminates.
7.3 Signal versus crosstalk, revisited
The derivation repeats Week 2’s signal-versus-crosstalk analysis — the same apparatus, the same CLT, the same Gaussian tails — with \(F'\) now amplifying the signal. In Week 2 the aligned field was \(1 + C_i\) with crosstalk \(C_i \sim \mathcal{N}(0, \alpha)\), and signal barely exceeded crosstalk — the margin vanished at \(\alpha_c\). A steeper \(F'\) widens that margin.
Step 1 — where the two sides live. Put the network at a stored pattern, \(s = \xi^\nu\), and read the effective field Equation 7.3 in its aligned form \(h_i\xi_i^\nu\), as in Week 2: bit \(i\) is stable as long as the aligned field is positive. The matching term has \(\xi^\nu \cdot s = N\): the signal enters through \(F'(N)\). Every other overlap \(\xi^\mu \cdot s\) (\(\mu \neq \nu\)) is a sum of \(N\) independent fair signs — Week 2’s CLT once more — so it is Gaussian of mean zero and width \(\sqrt{N}\): the crosstalk enters through \(F'\big(\mathcal{O}(\sqrt{N})\big)\). The signal and the crosstalk sit at different arguments of the same function,
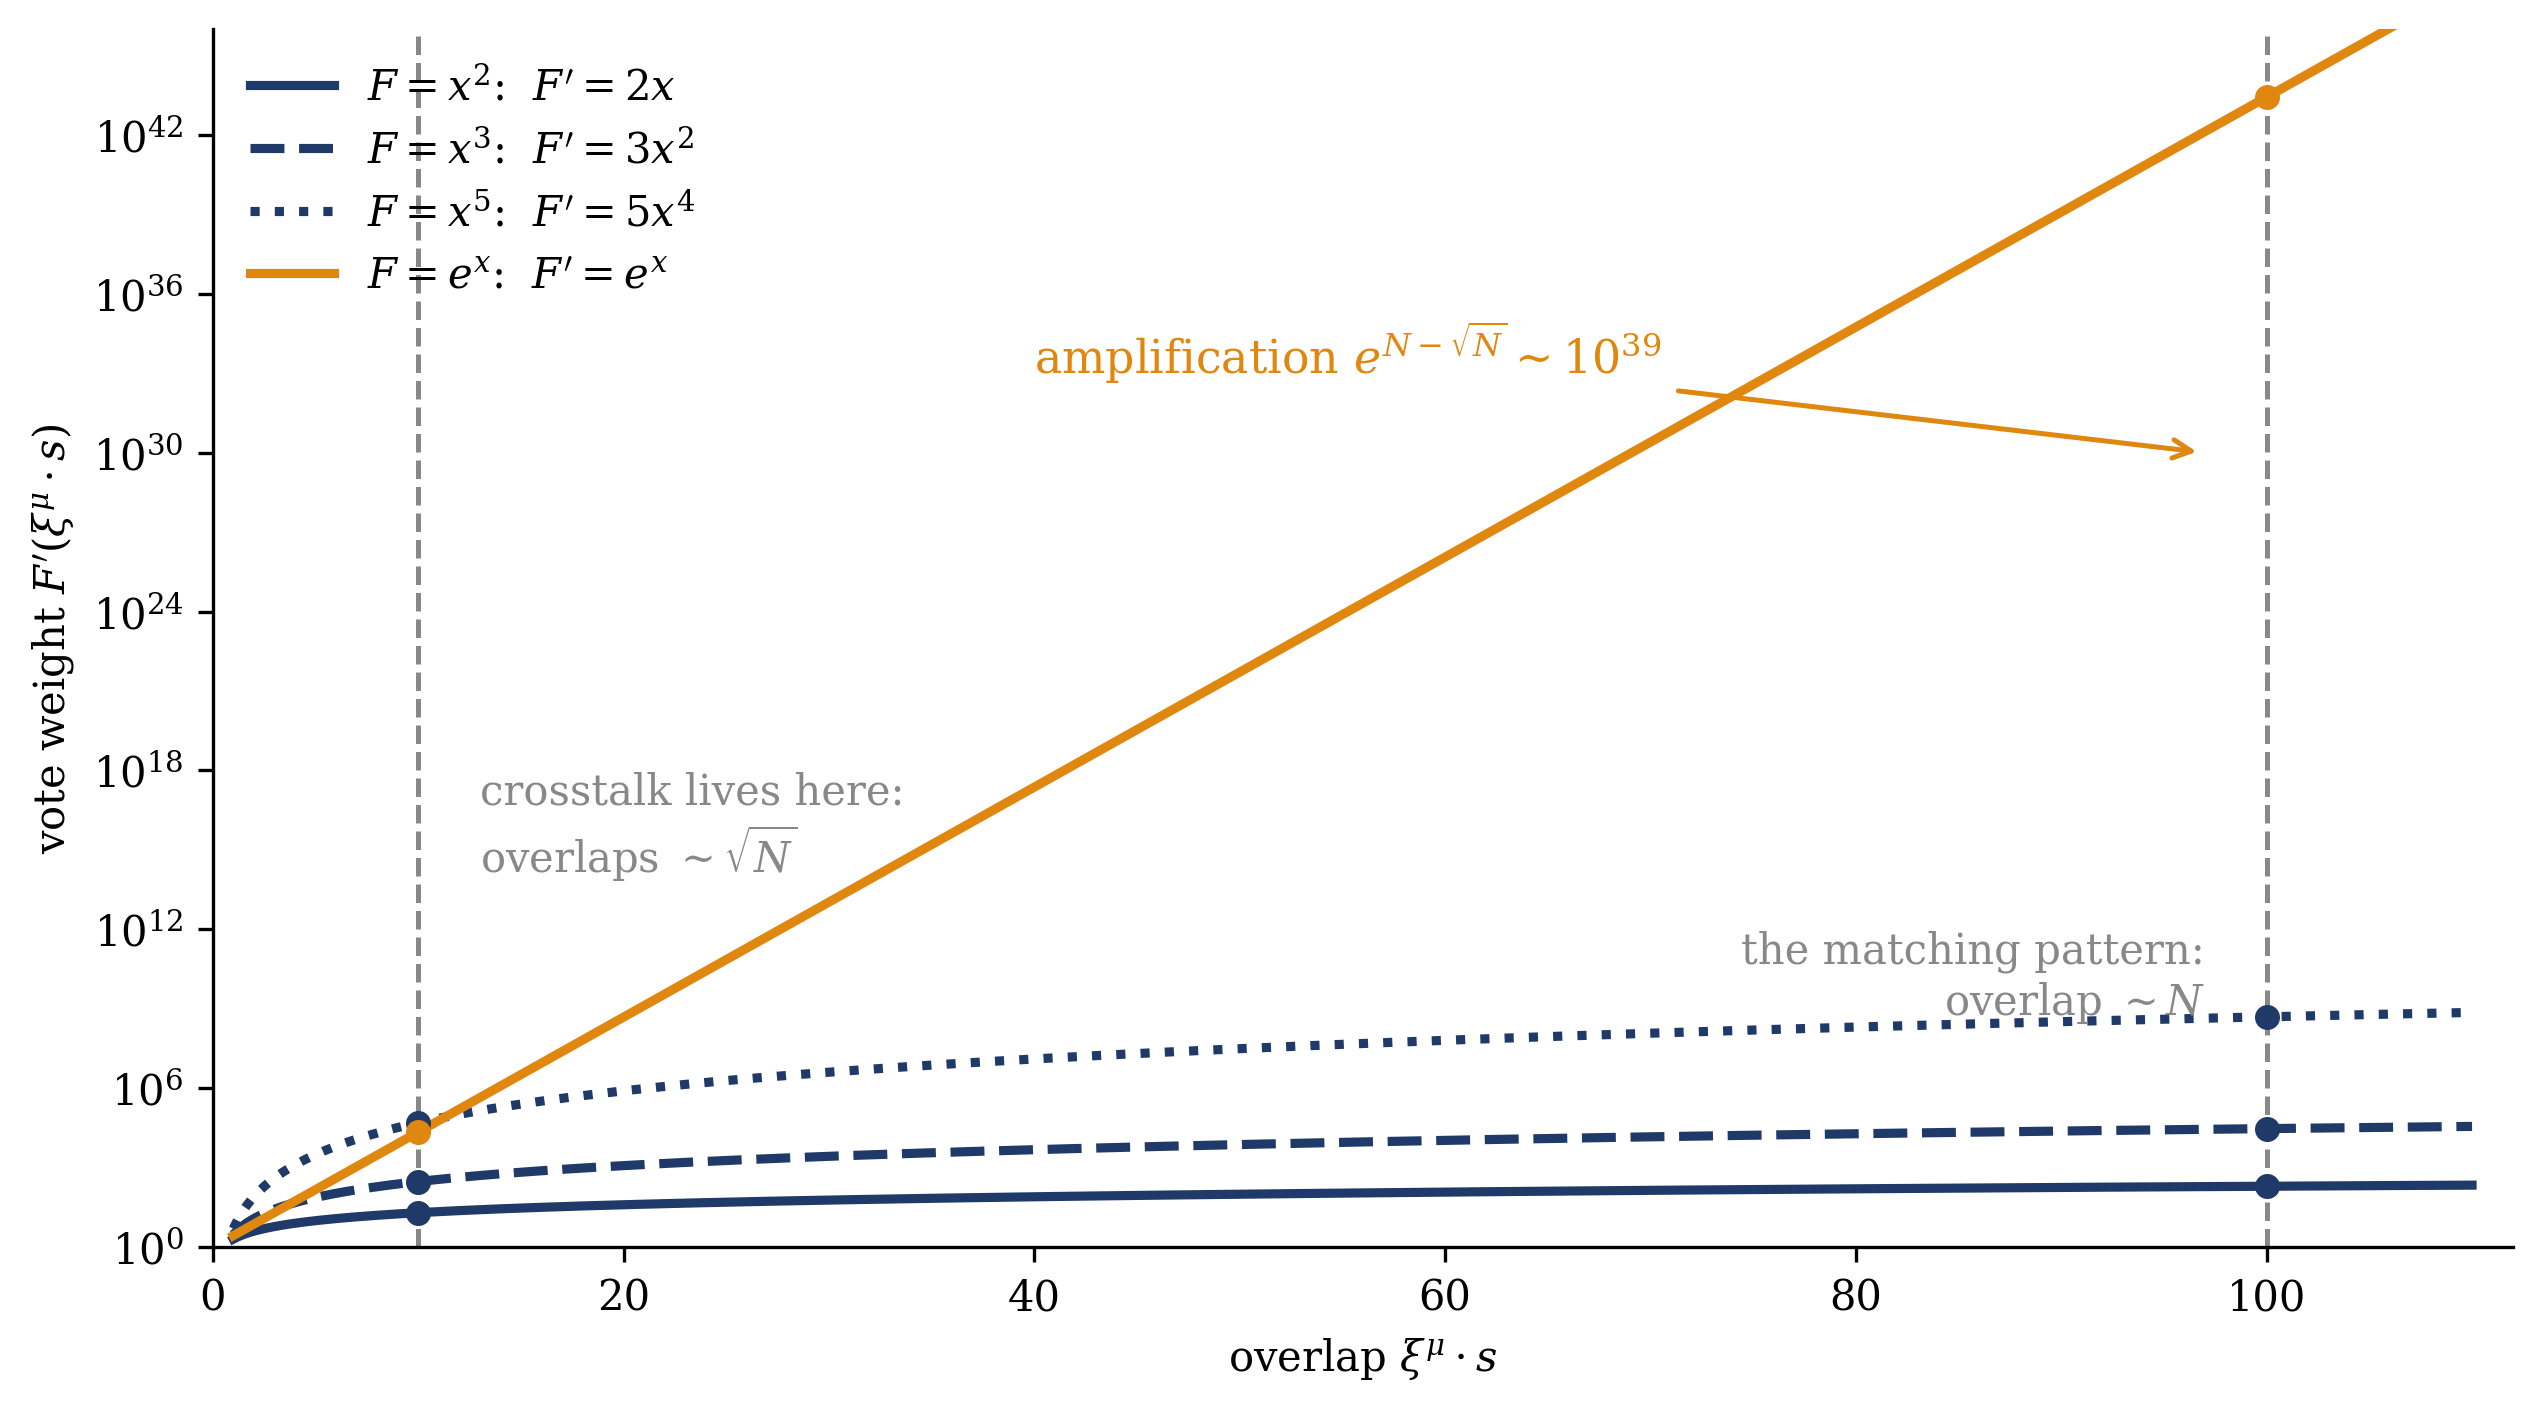
which is Week 2’s \(1 + C_i\) with the unit signal replaced by \(F'(N)\). The signal-to-crosstalk ratio is governed by the amplification factor\(F'(N) / F'(\sqrt{N})\). Figure 7.2 draws it for several choices: for the quadratic, \(F' = 2x\) is a straight line and the factor is a modest \(\sqrt{N}\) — the marginal separation of Week 2. For \(F = x^n\) the factor is \(N^{(n-1)/2}\); for \(F = e^x\) it is \(e^{N - \sqrt{N}}\), already \(\sim 10^{39}\) at \(N = 100\).
The amplification factor becomes a capacity once the field is read as a weighted vote, in which two random walks enter at different levels. Within one pattern, a random \(\xi^\mu\) agrees with the state on about half the sites, and the excess of agreements over disagreements is a walk of \(N\) steps; this sets the weight of each wrong vote, \(F'(\sqrt{N})\). Across patterns, the \(P - 1\) wrong votes carry independent random signs \(\xi_i^\mu \xi_i^\nu\) and largely cancel, so their sum is a second walk, of \(P\) steps, and reaches \(\sqrt{P}\,F'(\sqrt{N})\). Week 2’s crosstalk width is these two walks combined with Hebb’s normalization, \(\sqrt{N}\cdot\sqrt{P}/N = \sqrt{\alpha}\); the normalization of \(F\) cancels in the ratio, which is why we may drop it here. The bit holds as long as the signal outweighs the summed crosstalk, \(F'(N) \gtrsim \sqrt{P}\,F'(\sqrt{N})\), that is
\[
P \;\lesssim\; \bigg( \frac{F'(N)}{F'(\sqrt{N})} \bigg)^{2}.
\tag{7.4}\]
capacity \(\sim\) amplification squared
The capacity scales as the square of the amplification factor: \(N\) for the quadratic and \(N^{n-1}\) for \(F = x^n\), the laws that Steps 2 and 3 make precise, constants included.
The estimate assumes that every wrong pattern sits at the typical overlap \(\sqrt{N}\). For polynomial \(F\) this is accurate; for \(F = e^x\) it is not, because the weight \(e^{\xi^\mu \cdot s}\) is dominated by the rare patterns with unusually large overlap. For \(z \sim \mathcal{N}(0, N)\) the mean-square weight \(\langle e^{2z} \rangle = e^{2N}\) already equals the squared signal, so no average over typical patterns can decide the question. With \(P = e^{\alpha N}\) stored patterns, the largest wrong overlap is, by the extreme-value estimate of Section 4.3, \(\sqrt{2N \ln P} = N\sqrt{2\alpha}\), and retrieval is limited by this single nearest competitor rather than by a typical one. The \(10^{39}\) of Figure 7.2 therefore measures how strongly the matching pattern dominates a typical stored pattern, not the capacity. Requiring the nearest competitor to stay well below overlap \(N\) already yields an exponential law; the sharp constant requires the analysis of Demircigil et al. (2017) quoted in Step 3.
Figure 7.2: The interaction function as a filter, drawn for a network of \(N = 100\) neurons. The derivative \(F'(x)\) weights each stored pattern’s vote in the effective field Equation 7.3; the crosstalk patterns sit at overlaps \(\sim \sqrt{N} = 10\) (left dashed line) while the matching pattern sits at overlap \(N = 100\) (right dashed line). The signal-to-crosstalk amplification \(F'(N)/F'(\sqrt{N})\) is the vertical distance between the two operating points on the logarithmic axis: a factor \(\sqrt{N} = 10\) for the quadratic (the narrow margin of Week 2), \(N = 100\) for the cubic, \(10^4\) for degree five — and thirty-nine orders of magnitude for the exponential. Since the wrong votes add as a random walk over the \(P\) patterns, the capacity scales roughly as the square of the amplification (Equation 7.4), which gives the polynomial laws of Equation 7.5. For the exponential the amplification refers to a typical stored pattern; the capacity is limited instead by the single most similar one.
Step 2 — the bookkeeping. The scaling argument becomes a capacity number exactly the way it did in Week 2: compute the mean and variance of the stability margin, and ask when the Gaussian tail leaks past zero. Following Krotov and Hopfield (2016), take \(F(x) = x^n\) and ask whether bit \(i\) of the stored pattern \(\xi^\nu\) holds — that is, compare the energy of \(s = \xi^\nu\) against the energy with bit \(i\) flipped. The matching term supplies the energy gap (the signal):
while each of the \(P - 1\) crosstalk terms shifts by \(\approx \mp 2n\, (\xi^\mu \cdot s)^{n-1}\) with \(\xi^\mu \cdot s \sim \mathcal{N}(0, N)\). Their fluctuation is set by a Gaussian moment — \(\big\langle z^{2(n-1)} \big\rangle = (2n - 3)!!\, N^{n-1}\) for \(z \sim \mathcal{N}(0, N)\), the origin of the double factorial in the polynomial capacity constants — so the crosstalk variance is
where the last step uses \(P - 1 \approx P\) for \(P \gg 1\), as Week 2 did in writing the crosstalk variance as \(\alpha = P/N\). As a consistency check: \(n = 2\) gives \((2n-3)!! = 1\) and \(x = \sqrt{N/P} = 1/\sqrt{\alpha}\) — exactly the first-sweep error rate Equation 4.2, constant and all. The machinery is identical; only the exponent has changed.
Step 3 — read off the capacity laws. Fix a tolerated per-bit error (retrieval with a small dressing of wrong bits, Week 2’s tolerant question): then \(x = \mathcal{O}(1)\), i.e. \(P \sim N^{n-1}\). Demand instead that every bit of every pattern hold — the strict question — and the union bound over the \(N\) bits of one pattern brings in the usual extreme-value logarithm (Section 4.3): \(x^2 \approx 2\ln N\), i.e. \(P \sim N^{n-1}/\big(2 (2n-3)!! \ln N\big)\)(Krotov and Hopfield 2016); requiring all \(NP\) bits of all patterns gives \(x^2 \approx 2\ln(NP) \approx 2n \ln N\) and a further factor \(1/n\). And for the exponential interaction \(F(x) = e^x\), where the nearest competitor rather than the typical one sets the limit (Step 1), the capacity is exponential — the result Demircigil et al. (2017) made a theorem: storing \(P = e^{\alpha N}\) patterns, every one is a fixed point of the dynamics with probability \(\to 1\) for any \(\alpha < \ln 2 / 2\), i.e. up to
Here \(\alpha_n\) denotes an \(n\)-dependent constant set by the tolerated error. One caveat is inherited from Week 2. These estimates are first-sweep, no-feedback statements — precisely the kind that Section 4.4 showed cannot locate the classical transition, where the errors’ feedback moved the answer from \(2/\pi\) to \(0.138\) and changed its character. For \(n = 2\), then, read the first row as the scaling with the correct constant imported from the self-consistent theory. For \(n > 2\) the situation genuinely improves: the crosstalk suppression is now polynomial or exponential rather than marginal, the union-bound argument can be made rigorous — Demircigil et al. (2017) prove both the polynomial law (for \(P = N^{n-1}/(c_n \ln N)\) with \(c_n > 2(2n-3)!!\)) and the exponential one as theorems — and the first-sweep logic is sufficient.
⇒ The linear derivative \(F' = 2x\) is what made the classical capacity linear. Any \(F\) whose derivative grows faster lets the matching pattern dominate the crosstalk: polynomial sharpness gives polynomial capacity, exponential sharpness gives exponential capacity.
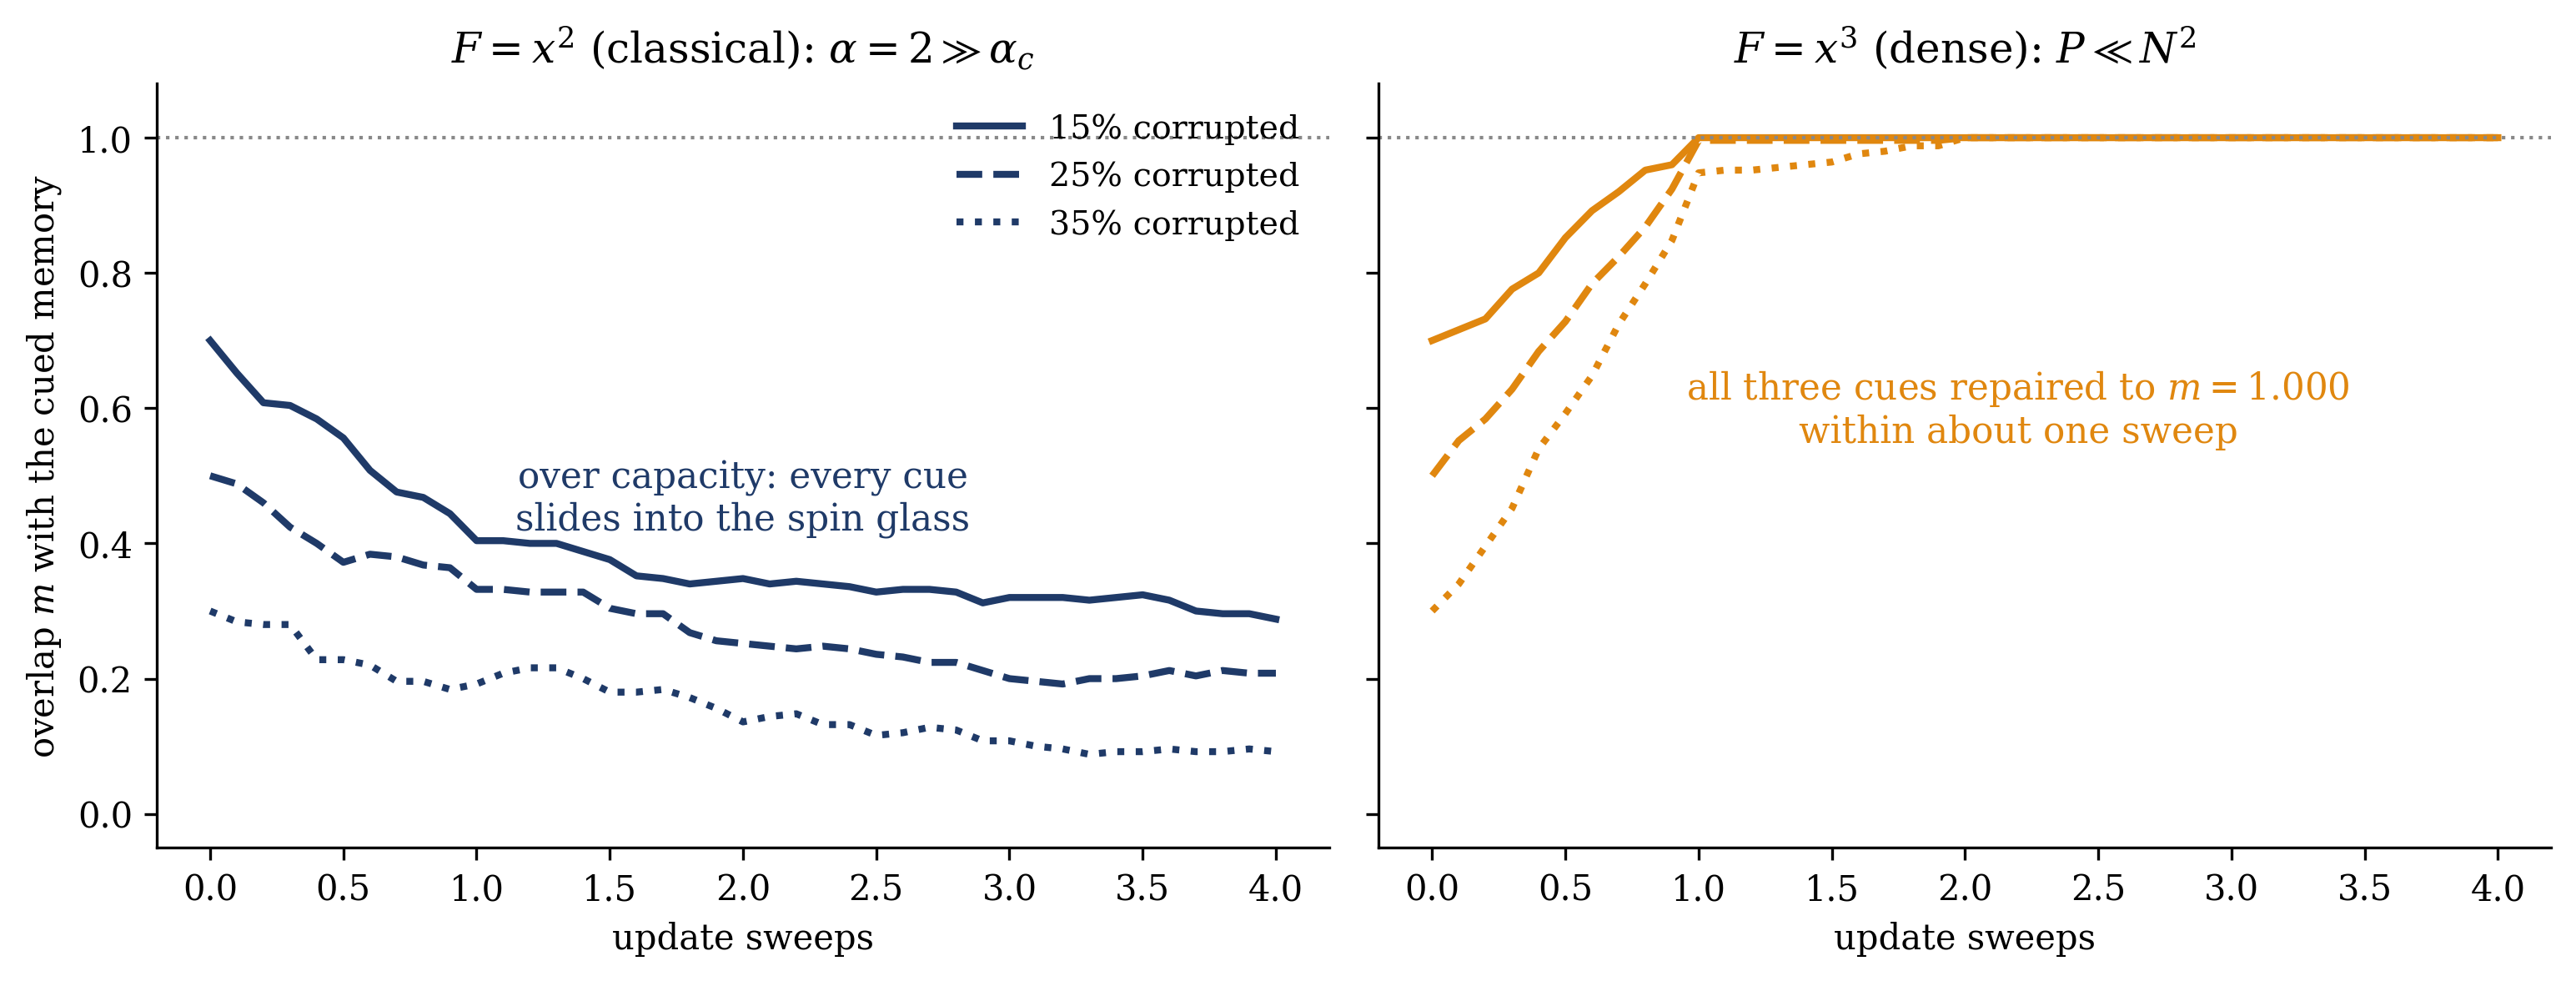
Figure 7.3 confirms the scaling numerically: a network of \(N = 500\) neurons loaded with \(P = 1000\) patterns — load \(\alpha = 2\), fourteen times past the classical wall — cued with corrupted memories under the classical update and under the cubic dense update Equation 7.2. The quadratic network, far past its capacity, drifts into the spin-glass phase from any starting point. The cubic network repairs a \(35\%\)-corrupted cue to \(m = 1.000\) in about one sweep.
Show code
N, P =500, 1000rng = np.random.default_rng(4)X = rng.choice([-1.0, 1.0], size=(P, N))def retrieve(n_power, f, sweeps=4, record_every=50): s = X[0].copy() flip = rng.choice(N, size=int(f * N), replace=False) s[flip] *=-1 o = X @ s # running overlaps xi^mu . s t, ms = [0.0], [o[0] / N] F =lambda x: x**n_powerfor sw inrange(sweeps):for step, i inenumerate(rng.permutation(N)): op = o + X[:, i] * (1- s[i]) # overlaps with s_i = +1 om = o - X[:, i] * (1+ s[i]) # overlaps with s_i = -1 si =1.0if (F(op) - F(om)).sum() >0else-1.0if si != s[i]: o += X[:, i] * (si - s[i]) s[i] = siif (step +1) % record_every ==0: t.append(sw + (step +1) / N); ms.append(o[0] / N)return t, msfig, axes = plt.subplots(1, 2, figsize=(10.4, 4.0), sharey=True)for ax, n_power, title inzip(axes, [2, 3], [r"$F = x^2$ (classical): $\alpha = 2 \gg \alpha_c$",r"$F = x^3$ (dense): $P \ll N^2$"]):for f, ls inzip([0.15, 0.25, 0.35], ["-", "--", ":"]): t, ms = retrieve(n_power, f) col = NAVY if n_power ==2else ORANGE ax.plot(t, ms, ls=ls, color=col, lw=2.0, label=rf"{int(f*100)}% corrupted") ax.axhline(1.0, color=GRAY, ls=":", lw=1) ax.set_title(title, fontsize=12) ax.set_xlabel("update sweeps"); ax.set_ylim(-0.05, 1.08)axes[0].set_ylabel(r"overlap $m$ with the cued memory")axes[0].text(2.0, 0.58, "over capacity: every cue\ndecays toward zero overlap", color=NAVY, fontsize=10.5, ha="center")axes[1].text(2.2, 0.55, r"all three cues repaired to $m = 1.000$""\nwithin about one sweep", color=ORANGE, fontsize=10.5, ha="center")axes[0].legend(frameon=False, fontsize=9.5, loc="upper right")fig.tight_layout(); plt.show()
Figure 7.3: The capacity laws, run rather than stated: \(N = 500\) neurons, \(P = 1000\) stored patterns — load \(\alpha = 2\), fourteen times the classical wall \(\alpha_c \approx 0.138\) — cued with a stored pattern corrupted in \(15\%\), \(25\%\), and \(35\%\) of its bits, under asynchronous energy-descent updates Equation 7.2. Left: the quadratic interaction (classical Hopfield, \(\sim N\) capacity): far over capacity, every cue drifts away from the memory into the spin-glass phase. Right: the cubic interaction (\(\sim N^2\) capacity, comfortably sufficient for \(P = 10^3 \ll N^2/(2 \cdot 3!! \ln N) \approx 7 \times 10^3\)): every cue is repaired to \(m = 1.000\) within about a sweep. Only the interaction function differs between the panels.
7.4 Capacity against robustness
Exponential capacity raises the obvious question: if a sharper \(F\) simply stores more, why would anyone ever use anything but \(F = e^x\)? The answer is visible in Figure 7.1: the deep, narrow well that lets a pattern ignore its neighbors is also a well that a corrupted cue can miss. Sharpening \(F\) shrinks the basins of attraction, and a memory with no basin is a lookup table that demands the exact key.
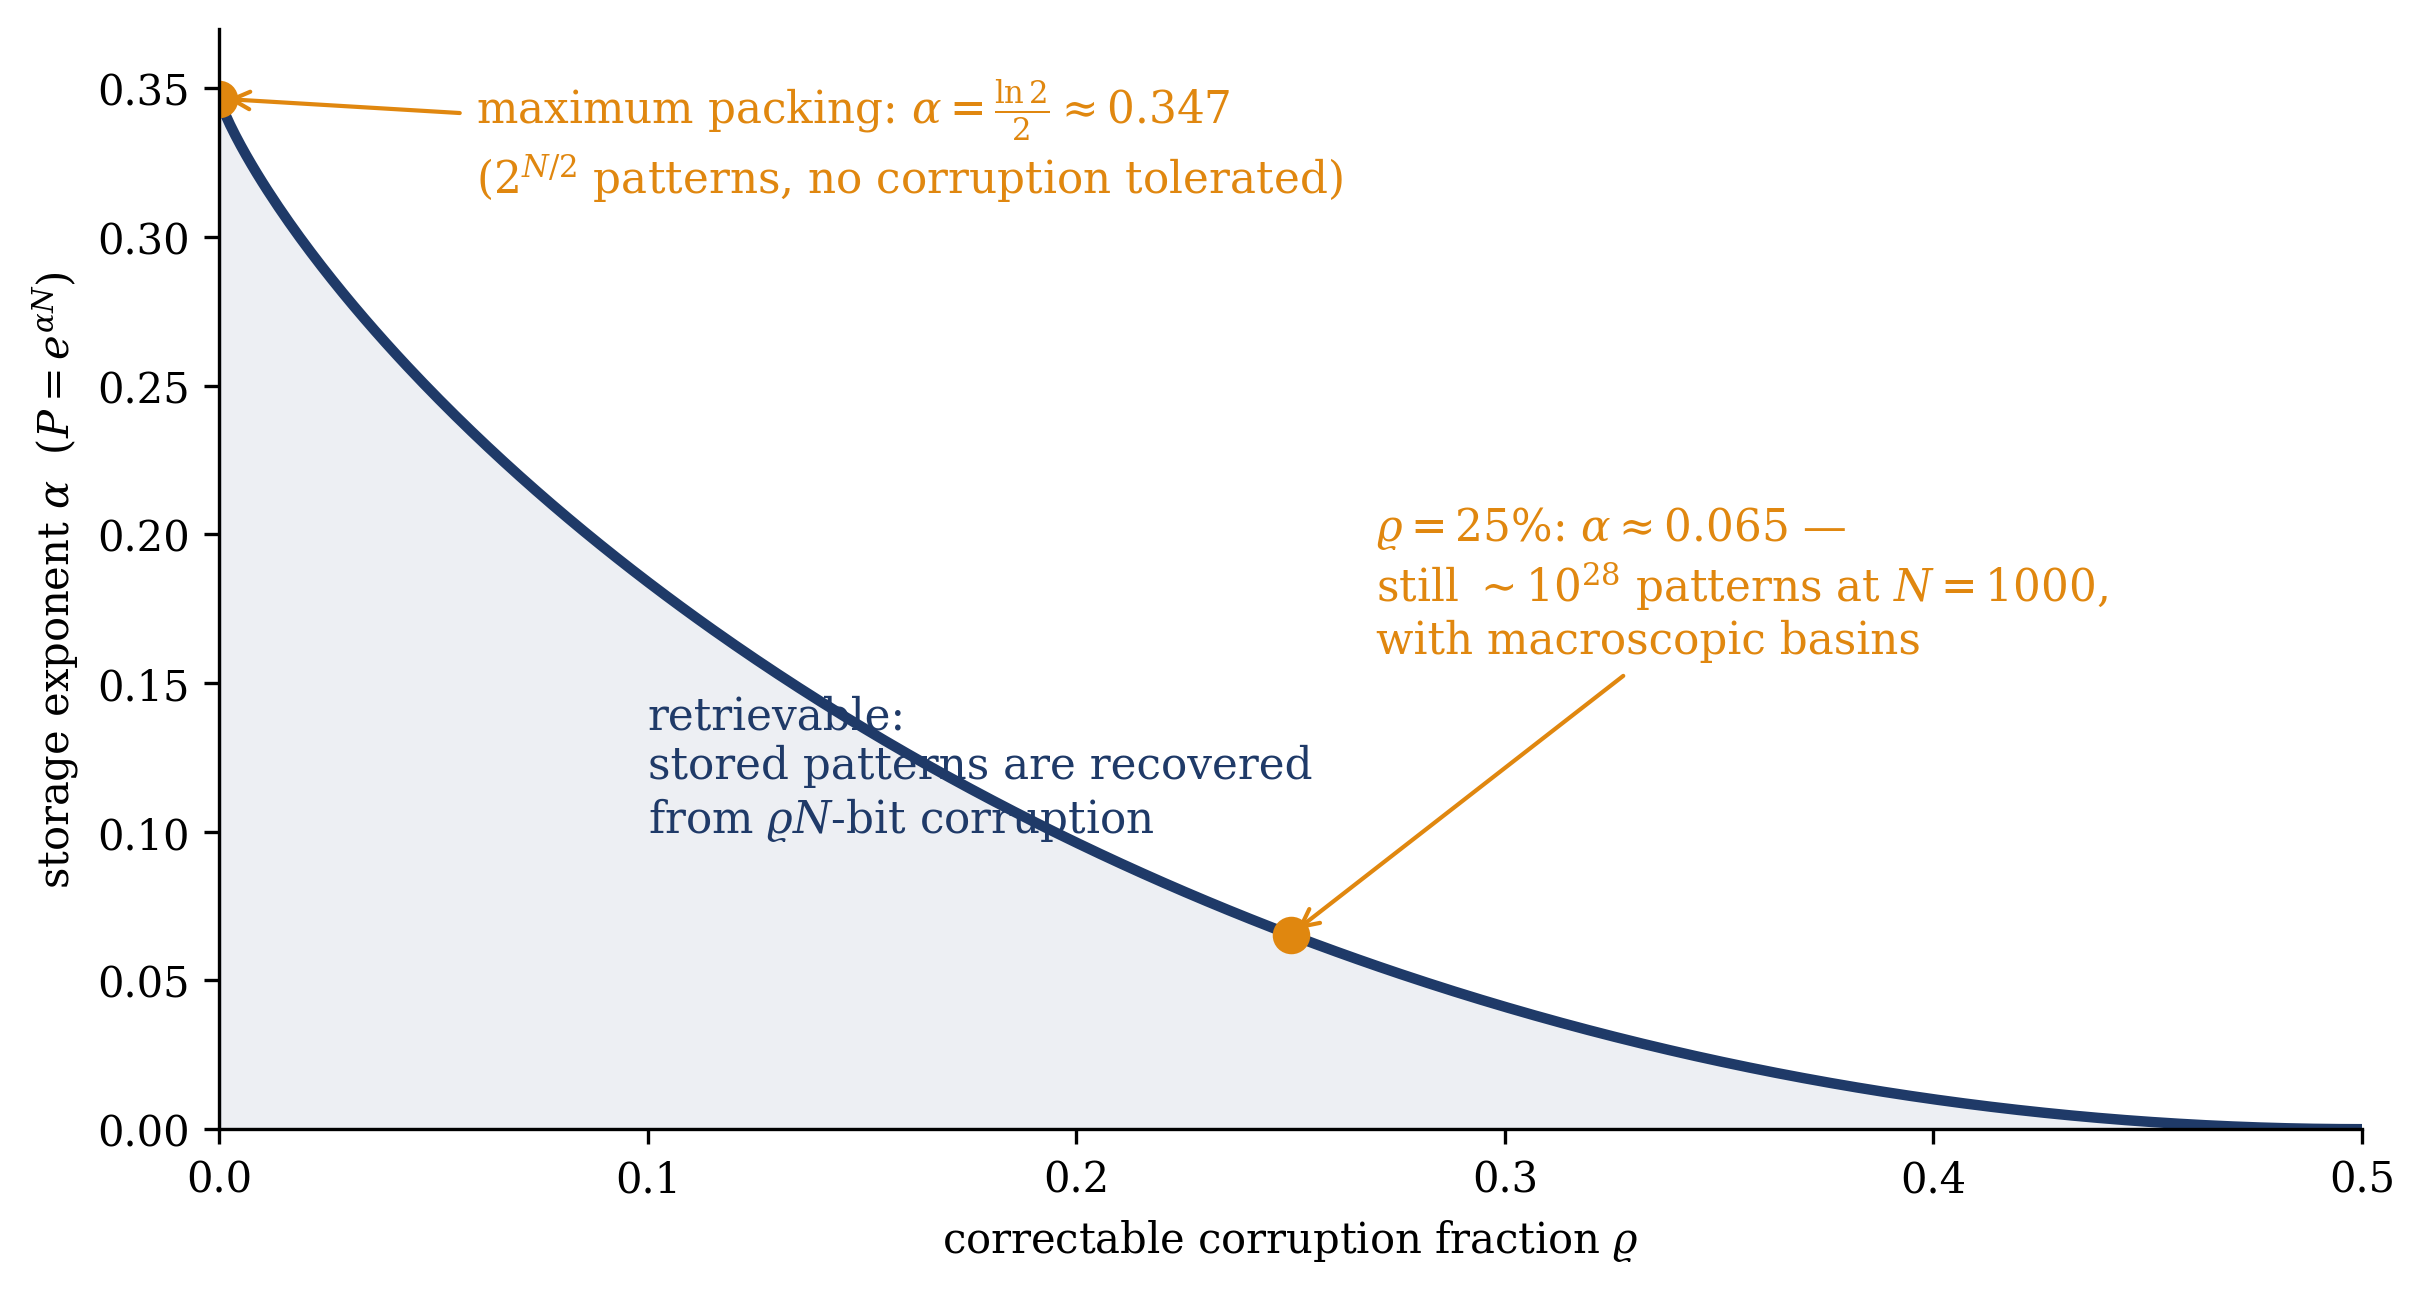
For the exponential model the tradeoff admits an exact formula. The theorem of Demircigil et al. (2017) is quantitative on exactly this point: storing \(P = e^{\alpha N}\) patterns, a cue corrupted in a fraction \(\varrho\) of its bits is repaired (in one step of the dynamics, with probability \(\to 1\)) provided
— a strictly decreasing function of \(\varrho\). Figure 7.4 plots the curve, and it makes the tradeoff quantitative. At \(\varrho \to 0\) (stability only, no error-correction demanded) the storage exponent reaches its maximum \(I(1)/2 = \ln 2/2 \approx 0.347\): the full \(2^{N/2}\). Demand that the memory still repair \(25\%\) corruption and the exponent drops to \(I(1/2)/2 \approx 0.065\) — at \(N = 1000\) still a comfortable \(\sim 10^{28}\) patterns, which is the sense of the paper’s “huge storage capacity”: it survives the demand for macroscopic basins. Pushed toward its ceiling, however, the storage squeezes the correctable fraction to zero, and at maximum packing the basins shrink to single configurations. Capacity and robustness are two ends of one rope.
Figure 7.4: The capacity–robustness tradeoff for the exponential interaction, exactly, from Equation 7.6: the largest storage exponent \(\alpha\) (capacity \(P = e^{\alpha N}\)) compatible with repairing a cue corrupted in a fraction \(\varrho\) of its bits. At \(\varrho = 0\) the exponent reaches \(\ln 2/2 \approx 0.347\) — the full \(2^{N/2}\), with no error-correction to spare. At \(\varrho = 0.25\) the exponent is \(\approx 0.065\): still \(\sim 10^{28}\) patterns at \(N = 1000\), with genuinely macroscopic basins. As \(\varrho \to 1/2\) (a cue barely better than chance) the storable exponent vanishes. More memories come at the cost of smaller basins.
The same tradeoff runs along the polynomial family, where Krotov and Hopfield made it a design principle. They trained the memories of a dense network by backpropagation on MNIST classification and inspected what the network learned as \(n\) varies (Krotov and Hopfield 2016). At small \(n\) (\(n = 2, 3\)) each memory’s contribution is broad, many memories respond to any input, and the learned memories are features: local strokes shared across digit classes, combined to recognize an object. At large \(n\) (\(n = 20, 30\)) the contributions are sharp, one or a few memories dominate, and the learned memories are prototypes: blurred whole-digit templates, each specialized to a single class. Krotov and Hopfield call the two ends the feature-matching and prototype regimes. The interaction function does more than set capacity: it selects what kind of memory you have, many shared parts or a few whole templates. The broad, cooperative response at small \(n\) comes from the same overlap of basins that produces the mixture states of Chapter 3, and the next lecture returns to such blends as the intended output of attention.
Trap
Exponential capacity has a cost. Sharpening \(F\) multiplies the wells and narrows every one of them: the correctable corruption shrinks as the storage exponent grows, with Equation 7.6 the exact relation. A network holding \(2^{N/2}\) patterns at maximum packing forgives essentially no corruption — capacity and robustness must always be quoted together.
Take-home 2
Sharper \(F\) means deeper, narrower basins — more memories, weaker error-correction, with the exact trade curve \(\alpha < I(1 - 2\varrho)/2\) for the exponential case. Along the polynomial family the same tradeoff appears as Krotov–Hopfield’s feature-vs-prototype regimes: at small \(n\) the learned memories are shared features, at large \(n\) whole-digit prototypes. Choose \(F\) for the task.
7.5 Toward the next lecture: continuous states, one-step retrieval
Consider once more the exponential filter, now with its steepness written as an inverse temperature, \(F(x) = \beta^{-1} e^{\beta x}\), so that \(F'(x) = e^{\beta x}\). The update reads only the sign of the effective field Equation 7.3, and dividing \(h_i\) by the total weight \(\sum_\nu e^{\beta\, \xi^\nu \cdot s}\), which is positive, leaves that sign unchanged. After the division the weights are Boltzmann weights over the \(P\) stored patterns, with the overlap playing the role of a negative energy:
Each stored pattern still casts the vote \(\xi_i^\mu\), and the normalized filter assigns it the softmax weight of its overlap, so the field is a softmax-weighted average of the stored patterns. In the language of Section 7.3, the signal is the weight \(w_\nu\) of the matching pattern and the crosstalk is the remaining weight \(1 - w_\nu\), spread over the others with random signs. At large \(\beta\) the weights approach a one-hot vector on the best-matching pattern (at \(\beta = 1\) and \(N = 100\) its typical advantage is the factor \(\sim 10^{39}\) of Figure 7.2), and the update returns that pattern; at small \(\beta\) the weights spread and the field averages several patterns. The inverse temperature \(\beta\) thus interpolates between exact one-winner retrieval and a blend of memories.
The next lecture modifies this energy in two ways. The states become continuous vectors rather than \(\pm 1\) spins — the energy built on the log-sum-exp of the overlaps, the smooth soft-maximum function — and retrieval, which today takes a sweep of single-spin flips, collapses to essentially one step: a single update carries a query to (a soft average of) the matching stored pattern, with the same \(\beta\) tuning exact retrieval against averaging (Ramsauer et al. 2021). That update rule is the subject of the next lecture.
All of this week’s sums run over the \(P\)stored patterns — and even \(2^{N/2}\) of them is a sum you index, not the \(2^N\) sum over configurations that constitutes \(Z\). Today’s normalizations live in Week 1’s tractable regime (a softmax over a finite menu, like the classifier of Section 1.6); nothing here needs, or computes, a partition function. \(Z\) is absent this week because retrieval never requires it; it returns when an energy must represent a normalized distribution — Week 3’s problem, and Module 2’s.
7.6 Example: the capacity ledger, and a familiar number
We evaluate every capacity law of Equation 7.5 on one network of \(N = 1000\) neurons, the size Week 2’s ledger used. The printed numbers are the pure scaling laws; for strict stability, the constants of Krotov and Hopfield (2016) lower the polynomial rows by about \(40\) for \(x^3\) and about \(1.5 \times 10^3\) for \(x^5\), which leaves the comparison across rows intact.
interaction \(F\)
capacity law
\(P_\text{max}\) at \(N = 1000\)
basins
\(x^2\) (classical)
\(\alpha_c N\)
\(\approx 138\)
wide; robust recall
\(x^3\)
\(\sim N^2\)
\(\sim 10^6\)
narrower
\(x^5\)
\(\sim N^4\)
\(\sim 10^{12}\)
narrower still
\(e^x\)
\(\sim 2^{N/2}\)
\(\sim 3 \times 10^{150}\)
macroscopic if\(\alpha\) backs off the ceiling (Equation 7.6)
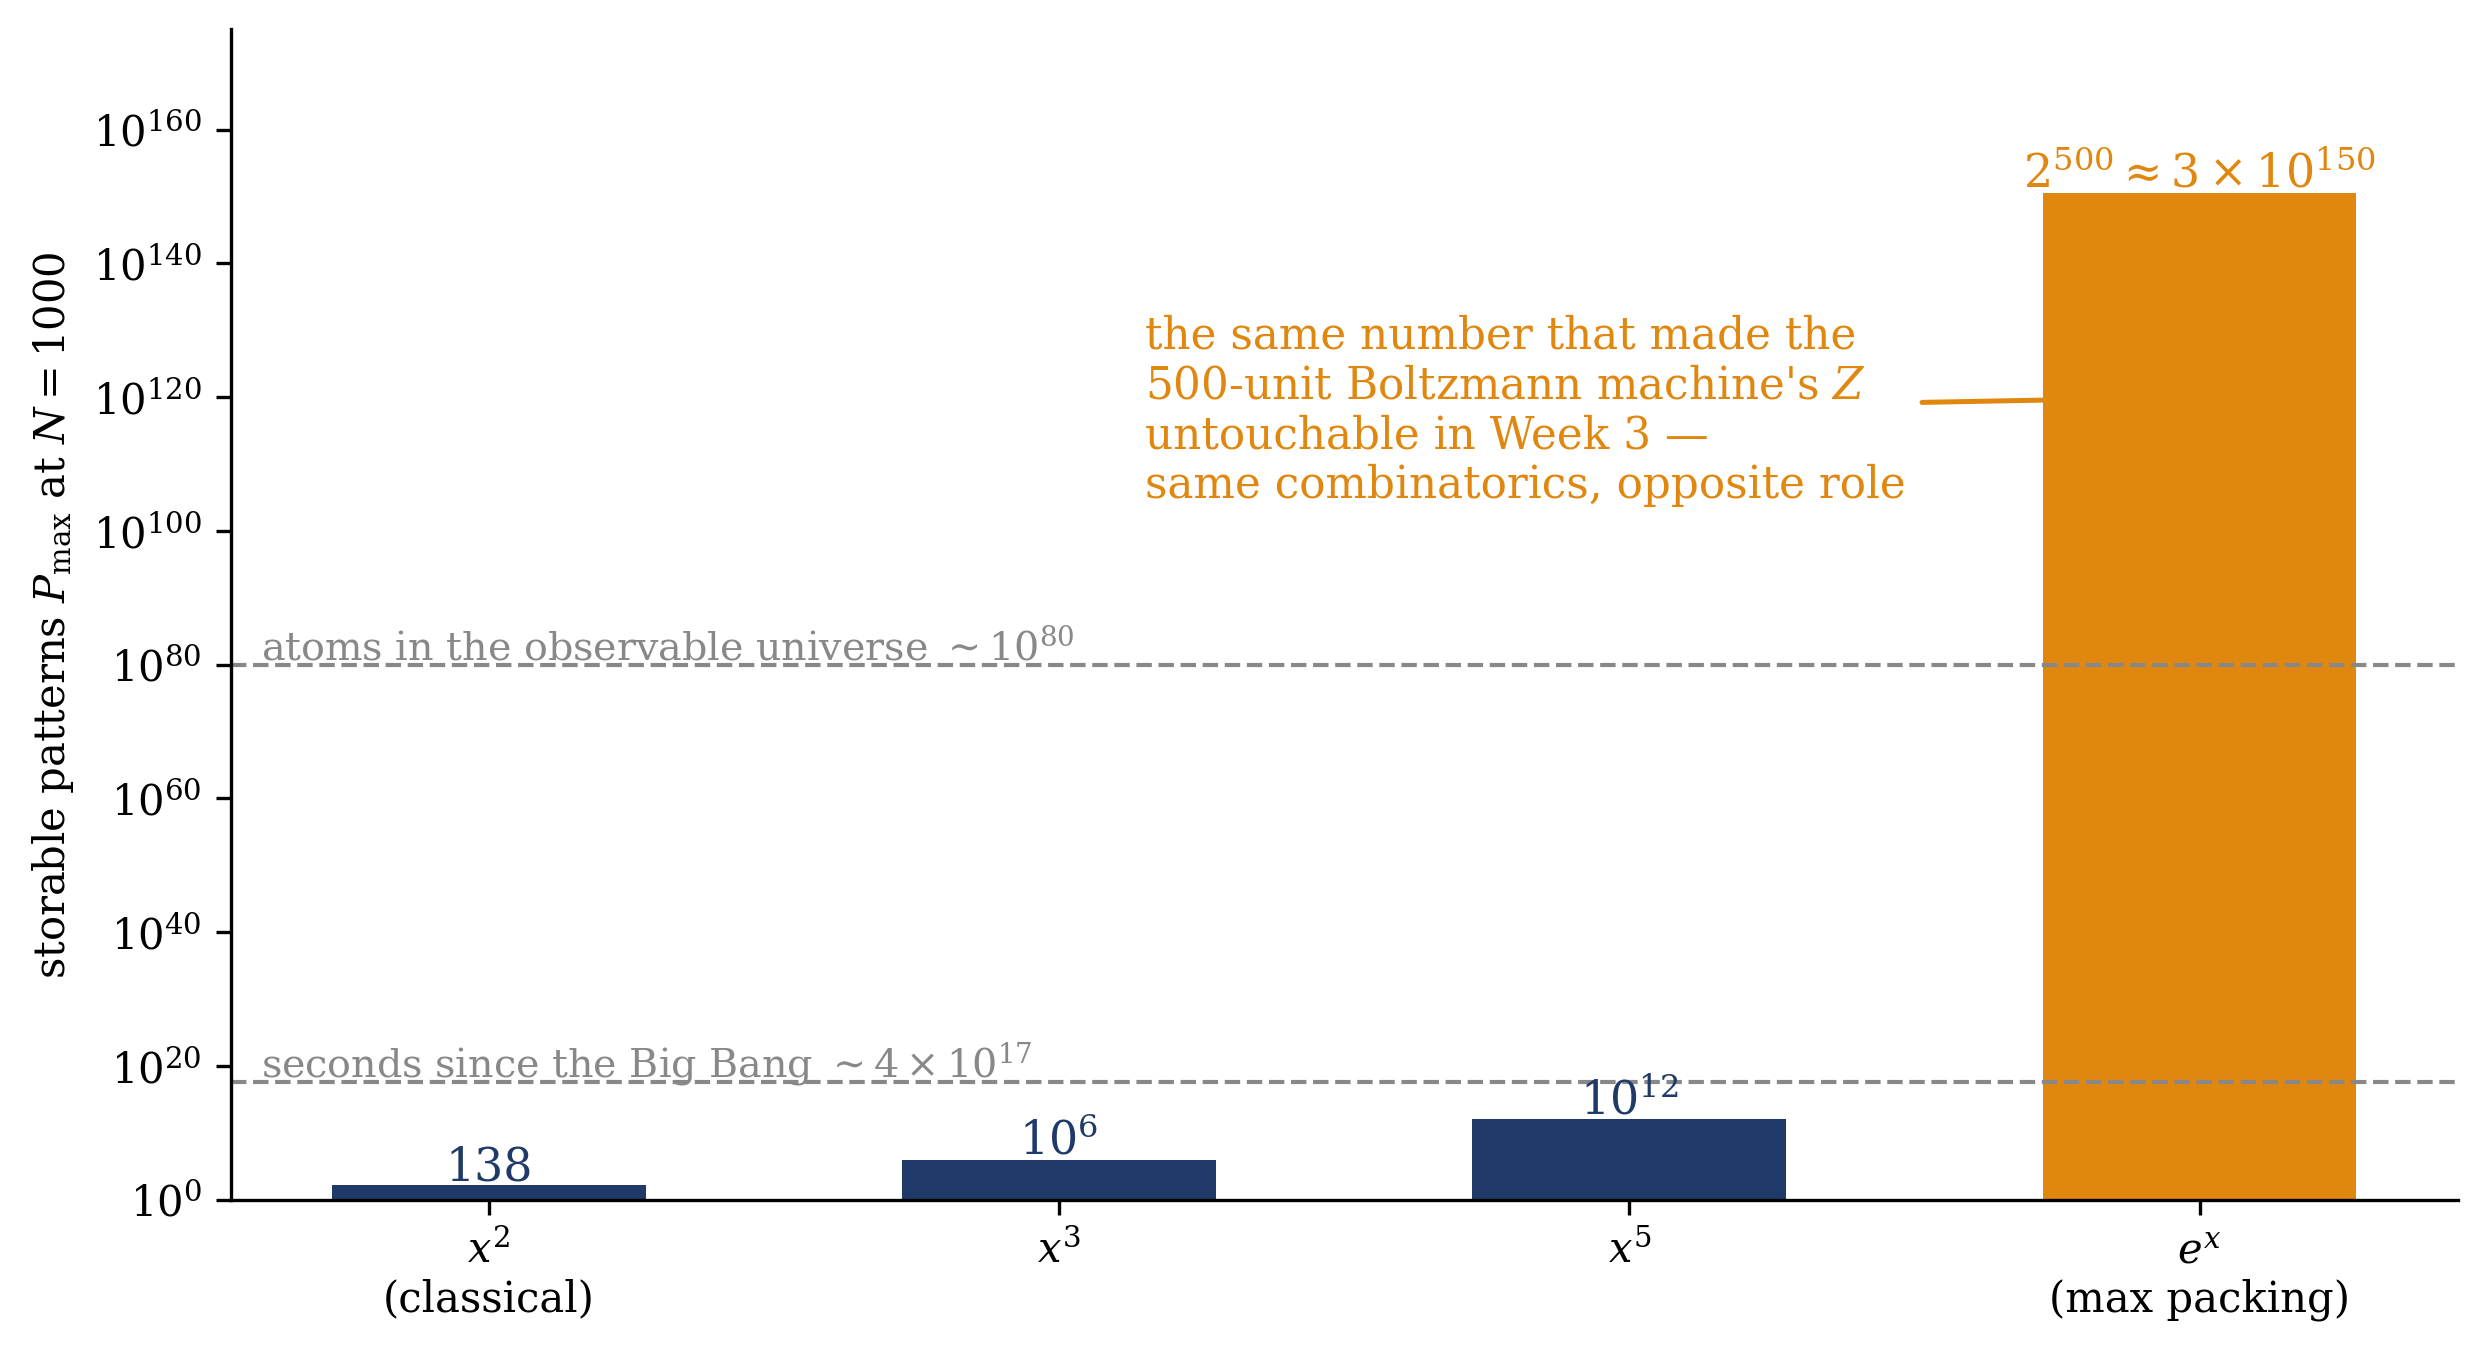
The last row’s number appeared before. In Week 3’s ledger (Section 5.7), a Boltzmann machine of \(500\) units had a partition function of \(2^{500} \approx 3 \times 10^{150}\) terms — more than the atoms of the observable universe, the number that made training hopeless. Today, a memory of \(1000\) neurons stores\(2^{500}\) patterns — numerically the same. The coincidence is structural: the exponential explosion of configuration space enters the denominator when you must normalize (Week 3’s problem) and the capacity when you get to store into it. Same combinatorics, opposite role. Figure 7.5 draws the four bars, with Week 3’s comparators included.
Show code
labels = [r"$x^2$""\n(classical)", r"$x^3$", r"$x^5$", r"$e^x$""\n(max packing)"]vals = [138, 1e6, 1e12, 2.0**500]fig, ax = plt.subplots(figsize=(8.4, 4.6))bars = ax.bar(labels, vals, color=[NAVY, NAVY, NAVY, ORANGE], width=0.55)ax.set_yscale("log")for lv, lab in [(4.4e17, r"seconds since the Big Bang $\sim 4\times10^{17}$"), (1e80, r"atoms in the observable universe $\sim 10^{80}$")]: ax.axhline(lv, color=GRAY, ls="--", lw=1) ax.text(-0.4, lv *8, lab, color=GRAY, fontsize=9.5)for i, v inenumerate(vals): txt ="138"if i ==0else (r"$10^{6}$"if i ==1else (r"$10^{12}$"if i ==2elser"$2^{500} \approx 3\times10^{150}$")) ax.text(i, v *8, txt, ha="center", color=NAVY if i <3else ORANGE, fontsize=11)ax.annotate("the same number that made the\n500-unit Boltzmann machine's $Z$\nintractable in Week 3", xy=(3, 1e120), xytext=(1.15, 1e105), color=ORANGE, fontsize=10.5, arrowprops=dict(arrowstyle="->", color=ORANGE, lw=1.2))ax.set_ylabel(r"storable patterns $P_\mathrm{max}$ at $N = 1000$")ax.set_ylim(1, 1e175)fig.tight_layout(); plt.show()
Figure 7.5: The capacity ledger at \(N = 1000\), on the log scale it demands. Four interaction functions, four capacity laws: \(138\) patterns (quadratic — Week 2’s wall), \(\sim 10^6\) (cubic), \(\sim 10^{12}\) (degree five), \(\sim 3 \times 10^{150}\) (exponential, at maximum packing \(2^{N/2}\)). The gray comparators are taken from Week 3’s ledger: the exponential memory stores more patterns than there are atoms in the observable universe — and its capacity, \(2^{500}\), is numerically identical to the count of terms that made the \(500\)-unit Boltzmann machine’s partition function intractable.
The fourth column qualifies the third. Beside every capacity, its basin: the quadratic network at low load repaired a \(49\%\)-corrupted cue (Section 3.6); the exponential network at maximum packing repairs essentially nothing, and restoring a \(25\%\) basin lowers the exponent by a factor of five. The two columns move in opposite directions and should always be read together.
The \(0.138\,N\) wall is a property of the quadratic energy; sharpening the interaction function raises the capacity from linear to exponential in \(N\).
Take-home 3
At \(N = 1000\): the quadratic memory holds \(138\) patterns, the cubic a million, the exponential \(2^{500} \approx 3 \times 10^{150}\) — numerically the same count of states that made Week 3’s partition function intractable. The exponential growth of configuration space enters the denominator when a model must be normalized, and the capacity when patterns are stored.
7.7 Toward the next lecture
The next lecture makes the states continuous, and the scaled-up retrieval rule turns out to be the attention mechanism of the transformer. That lecture also closes Module 1.
Demircigil, Mete, Judith Heusel, Matthias Löwe, Sven Upgang, and Franck Vermet. 2017. “On a Model of Associative Memory with Huge Storage Capacity.”Journal of Statistical Physics 168 (2): 288–99. https://doi.org/10.1007/s10955-017-1806-y.
Gardner, Elizabeth. 1988. “The Space of Interactions in Neural Network Models.”Journal of Physics A: Mathematical and General 21 (1): 257–70. https://doi.org/10.1088/0305-4470/21/1/030.
Krotov, Dmitry, and John J. Hopfield. 2016. “Dense Associative Memory for Pattern Recognition.” In Advances in Neural Information Processing Systems (NeurIPS). Vol. 29.
———. 2021. “Large Associative Memory Problem in Neurobiology and Machine Learning.” In International Conference on Learning Representations (ICLR).
Ramsauer, Hubert, Bernhard Schäfl, Johannes Lehner, Philipp Seidl, Michael Widrich, Thomas Adler, Lukas Gruber, et al. 2021. “Hopfield Networks Is All You Need.” In International Conference on Learning Representations (ICLR).