12Belief propagation: the cavity becomes an algorithm
Recommended reading
Core (~1 h).Mézard and Montanari (2009), Ch. 14 — belief propagation built from the cavity method, the Bethe free energy, and the physics/coding/inference unification; this lecture follows its logic. Alongside it, Yedidia, Freeman, and Weiss (2003) — the definitive statement of this lecture’s variational result, that BP fixed points are stationary points of the Bethe free energy, plus the generalized (region-graph) extensions we only name.
Optional background.Donoho, Maleki, and Montanari (2009) — AMP and its Onsager correction; Bayati and Montanari (2011) — the proof of AMP’s state evolution; Pearl (1988) — belief propagation in AI, in book form; Bethe (1935) — the approximation that named the free energy; Gallager (1962) — the same algorithm decoding codes, two decades before Pearl.
Prerequisite reminder. All of Chapter 11 — the cavity field Equation 11.1, the Onsager reaction term, the TAP equations, and the \(\sum_j J_{ij}^2\) verdict — plus Week 5’s mean-field functional. New content: messages on a graph, exactness on trees and its chain instance (the forward–backward algorithm), the Bethe free energy, the BP→TAP reduction, and AMP as message passing for the dense linear model.
12.1 Passing the cavity field
The previous lecture’s cavity field — the field on a spin computed in the cavity where that spin is removed — is, in structure, a message. Today the identification becomes precise. Compute the cavity field not once, as a correction, but recursively, along the edges of a graph: every node sends every neighbor its cavity estimate in that neighbor’s absence, each built from the estimates the node received from its other neighbors. Iterate to consistency. That is belief propagation, and on a tree it is not an approximation at all — it returns the exact marginals of a \(2^N\)-state distribution in a number of operations linear in \(N\). (What distinguishes a message from a marginal is the central point of the method.)
The algorithm has three independent origins, in fields that did not communicate. Bethe (1935) gave, in statistical physics, an approximation for alloys whose fixed point is, in retrospect, the same object — the “Bethe approximation” whose free energy we meet today. Gallager (1962) invented it in coding theory, as an iterative decoder for the error-correcting codes that were decades ahead of their hardware — the LDPC codes now used in 5G and Wi-Fi radios. And Pearl introduced it in artificial intelligence in 1982, consolidated in his 1988 book (Pearl 1988), as exact inference on the graphical models that organized modern probabilistic reasoning. The demonstration that the three are one algorithm, assembled in Mézard and Montanari (2009), is a direct statement of this course’s premise: physics, coding, and inference share their mathematics.
TAP’s reaction term was the right correction for a dense graph — the Plefka expansion said so. But the graphs of real inference problems are not all dense: they are sparse, structured, tree-like, loopy. What is the right correction for an arbitrary graph? Today’s answer is structural rather than perturbative: pass the cavity field along each edge and let the graph decide. On a tree the result is exact, and on a dense graph the messages collapse and their correction is the Onsager term.
Take-home 1
Belief propagation is the previous lecture’s cavity field, passed recursively along a graph’s edges: each node sends each neighbor its estimate in that neighbor’s absence. On a tree it returns the exact marginals.
12.2 Node beliefs versus edge messages
Week 5’s mean field tracked one number per node, the magnetization \(m_i\), and set all correlations to zero. Belief propagation tracks one number per directed edge: the message \(u_{k\to i}\), a different report for every recipient, because what \(k\) believes in \(i\)’s absence genuinely depends on who \(i\) is. That per-edge bookkeeping is exactly what lets correlation flow along the graph — and it is the previous lecture’s cavity distinction (\(m_j\) versus \(m_j^{(i)}\)), promoted from a second-order correction to the method’s primary variable.
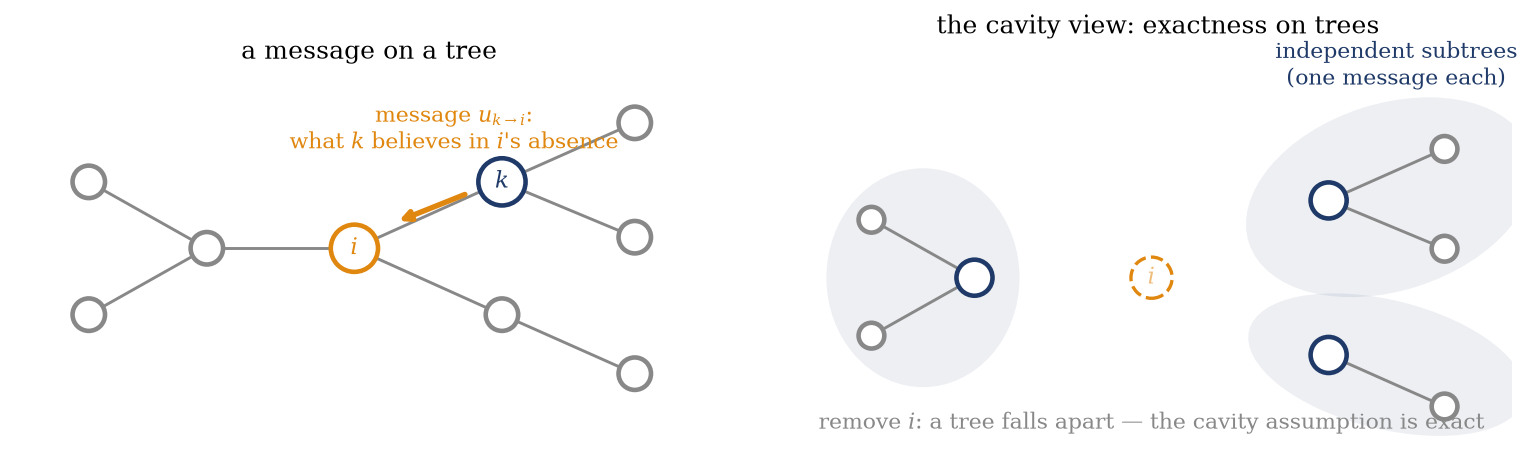
Figure 12.1 draws the construction. Left: a tree, with one message flowing along one directed edge — \(u_{k \to i}\), the influence of the subtree behind \(k\) on \(i\), condensed into a single effective field. Right: the reason trees are special. Remove node \(i\), and a tree falls apart — the neighbors’ subtrees are genuinely, exactly independent of one another, because the only path between them ran through \(i\). The cavity assumption that the previous lecture’s TAP invoked approximately (“the neighbors are independent in my absence”) is, on a tree, simply true. Exactness holds where removing a node disconnects the graph; correction terms appear where it does not.
Figure 12.1: Messages and cavities on a tree. Left: \(u_{k\to i}\) carries the influence of the subtree behind \(k\) on \(i\), condensed into one effective field: what \(k\) believes in \(i\)’s absence. Right: why trees are special — remove \(i\) and the tree falls apart into independent subtrees, one per neighbor, each summarized by one incoming message. The cavity assumption (“my neighbors are independent in my absence”) is exactly true on a tree; every loop in a graph is a way for it to fail.
12.3 Belief propagation on a pairwise model
Setup. A pairwise model on a graph — Ising, for concreteness and continuity: spins \(s_i = \pm 1\), couplings \(J_{ij}\) on the edges, fields \(h_i\), temperature \(T\) live as it has been all module. Write \(\partial i\) for the set of \(i\)’s neighbors. Two cavity objects are needed.
The cavity field, per edge. Let \(h_{i \to j}\) be the effective field on \(i\)with the edge to \(j\) cut. In the cavity, \(i\)’s remaining neighbors act on it independently (exactly so on a tree), so their contributions add. The previous lecture used the word for a different field: its \(h_i^\text{cav}\) is the field on\(i\), built from neighbors computed with \(i\) removed, and in today’s notation it reads \(h_i^\text{cav} \approx h_i + \sum_{k \in \partial i} u_{k\to i}\), the field inside the marginal below. Today’s directed field enters the previous lecture through its cavity magnetization instead, \(m_j^{(i)} = \tanh(\beta h_{j \to i})\).
The message. What does neighbor \(k\) contribute to \(i\)? Trace \(k\) out. Spin \(k\) sits in its own cavity field \(h_{k \to i}\) (its field from everything except\(i\)) and couples to \(i\) through \(J_{ki}\); summing over \(s_k = \pm 1\) produces an effective field on \(i\), and two lines of algebra give it in closed form. Define \(u_{k\to i}\) by \(\sum_{s_k} e^{\beta J_{ki} s_k s_i + \beta h_{k\to i} s_k} \propto e^{\beta u_{k \to i} s_i}\); taking the ratio of the \(s_i = \pm 1\) cases,
In words: the message is \(k\)’s cavity magnetization \(\tanh(\beta h_{k\to i})\), attenuated by the bond through \(\tanh(\beta J_{ki})\) — a weak bond transmits almost none of \(k\)’s belief, a strong bond passes it on nearly verbatim, and the \(\operatorname{artanh}\) converts the result back into field units so that messages can be added.
The recursion, and the marginals. The cavity field on \(i\) toward \(j\) collects the messages from all of \(i\)’s other neighbors,
and the definition closes on itself: messages determine cavity fields determine messages. Iterate to a fixed point (sweep the directed edges; damping helps on hard instances, as it did in the previous lecture). Once converged, the full marginal at a node combines all incoming messages:
A message is not a marginal. The message \(u_{k\to i}\) is a belief in \(i\)’s absence — computed from \(h_{k \to i}\), which deliberately excludes \(i\)’s own message to \(k\). The marginal \(m_i\) combines the messages from every neighbor. Keeping the two straight — always asking “who was removed?” — is precisely the discipline that prevents the double-counting the previous lecture was about.
Exactness on trees. The only assumption anywhere above is the cavity assumption: that \(i\)’s neighbors are statistically independent once \(i\) is removed. On a tree, removing \(i\)disconnects the neighbors’ subtrees — there is no path left between them — so the assumption is exactly true, at every node, at every step of the recursion. By induction from the leaves (whose cavity fields are just their local fields, no assumption needed), every message is exact, hence every marginal Equation 12.2 is exact. A \(2^N\)-sum inference problem, solved in \(\mathcal{O}(N)\) message updates, with no approximation: belief propagation on a tree is an exactly solvable algorithm. And the same paragraph locates the failure mode in advance: on a graph with loops, removing \(i\) does not disconnect its neighbors, so influence can travel around a loop and come back, and belief propagation has no term for it. The echo that the previous lecture subtracted is a different object. It runs along a single bond, \(i \to k \to i\), and is present on trees too; every message already leaves it out, on any graph, by excluding what \(i\) sent to \(k\), which is why dense BP reduces to TAP in Section 12.4.
The oldest special case: the chain. The simplest tree has no branching at all, and on it the theorem lands on an algorithm invented yet a fourth time, in yet a fourth field (Welling, Lu, and Holdijk 2026, ch. 6 on belief propagation). Consider a hidden Markov model, the workhorse of speech recognition and biological sequence analysis: hidden states \(z_t\) evolving under a transition law \(p(z_t \mid z_{t-1})\), each emitting an observation \(x_t\) with likelihood \(p(x_t \mid z_t)\). With the observations clamped, the posterior over the hidden sequence is a chain of pairwise factors,
The graph is a chain — a tree without branches — so belief propagation on it is exact, and it simplifies twice. Each interior node has exactly two neighbors, so “all neighbors but the recipient” is a single term and the recursion loses its product: messages simply sweep, once left to right and once right to left. And because \(z_t\) need not be binary, the message travels as a function over states rather than as one number — the Ising field of Equation 12.1 was the binary compression of this object, the \(\operatorname{artanh}\) algebra doing nothing more than storing a two-state message in a single scalar. Writing \(\alpha_t\) for the rightward message into \(z_t\) and \(\beta_t\) for the leftward one, the sweeps read
seeded at the ends by the leaf initialization of the induction above (\(\alpha_0 = p(z_0)\,p(x_0 \mid z_0)\), \(\beta_T = 1\)), and the exact posterior marginal combines the two incoming messages exactly as Equation 12.2 prescribes, \(p(z_t \mid x) \propto \alpha_t(z_t)\, \beta_t(z_t)\). These two sweeps are the forward–backward algorithm of hidden-Markov-model inference (Baum et al. 1970), running in speech recognizers and genome annotators for half a century, and the tree-exactness theorem is the reason it returns exact posteriors in \(\mathcal{O}(T)\) operations. The three origins of the opening section are therefore four: besides alloys (Bethe), codes (Gallager), and expert systems (Pearl), the structure appeared in time series with Baum, twelve years before Pearl; a chain is a simple enough tree that its users did not recognize the general message-passing structure.
12.4 The Bethe free energy — and BP contains TAP
Two results complete the theory: one gives BP a variational foundation, and the other connects it back to the previous lecture’s TAP equations.
BP is variational: the Bethe free energy. BP optimizes a functional. The argument starts from a tree identity: on a tree, the full Gibbs distribution factorizes exactly over its node and edge marginals,
where \(b_i, b_{ij}\) are the single-node and pairwise marginals and \(d_i\) is node \(i\)’s degree — each node over-counted once per extra edge and divided back out. Insert this form into \(F = \langle E \rangle + T \langle \log p \rangle\) and the free energy assembles itself from the beliefs alone:
with \(E_{ij} = -J_{ij} s_i s_j\) and \(E_i = -h_i s_i\). This is the Bethe free energy: the pairwise-correlation upgrade of Week 5’s mean-field functional, tracking beliefs on edges and not just nodes. Note where the approximation lives — the energy term is exact on any graph, because the Hamiltonian only ever touches pairs; it is the entropy whose node-and-edge counting is borrowed from the tree. On a tree, by the identity above, \(F_\text{Bethe}\) equals the true free energy exactly. Now treat the beliefs as free variables, constrained to normalize and to be consistent — each pairwise belief must marginalize to its nodes’ beliefs, \(\sum_{s_j} b_{ij}(s_i, s_j) = b_i(s_i)\) — and ask what stationarity delivers.
The constrained optimization runs as follows (Yedidia, Freeman, and Weiss 2003). First, attach a Lagrange multiplier \(\lambda_{j \to i}(s_i)\) to each marginalization constraint \(\sum_{s_j} b_{ij} = b_i\), one function per directed edge. Second, vary the pairwise belief: setting the derivative of the Lagrangian with respect to \(b_{ij}(s_i, s_j)\) to zero gives \(E_{ij} + T(\log b_{ij} + 1) - \lambda_{j \to i}(s_i) - \lambda_{i \to j}(s_j) = \text{const}\), i.e.
— a Boltzmann factor for the bond, tilted at each end by that end’s multiplier. Third, vary the node belief, whose entropy enters Equation 12.3 with the negative weight \(-(d_i - 1)\) — which flips the usual signs — while every incident edge contributes its multiplier:
On binary spins any function of \(s_i\) is affine, so each multiplier is one number per directed edge, \(\lambda_{j \to i}(s_i) = \mu_{j \to i}\, s_i\) up to a constant, and each node belief is fixed by one field, \(b_i(s_i) \propto e^{\beta H_i s_i}\). Per unit \(s_i\), node stationarity then reads
Nothing so far says what the multipliers are; the constraints decide that. Impose marginalization on the stationary pairwise belief \(b_{ij} \propto e^{\beta[J_{ij} s_i s_j + \mu_{j \to i} s_i + \mu_{i \to j} s_j]}\). Summing over \(s_j\) is a single spin in the field \(\mu_{i \to j}\) coupled to \(s_i\) through \(J_{ij}\), and the two-line \(\cosh\) trace of Section 12.3 applies unchanged: it turns the sum into an effective field on \(i\),
(For a leaf, \(d_i = 1\), the node condition reads \(\mu_{j \to i} = h_i\) directly, the empty-sum case of the second equation, consistent with the leaf-initialized recursion above.) Only now compare with Section 12.3. The multiplier \(\mu_{j \to i}\) obeys the recursion of the cavity field: it is the field on \(i\) with the edge to \(j\) cut, \(\mu_{j \to i} = h_{i \to j}\). The effective field \(u_{j \to i}\), computed from \(\mu_{i \to j} = h_{j \to i}\), is the message Equation 12.1, and \(H_i\) is the field of the BP marginal Equation 12.2. Every step can be read in reverse: from a BP fixed point, set \(\mu_{j \to i} = h_{i \to j}\) and build \(b_{ij}\) and \(b_i\) from the two Boltzmann forms above, and both stationarity conditions and every constraint hold. The correspondence is therefore one-to-one, and the marginalization constraints, imposed on the Bethe stationary beliefs, are the message equations:
\[
\boxed{\;\text{BP fixed points} \;=\; \text{stationary points of the Bethe free energy}\;}
\]
BP is variational (Yedidia–Freeman–Weiss)
One scope note: the negative node-entropy weight in Equation 12.3 means \(F_\text{Bethe}\) is in general not convex once the graph has more than one loop — stationary points need not be minima, which is one root of loopy BP’s convergence trouble. Module 2’s organizing principle — approximate the distribution by optimizing a functional — therefore extends through the entire week: mean field optimized a node functional (W5, with a bound), TAP optimized a truncated expansion (the previous lecture, without a bound), and BP optimizes the Bethe functional — exact on trees, and on loopy graphs a principled approximation (“loopy BP”) whose functional, like TAP’s, promises no side of the truth.
BP contains TAP. The reduction can now be derived at leading order. Put belief propagation on the previous lecture’s dense graph — every pair coupled, weakly, \(J \sim 1/\sqrt{N}\) — and expand. For weak bonds the message Equation 12.1 linearizes, \(u_{k\to i} \approx J_{ki}\, m_{k \to i}\), so the marginal reads \(m_i = \tanh(\beta[h_i + \sum_k J_{ki}\, m_{k\to i}])\): naive mean field, except that the inputs are cavity magnetizations. And the cavity magnetization differs from the full one by exactly the neighbor’s linear response to \(i\)’s removal:
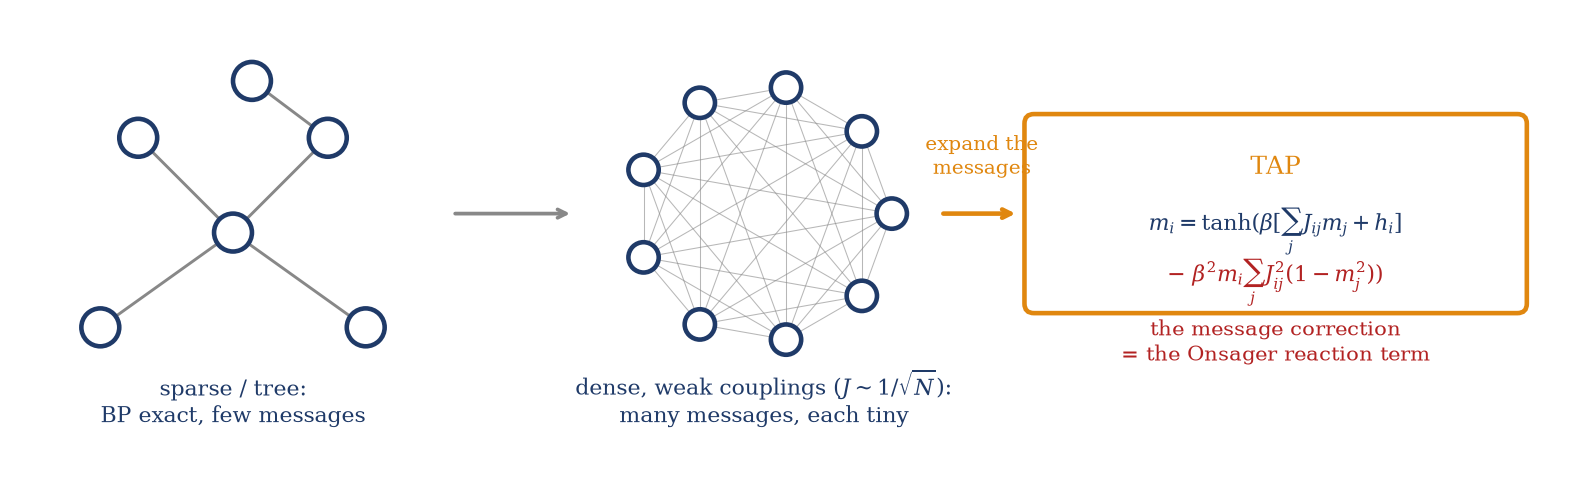
— the TAP equations Equation 11.3, term for term: the message correction is the Onsager reaction term (Figure 12.2; the systematic \(1/\sqrt N\) bookkeeping is not carried out here). On a sparse graph, BP is the richer object — a full message per edge; on a dense one, the many tiny messages collapse and what survives of them, collectively, is precisely the reaction term the previous lecture derived from the Plefka ladder.
Figure 12.2: From belief propagation to TAP. On a sparse graph (left) belief propagation carries a full message per edge and is exact on trees. Densify the graph — many couplings, each weak, \(J \sim 1/\sqrt{N}\) (center) — and the messages linearize and collapse: expanding the cavity magnetizations to leading order (right) yields exactly the TAP equations, the messages’ collective correction to naive mean field being the Onsager reaction term of Chapter 11.
Trap
BP is exact only on trees — and “works” is not “exact.” On loopy graphs, belief propagation may fail to converge, and its fixed points can return wrong marginals: a short loop lets a node’s influence travel around and return as fresh evidence, a returning influence that trees structurally lack and BP has no term for (the example below measures the damage growing with the loop’s coupling strength). The Bethe free energy is likewise not a bound off trees. Loopy BP nonetheless works well in many applications, including the decoding of error-correcting codes, but this is an empirical observation with known failure modes (short loops, strong couplings). Generalized BP on region graphs (Yedidia, Freeman, and Weiss 2003) repairs loops systematically; we name it here without developing it.
Take-home 2
On a dense weak-coupling graph the messages collapse, and the linearized cavity correction reproduces the TAP equations. On graphs with loops BP is often accurate but never guaranteed, and the Bethe free energy is not a bound.
12.5 AMP: TAP for the dense linear model
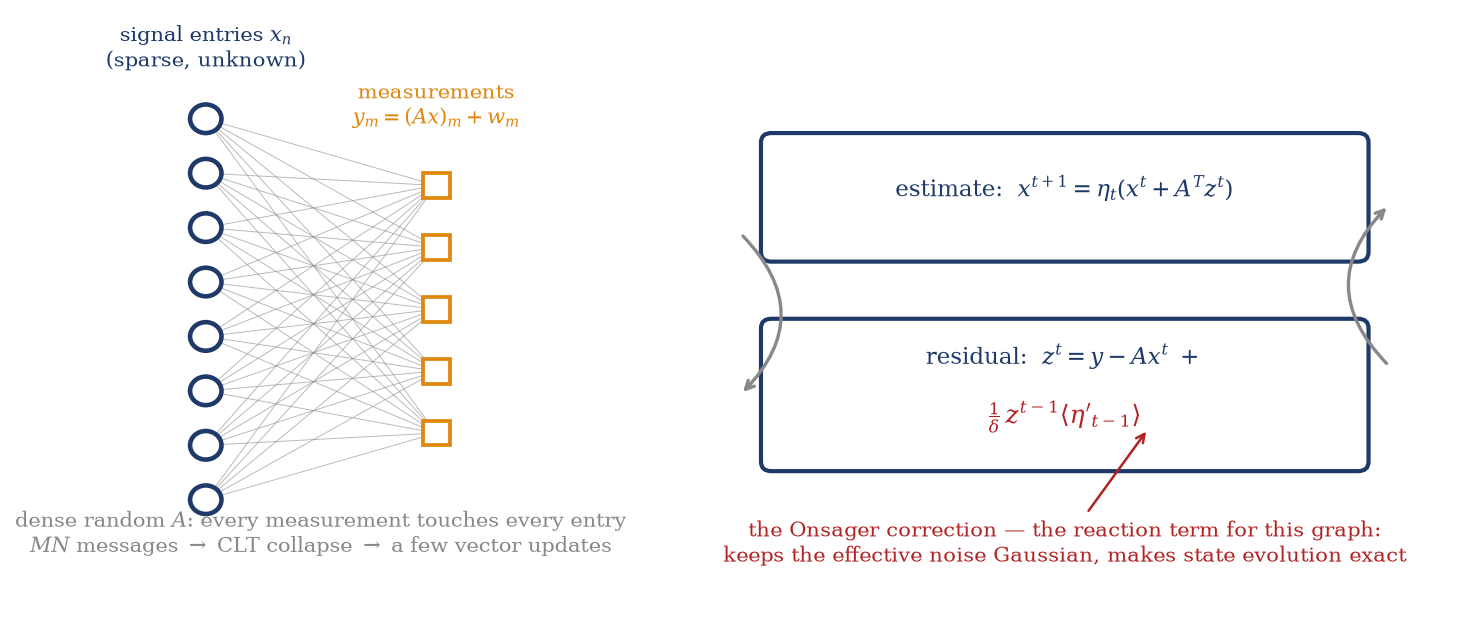
One more graph shows where this physics became a modern algorithm with a proof. The problem is compressed sensing: observe \(y = A x + w\), with \(A\) an \(M \times N\) dense random matrix (i.i.d. Gaussian entries), \(M < N\) measurements of an \(N\)-dimensional but sparse signal \(x\), noise \(w\). Sparsity makes the undersampled regression solvable; accelerated MRI is the textbook application. As an inference problem it lives on a dense bipartite factor graph (Figure 12.3, left): every measurement touches every signal entry, so literal BP would pass \(2MN\) messages per iteration — computationally impractical, but structurally familiar: a dense graph of weak individual influences, the regime in which messages collapse.
They do. Because each message is a sum of many weak, nearly independent contributions, the central limit theorem collapses the \(2MN\) messages onto a few vector updates — approximate message passing(Donoho, Maleki, and Montanari 2009). Its structure, stated here without derivation: iterate an estimate step, \(x^{t+1} = \eta_t(x^t + A^T z^t)\), where \(\eta_t\) is a scalar denoiser (for sparse signals, a soft-threshold that shrinks small entries to zero), and a residual step,
\[
z^t \;=\; y - A x^t \;+\; \underbrace{\frac{1}{\delta}\, z^{t-1}\, \big\langle \eta_{t-1}' \big\rangle}_{\text{the Onsager correction}},
\qquad \delta = M/N,
\]
AMP: the reaction term, again
whose last term is an extra piece of the residual, proportional to the previous residual and to the average sensitivity \(\langle \eta' \rangle\) of the denoiser — a memory term that naive iterative thresholding does not have. It is called, in the AMP literature and not by coincidence, the Onsager correction term, and its job is the previous lecture’s job: the estimate \(x^t\) was built from the residual, so the naive residual \(y - Ax^t\) is contaminated by the estimate’s own influence reflected back through \(A\). Subtracting it decorrelates the effective noise, keeping \(x^t + A^T z^t\) statistically equivalent to signal plus fresh Gaussian noise at every iteration — which is precisely what makes AMP analyzable: a one-dimensional recursion (state evolution) then predicts the algorithm’s error at every step, exactly in the large-system limit, a result proved by Bayati and Montanari (2011) for Gaussian matrices. Without the term the iteration converges more slowly, and its error is no longer predicted by state evolution.
Two further results connect AMP to the module’s themes. State evolution has a sharp threshold: below a critical measurement rate \(\delta\), recovery fails; above it, in the noiseless limit AMP reconstructs the signal essentially perfectly (with measurement noise the transition is a jump in the reconstruction error rather than to perfection) — a phase transition in an inference problem, the same order-parameter physics that magnetized Week 5’s ferromagnet and collapsed Week 2’s memory, now deciding whether an MRI scan can be undersampled.
Figure 12.3: AMP in one picture. Left: compressed sensing as a graphical model — a dense bipartite graph in which every measurement \(y_m\) touches every unknown signal entry \(x_n\); literal BP would pass \(2MN\) messages, but dense-and-weak is exactly the collapsing regime. Right: the collapsed algorithm (Donoho, Maleki, and Montanari 2009) — an estimate step through a denoiser \(\eta_t\), and a residual step carrying the Onsager correction (red): the memory term that subtracts the estimate’‘s own influence reflected back through the measurement matrix, keeps the effective noise Gaussian, and makes the algorithm’’s state-evolution analysis exact. The reaction term of Chapter 11 in signal-processing form.
Take-home 3
AMP is belief propagation for the dense compressed-sensing graph, collapsed by the CLT to vector updates. Its residual carries an Onsager correction term that decorrelates the effective noise and makes state evolution exact in the large-system limit, with a sharp recovery phase transition in the measurement rate.
12.6 Example: a tree, a loop, and a dense graph
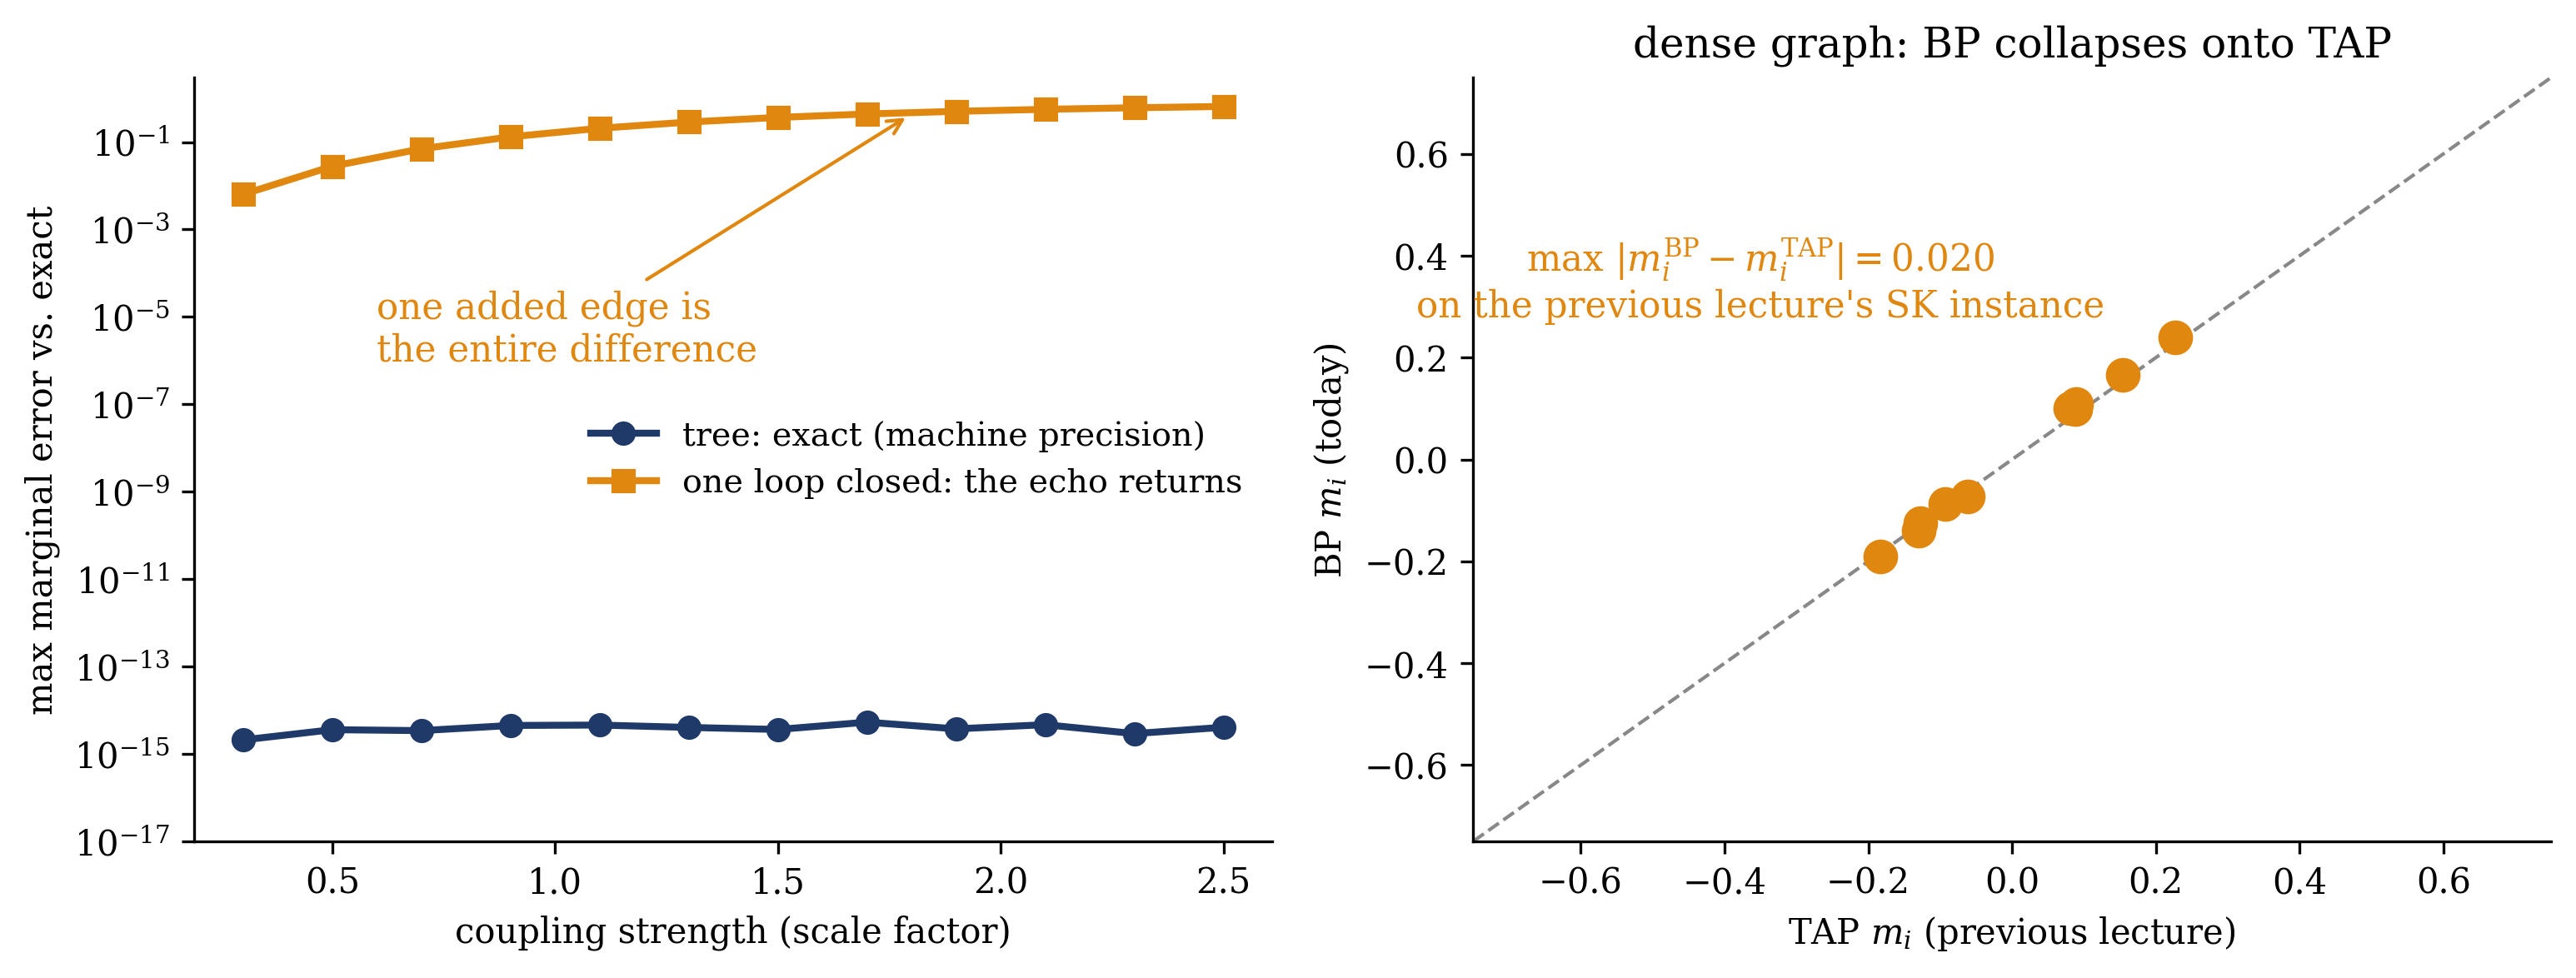
The three claims are tested numerically on three graphs (Figure 12.4). The tree: a seven-node Ising tree with random couplings and fields — BP converges (about fifty damped sweeps to \(10^{-14}\)) and matches the enumerated marginals to \(4 \times 10^{-15}\), machine precision. The loop: add one edge to that tree, closing a single cycle, and rerun. BP still converges here, but the marginals are now wrong — by \(0.006\) at weak coupling, growing to \(0.65\) as the loop’s couplings strengthen — while the tree’s error stays at machine zero throughout. The tree and the loop differ by a single edge. Around the loop a node’s influence returns as spurious evidence, more strongly as the loop’s couplings grow. The dense graph: run full BP on the previous lecture’s SK instance (\(N = 10\), the seed and fields of Section 11.5, \(T = 1.5\)) and set it beside the previous lecture’s TAP solution: the two agree to \(0.02\) across all ten spins — the BP→TAP reduction on the instance the previous lecture used to test TAP (both within \(0.03\) RMS of the enumerated truth).
Show code
def exact_marginals(N, edges, J, h, T): S = np.array([[(c >> i &1) *2-1for i inrange(N)] for c inrange(2**N)], dtype=float) E = np.zeros(2**N)for (a, b), Jab inzip(edges, J): E -= Jab * S[:, a] * S[:, b] E -= S @ h w = np.exp(-(E - E.min()) / T) p = w / w.sum()return (p[:, None] * S).sum(axis=0)def bp(N, edges, J, h, T, damp=0.5, iters=5000, tol=1e-14): beta =1.0/ T nbrs = {i: [] for i inrange(N)}for (a, b) in edges: nbrs[a].append(b); nbrs[b].append(a) u = {(a, b): 0.0for (a, b) in edges} | {(b, a): 0.0for (a, b) in edges} Jmap = {}for (a, b), Jab inzip(edges, J): Jmap[(a, b)] = Jmap[(b, a)] = Jabfor _ inrange(iters): delta =0.0for (k, i) in u: hki = h[k] +sum(u[(l, k)] for l in nbrs[k] if l != i) new = (1/ beta) * np.arctanh(np.tanh(beta * Jmap[(k, i)]) * np.tanh(beta * hki)) delta =max(delta, abs(new - u[(k, i)])) u[(k, i)] = (1- damp) * u[(k, i)] + damp * newif delta < tol:breakreturn np.array([np.tanh((h[i] +sum(u[(k, i)] for k in nbrs[i])) / T) for i inrange(N)])rng = np.random.default_rng(3)N =7tree = [(0, 1), (1, 2), (2, 3), (1, 4), (2, 5), (0, 6)]J0 = rng.uniform(-1, 1, len(tree))h0 = rng.normal(0, 0.3, N)loop = tree + [(3, 5)]Jl0 = np.append(J0, 0.8)scales = np.linspace(0.3, 2.5, 12)err_tree, err_loop = [], []for c in scales: err_tree.append(np.abs(bp(N, tree, c * J0, h0, 1.0)- exact_marginals(N, tree, c * J0, h0, 1.0)).max()) err_loop.append(np.abs(bp(N, loop, c * Jl0, h0, 1.0)- exact_marginals(N, loop, c * Jl0, h0, 1.0)).max())fig, (a1, a2) = plt.subplots(1, 2, figsize=(10.4, 4.0))a1.semilogy(scales, np.maximum(err_tree, 1e-16), "o-", color=NAVY, lw=2, label="tree: exact (machine precision)")a1.semilogy(scales, err_loop, "s-", color=ORANGE, lw=2, label="one loop closed")a1.annotate("one added edge", xy=(1.8, err_loop[7]), xytext=(0.6, 1e-6), color=ORANGE, fontsize=10.5, arrowprops=dict(arrowstyle="->", color=ORANGE, lw=1))a1.set_xlabel("coupling strength (scale factor)")a1.set_ylabel(r"max marginal error vs. exact")a1.set_ylim(1e-17, 3)a1.legend(frameon=False, fontsize=9.5, loc="center right")# dense: BP vs TAP on the W6L1 SK instancedef make_sk(N, Js, seed): r = np.random.default_rng(seed) Jm = r.normal(0, Js / np.sqrt(N), (N, N)); Jm = (Jm + Jm.T) / np.sqrt(2) np.fill_diagonal(Jm, 0.0)return Jm, r.normal(0, 0.2, N)def tap(Jm, h, T, damp=0.3, iters=20000): m = np.full(len(h), 0.01); J2 = Jm**2for _ inrange(iters): f = Jm @ m + h - (1/ T) * m * (J2 @ (1- m**2)) mn = np.tanh(f / T)if np.abs(mn - m).max() <1e-12:return mn m = (1- damp) * m + damp * mnreturn mN2 =10Jm, h2 = make_sk(N2, 1.0, 8)dense = [(i, j) for i inrange(N2) for j inrange(i +1, N2)]Jd = np.array([Jm[i, j] for (i, j) in dense])m_bp = bp(N2, dense, Jd, h2, 1.5, damp=0.3, iters=20000)m_tap = tap(Jm, h2, 1.5)a2.plot([-1, 1], [-1, 1], color=GRAY, ls="--", lw=1)a2.plot(m_tap, m_bp, "o", color=ORANGE, ms=9)a2.text(0.22, -0.48, rf"max $|m_i^{{\rm BP}} - m_i^{{\rm TAP}}| = {np.abs(m_bp-m_tap).max():.3f}$""\non the previous lecture's SK instance", color=ORANGE, fontsize=10.5, ha="center")a2.set_xlabel(r"TAP $m_i$ (previous lecture)"); a2.set_ylabel(r"BP $m_i$ (today)")a2.set_title("dense graph: BP collapses onto TAP", fontsize=12)a2.set_xlim(-0.75, 0.75); a2.set_ylim(-0.75, 0.75)fig.tight_layout(); plt.show()
Figure 12.4: The three claims, tested. Left: maximum marginal error of BP against exact enumeration, versus the strength of the couplings, on a seven-node tree (navy — flat at machine precision, \(\sim 10^{-15}\): the exactness theorem) and on the same graph with one added edge closing a single loop (orange — the error grows from \(0.006\) to \(0.65\) as the loop’s couplings strengthen: influence returning around the cycle, for which BP has no term). Right: on the dense graph, BP collapses onto TAP — the BP marginals of the previous lecture’s \(N = 10\) SK instance (Section 11.5, same seed, \(T = 1.5\)) against the previous lecture’s TAP solution, on the diagonal to within \(0.02\). Exact where removal disconnects, approximate where it does not, and TAP where the graph is dense.
The cavity field is a message: passed on a tree it is exact, and on a dense graph it reduces to TAP — message passing is mean field plus Onsager.
12.7 Outlook
The previous lecture derived one term — the Onsager reaction, a spin’s own reflected influence subtracted from its effective field — twice, and found its size governed by \(\sum_j J_{ij}^2\). Today the same cavity idea, run recursively, became an algorithm: exact on trees, variational through the Bethe free energy, and collapsing — on dense graphs — back onto the previous lecture’s equations, the messages’ correction being the reaction term. On the dense linear model the same term reappears in AMP’s residual update, where state evolution makes it exactly analyzable. Mean field, TAP, belief propagation, and AMP are therefore one construction at four levels of graph structure, with a progressively weaker set of guarantees — a bound (W5), an estimate (TAP), tree-exactness (BP), asymptotic exactness with state evolution (AMP) — each relaxed in exchange for broader applicability.
The two routes through disordered systems can now be compared. Week 2 introduced the replica method’s results; the previous lecture presented the cavity route as the alternative. The cavity route is the one that became algorithms: belief propagation decodes the LDPC codes of 5G and Wi-Fi (Gallager 1962), and AMP reconstructs undersampled signals with performance guarantees (Donoho, Maleki, and Montanari 2009; Bayati and Montanari 2011). The cavity method is how disordered-systems physics entered algorithm design.
The module now turns toward machine learning proper. Week 7 takes the variational thread to its ML destination: latent-variable models, the auxiliary-field (Hubbard–Stratonovich) transformation that introduces latents, and the variational autoencoder — where Week 5’s ELBO stops being a physicist’s identity and becomes the literal training loss of a deep generative network, together with its characteristic failure, posterior collapse. After that, Module 3 finally takes the other road out of the intractable \(Z\) — not approximating the distribution but sampling it — and the two roads will meet again in Module 4, where \(Z\) is neither approximated nor sampled but removed from the objective altogether.
Baum, Leonard E., Ted Petrie, George Soules, and Norman Weiss. 1970. “A Maximization Technique Occurring in the Statistical Analysis of Probabilistic Functions of Markov Chains.”The Annals of Mathematical Statistics 41 (1): 164–71. https://doi.org/10.1214/aoms/1177697196.
Bayati, Mohsen, and Andrea Montanari. 2011. “The Dynamics of Message Passing on Dense Graphs, with Applications to Compressed Sensing.”IEEE Transactions on Information Theory 57 (2): 764–85. https://doi.org/10.1109/TIT.2010.2094817.
Bethe, Hans A. 1935. “Statistical Theory of Superlattices.”Proceedings of the Royal Society of London A 150 (871): 552–75. https://doi.org/10.1098/rspa.1935.0122.
Donoho, David L., Arian Maleki, and Andrea Montanari. 2009. “Message-Passing Algorithms for Compressed Sensing.”Proceedings of the National Academy of Sciences 106 (45): 18914–19. https://doi.org/10.1073/pnas.0909892106.
Mézard, Marc, and Andrea Montanari. 2009. Information, Physics, and Computation. Oxford: Oxford University Press.
Pearl, Judea. 1988. Probabilistic Reasoning in Intelligent Systems: Networks of Plausible Inference. San Francisco: Morgan Kaufmann.
Welling, Max, Sirui Lu, and Lars Holdijk. 2026. Generative AI and Stochastic Thermodynamics: A Tale of Free Energies. Cambridge: Cambridge University Press. https://doi.org/10.1017/9781009709071.
Yedidia, Jonathan S., William T. Freeman, and Yair Weiss. 2003. “Understanding Belief Propagation and Its Generalizations.” In Exploring Artificial Intelligence in the New Millennium, edited by Gerhard Lakemeyer and Bernhard Nebel, 239–69. San Francisco: Morgan Kaufmann.