14The variational autoencoder: minimizing free energy by backpropagation
Recommended reading
Core (~1 h).Kingma and Welling (2014) — the founding VAE paper, and a rare case of a field-launching result that fits in eight pages: the ELBO estimator, the amortized encoder, and the reparameterization trick, all first stated here; read §2–§3 for the ideas and let the lecture carry the derivations. Alongside it, the ELBO and reparameterization sections of Kingma and Welling (2019), which retells the same construction with six years of hindsight.
Optional background.Rezende, Mohamed, and Wierstra (2014) — the simultaneous, independent invention of the same model from the generative-model side; that two groups arrived at the reparameterized ELBO within months of each other says something about how ready the pieces were. Higgins et al. (2017) — the β-VAE, which reweights the KL term and maps the tradeoff this lecture ends on. Dayan et al. (1995) — the Helmholtz machine, the recognition/generative-network ancestor, with Hinton in the author list once again. Mehta et al. (2019), the variational-autoencoder section, for the physicists’ telling in notation close to ours.
Prerequisite reminder. Week 5 in full — the variational free energy and the identity \(F_q = -\mathrm{ELBO}\) (Equation 9.4), the dictionary of Table 9.1, and the reverse-KL mode-seeking warning (Figure 9.3); the previous lecture’s latent-variable reframe Equation 13.4, \(p(x) = \int \mathrm{d}z\, p(z)\, p(x \mid z)\), with the Curie–Weiss latent as a decoupling field (Section 13.4); and basic feed-forward networks trained by SGD, from the companion Machine Learning and Physics course. New content: amortized inference, the reparameterization trick, and the VAE as the trainable form of the variational free energy.
14.1 The objective we already have
Module 2 ends with a trainable model. The previous lecture closed the circle it had opened: a latent-variable model \(p_\theta(x) = \int \mathrm{d}z\, p(z)\, p_\theta(x \mid z)\) couples its observations once the latent is integrated out, and for Curie–Weiss and probabilistic PCA the latent is exactly the field that decouples that coupling (Section 13.4). Learning such a model runs immediately into the posterior \(p_\theta(z \mid x)\), which is intractable for the same reason \(Z\) always was. Week 5 told us what to do about that: replace the posterior by a tractable \(q\), and optimize the evidence lower bound, which is nothing but the negative variational free energy (Equation 9.4). So the objective is settled. What is not settled is whether anyone can train it. Between the ELBO on the blackboard and a generative model fitted to a million images stand two concrete obstacles.
The first obstacle is bookkeeping that does not scale. Classical variational inference — and its ancestor, the EM algorithm — optimizes a separate variational distribution \(q\) for every data point: one free-standing optimization per image, re-run from scratch for any image not seen before. The second obstacle is a gradient that does not exist where we need it. The ELBO is an expectation over \(q_\phi(z \mid x)\), and its parameters \(\phi\) sit inside the distribution being sampled; back-propagation, which differentiates compositions of deterministic functions, cannot pass through the random draw of a \(z\).
In 2014, Kingma and Welling (2014) and, independently and nearly simultaneously, Rezende, Mohamed, and Wierstra (2014) proposed the same pair of fixes: replace the per-datapoint \(q\) by a single neural network — an encoder — that outputs the variational parameters for any \(x\) in one forward pass, and rewrite the random draw as a deterministic, differentiable function of the parameters plus external noise. The resulting model, the variational autoencoder (VAE), opened — together with generative adversarial networks, the same year — the modern era of deep generative modeling, which deep belief nets (Hinton, Osindero, and Teh 2006) had begun in 2006. The idea of pairing a recognition network with a generative network and training them together is the Helmholtz machine of Dayan et al. (1995), nearly two decades earlier, whose name refers both to Helmholtz’s view of perception as unconscious inference and to the Helmholtz free energy it optimizes.
The driving question of the lecture: how do you train Week 5’s free-energy minimization on a dataset too large to enumerate and a model too deep to solve?
Take-home 1
The ELBO (\(= -F_\mathrm{var}\), Week 5) is the right objective for a latent-variable model, but two obstacles block training it at scale: classical VI optimizes a fresh \(q\) per data point, and the gradient in the variational parameters cannot pass through a random sample. The VAE (Kingma and Welling 2014; Rezende, Mohamed, and Wierstra 2014) removes both — amortized inference (one encoder network for all data) and the reparameterization trick (a differentiable sampler) — turning free-energy minimization into a network trained by SGD.
14.2 Two obstacles, two fixes
Each obstacle has its own fix. Obstacle one, per-datapoint inference, is removed by amortization: a single network \(q_\phi(z \mid x)\) learns the map from data to variational parameters, so that inference on a new \(x\) costs one forward pass rather than one optimization. Obstacle two, non-differentiable sampling, is removed by reparameterization: the sample \(z\) is rewritten as a deterministic function of \(\phi\) and a parameter-free noise \(\varepsilon\), so that gradients flow through the sampler like through any other layer. The first provides scale; the second provides gradients; together they make the ELBO an objective like any other in deep learning — evaluated on minibatches, differentiated by backprop, optimized by SGD.
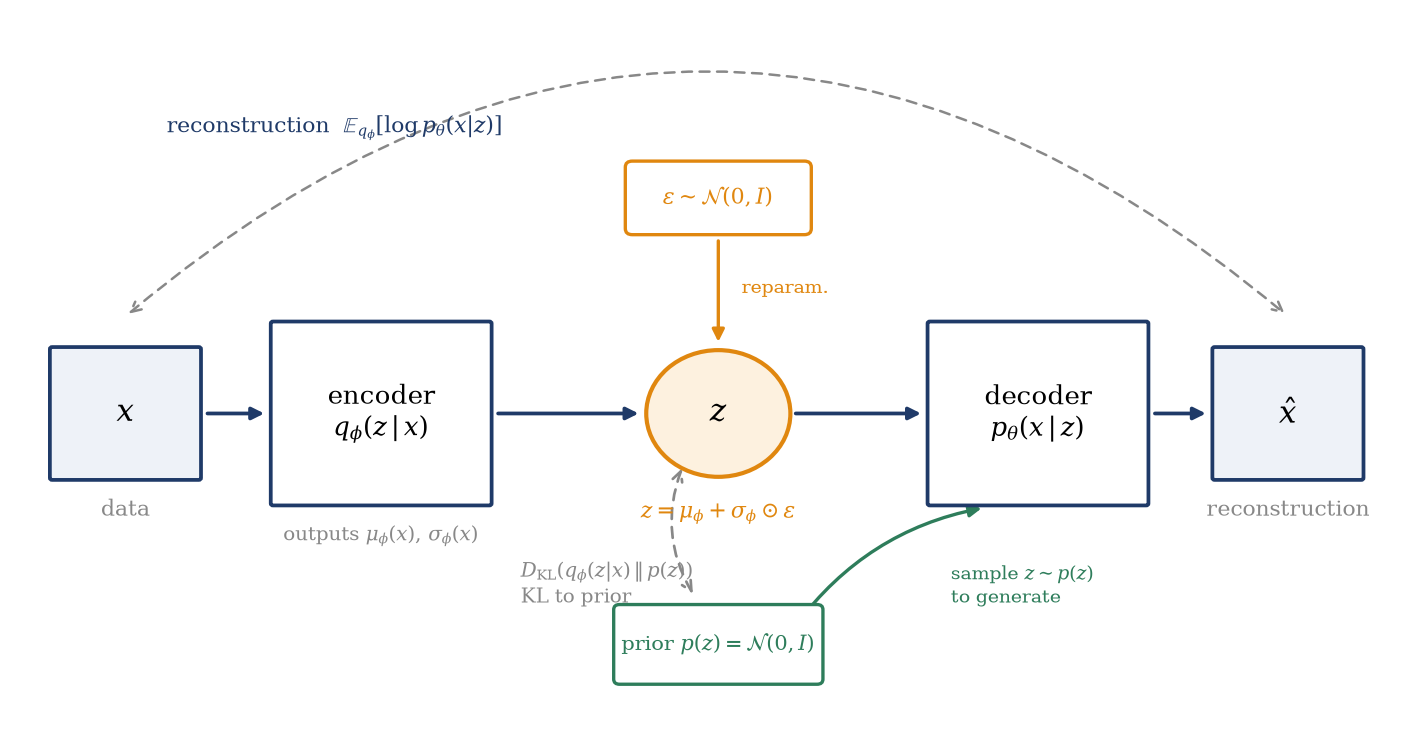
Figure 14.1 assembles the machine these fixes produce. Data \(x\) enters the encoder\(q_\phi(z \mid x)\), which outputs the mean \(\mu_\phi(x)\) and standard deviation \(\sigma_\phi(x)\) of a Gaussian over the latent; a sample \(z = \mu_\phi + \sigma_\phi \odot \varepsilon\) is drawn with external noise \(\varepsilon\) (\(\odot\) is the elementwise product); the decoder\(p_\theta(x \mid z)\) maps the latent back to a distribution over data space, scored against the input. Two terms tie the loop together: the reconstruction term compares the decoder’s output to \(x\), and a KL term holds the encoder’s distribution near the prior \(p(z) = \mathcal{N}(0, I)\). That KL term is what separates this machine from a plain autoencoder, and it is what lets the model generate: because every encoder output is pulled toward the same prior, a \(z\) drawn from that prior is a legitimate input to the decoder — the model can generate, not only compress. A deterministic autoencoder has no prior to sample from and cannot.
Figure 14.1: The variational autoencoder. Data \(x\) enters the encoder \(q_\phi(z \mid x)\), which outputs the variational parameters \(\mu_\phi(x), \sigma_\phi(x)\); the latent is sampled through the reparameterization \(z = \mu_\phi + \sigma_\phi \odot \varepsilon\) with external noise \(\varepsilon \sim \mathcal{N}(0, I)\) (orange), and the decoder \(p_\theta(x \mid z)\) scores the reconstruction against the input. The two loss terms are drawn in gray: the reconstruction term (top) compares \(\hat{x}\) to \(x\); the KL term (bottom) holds the encoder near the prior \(p(z) = \mathcal{N}(0, I)\). Generation (green) bypasses the encoder entirely: sample \(z \sim p(z)\) and decode.
Two parameter sets now live in one objective. Throughout, \(\theta\) denotes the decoder (generative) parameters and \(\phi\) the encoder (inference) parameters; the ELBO is optimized over both, but the two gradients raise entirely different issues — \(\nabla_\theta\) is routine, and \(\nabla_\phi\) is the subject of Section 14.4. The latent \(z\) has the structural role of the previous lecture’s auxiliary field (Chapter 13), a hidden common cause given which the observations are independent; unlike that field, its standard-normal prior and neural decoder are model choices rather than consequences of an interaction; \(\varepsilon\) is the reparameterization noise, not an energy scale. And we work at \(T = 1\) with the energy \(E(z) = -\log p_\theta(x, z)\) of Section 9.4, so the machine-learning literature’s \(\mathbb{E}_{q_\phi}[\,\cdot\,]\) is our \(\langle \cdot \rangle_{q_\phi}\); we keep the course’s angle brackets.
14.3 The ELBO in two terms
The ELBO as Week 5 left it is one number — a lower bound on the log-evidence. To train a network we need it in the two pieces that compete during training. Start from the master identity, Equation 9.4, specialized to an \(x\)-dependent variational family:
Since the gap on the right is a KL divergence, it is non-negative, and the ELBO bounds the evidence from below — that much is Week 5 verbatim. Now split the joint along the generative structure of Equation 13.4, \(p_\theta(x, z) = p(z)\, p_\theta(x \mid z)\), and regroup:
The two terms pull against each other, and their tension is the model. The reconstruction term is the log-likelihood the decoder assigns to the data given its inferred latent: it grows when \(z\) carries information about \(x\), so it pushes the encoder to be informative. The KL regularizer measures how far the encoder strays from the prior: it shrinks when \(z\) carries nothing, so it pushes the encoder to be uninformative. A trained VAE sits where the two forces balance — enough structure in the latent to reconstruct, little enough to keep the latent space close to the prior it must share with generation. And by Week 5’s identity, the whole expression is \(-F_\mathrm{var}(q_\phi)\): reconstruction plays the energy term, the KL plays the entropy-and-prior term, and we will make that mapping exact in Section 14.6 once the objective is trainable.
Amortization. As it stands, Equation 14.1 still expects a separate \(q\) per data point: classical variational inference would now optimize the variational parameters of \(q\) for this\(x\), then start over for the next one. That is one inner optimization per data point visited, and one more for every test image. The fix is to make the variational parameters a function of \(x\) and learn the function once:
where \(\mu_\phi(x)\) and \(\sigma_\phi(x)\) are the outputs of one neural network with weights \(\phi\). This is amortized inference: the inference effort is spent once, during training, and thereafter every data point — including data never seen — gets its approximate posterior in a single forward pass. The trade-off is explicit. A single network cannot match the optimal per-datapoint \(q\) on every \(x\), so the amortized ELBO sits below what classical VI could reach; that shortfall is the amortization gap, distinct from the approximation gap \(D_\mathrm{KL}(q_\phi \| p_\theta(z \mid x))\) of any restricted family. The two gaps stack — the family’s first, then the function’s — and both reappear in the traps below.
The objective now scales, but it is not yet differentiable where it matters: the reconstruction term is an average over \(q_\phi(z \mid x)\), and training the encoder needs \(\nabla_\phi\) of that average. That gradient is the subject of the next section.
14.4 The reparameterization trick
The problem, stated precisely: we need \(\nabla_\phi \langle f(z) \rangle_{q_\phi}\), the gradient of an expectation with respect to the parameters of the distribution being averaged over. Backprop differentiates deterministic compositions; a sample \(z \sim q_\phi\) is not one. There is a classical estimator for exactly this object, and its failure is what makes the trick necessary. Differentiate the integral directly and insert \(\nabla_\phi q_\phi = q_\phi \nabla_\phi \log q_\phi\):
This is the score-function (or REINFORCE) estimator: unbiased and universal, since it never differentiates \(f\) and \(f\) may be a black box, but for our purposes far too noisy. The reason is structural: the estimator multiplies the value of \(f\) by the score, so its fluctuations track the magnitude of \(f\) across the whole distribution rather than the local sensitivity of \(f\) to \(\phi\); every irrelevant fluctuation of \(f\) enters at full strength. Baselines and control variates tame it somewhat, but the variance grows with the dimension of \(z\) (the example below measures the growth), and deep latent models sit exactly where it hurts.
The reparameterization trick replaces value-times-score by an actual derivative. For the Gaussian encoder of Equation 14.2, write the sample as a deterministic map applied to parameter-free noise:
which leaves the distribution of \(z\) unchanged but relocates the randomness: the expectation is now over a fixed distribution, and the parameters sit inside the integrand, where \(\nabla_\phi\) can reach them,
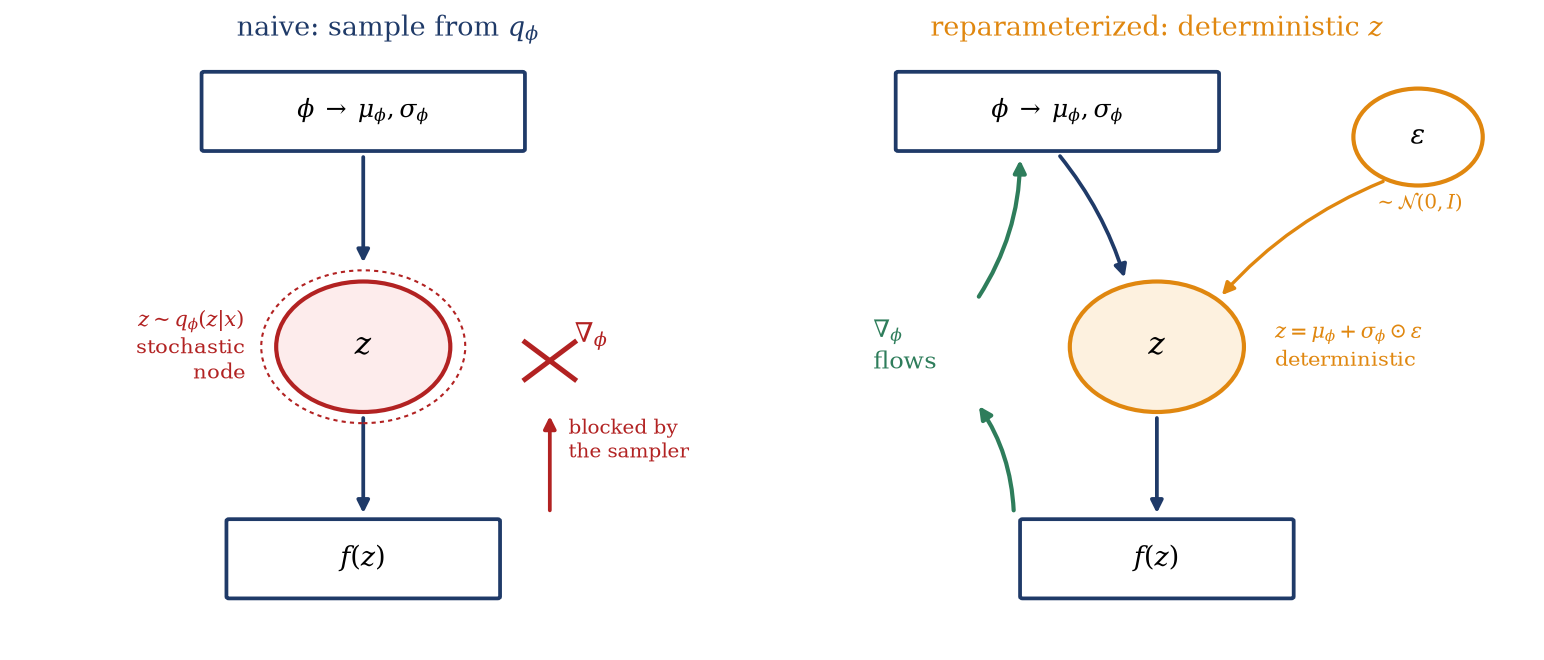
The sampler has become a differentiable layer (Figure 14.2): forward, draw \(\varepsilon\) and compute \(z\); backward, gradients flow through \(\mu_\phi\) and \(\sigma_\phi\) by the chain rule, exactly as through any affine layer with an input. This pathwise gradient uses \(\nabla_z f\) — the local slope, not the global value — and its variance is correspondingly small; one draw of \(\varepsilon\) per data point is standard practice and usually enough. The trick has one requirement: the latent must admit such a deterministic-map-plus-fixed-noise form, which continuous families do and discrete ones do not — for discrete latents one falls back on score-function estimators or the Gumbel-softmax relaxation, which we name and set aside.
Figure 14.2: The enabling idea as two computation graphs. Left: sampling \(z\) directly from \(q_\phi(z \mid x)\) makes \(z\) a stochastic node, and the backward pass cannot cross it — the gradient in \(\phi\) is blocked at the sampler. Right: the reparameterized graph. The noise \(\varepsilon \sim \mathcal{N}(0, I)\) enters as an input, \(z = \mu_\phi + \sigma_\phi \odot \varepsilon\) is a deterministic node, and \(\nabla_\phi\) flows from \(f(z)\) back through \(\mu_\phi, \sigma_\phi\) (green) by ordinary backpropagation.
The KL term is analytic. The second term of Equation 14.1 needs no estimator at all: for a Gaussian encoder against the standard-normal prior it is a closed-form function of the encoder outputs. Per latent dimension, with \(q = \mathcal{N}(\mu, \sigma^2)\) and \(p = \mathcal{N}(0, 1)\),
Assemble the objective. Estimate the reconstruction term by Monte Carlo over \(\varepsilon\) — a single draw per data point — take the KL in closed form, and average over a minibatch:
maximized over \((\theta, \phi)\) jointly by SGD. The form of the reconstruction term follows from the decoder’s likelihood: a Bernoulli decoder (binarized images) makes it a binary cross-entropy, a Gaussian decoder makes it a mean-squared error up to constants — the standard losses of supervised learning, reappearing as likelihood choices. Trained, the network is two machines in one: a generative model (draw \(z \sim \mathcal{N}(0, I)\), decode) and a representation learner (encode \(x\), keep \(z\)). Amortization made the objective scale; reparameterization made it differentiable; with both, Week 5’s free-energy minimization is a network trained by gradient descent.
Take-home 2
The score-function estimator is unbiased but tracks the value of \(f\), and its variance grows with latent dimension. Reparameterization moves the randomness onto a fixed distribution, so the gradient uses the slope \(\nabla_z f\) instead, with low variance and one noise draw per data point. With the closed-form Gaussian KL (Equation 14.4), the VAE objective (Equation 14.5) trains by ordinary SGD.
14.5 Example: two estimators of one gradient
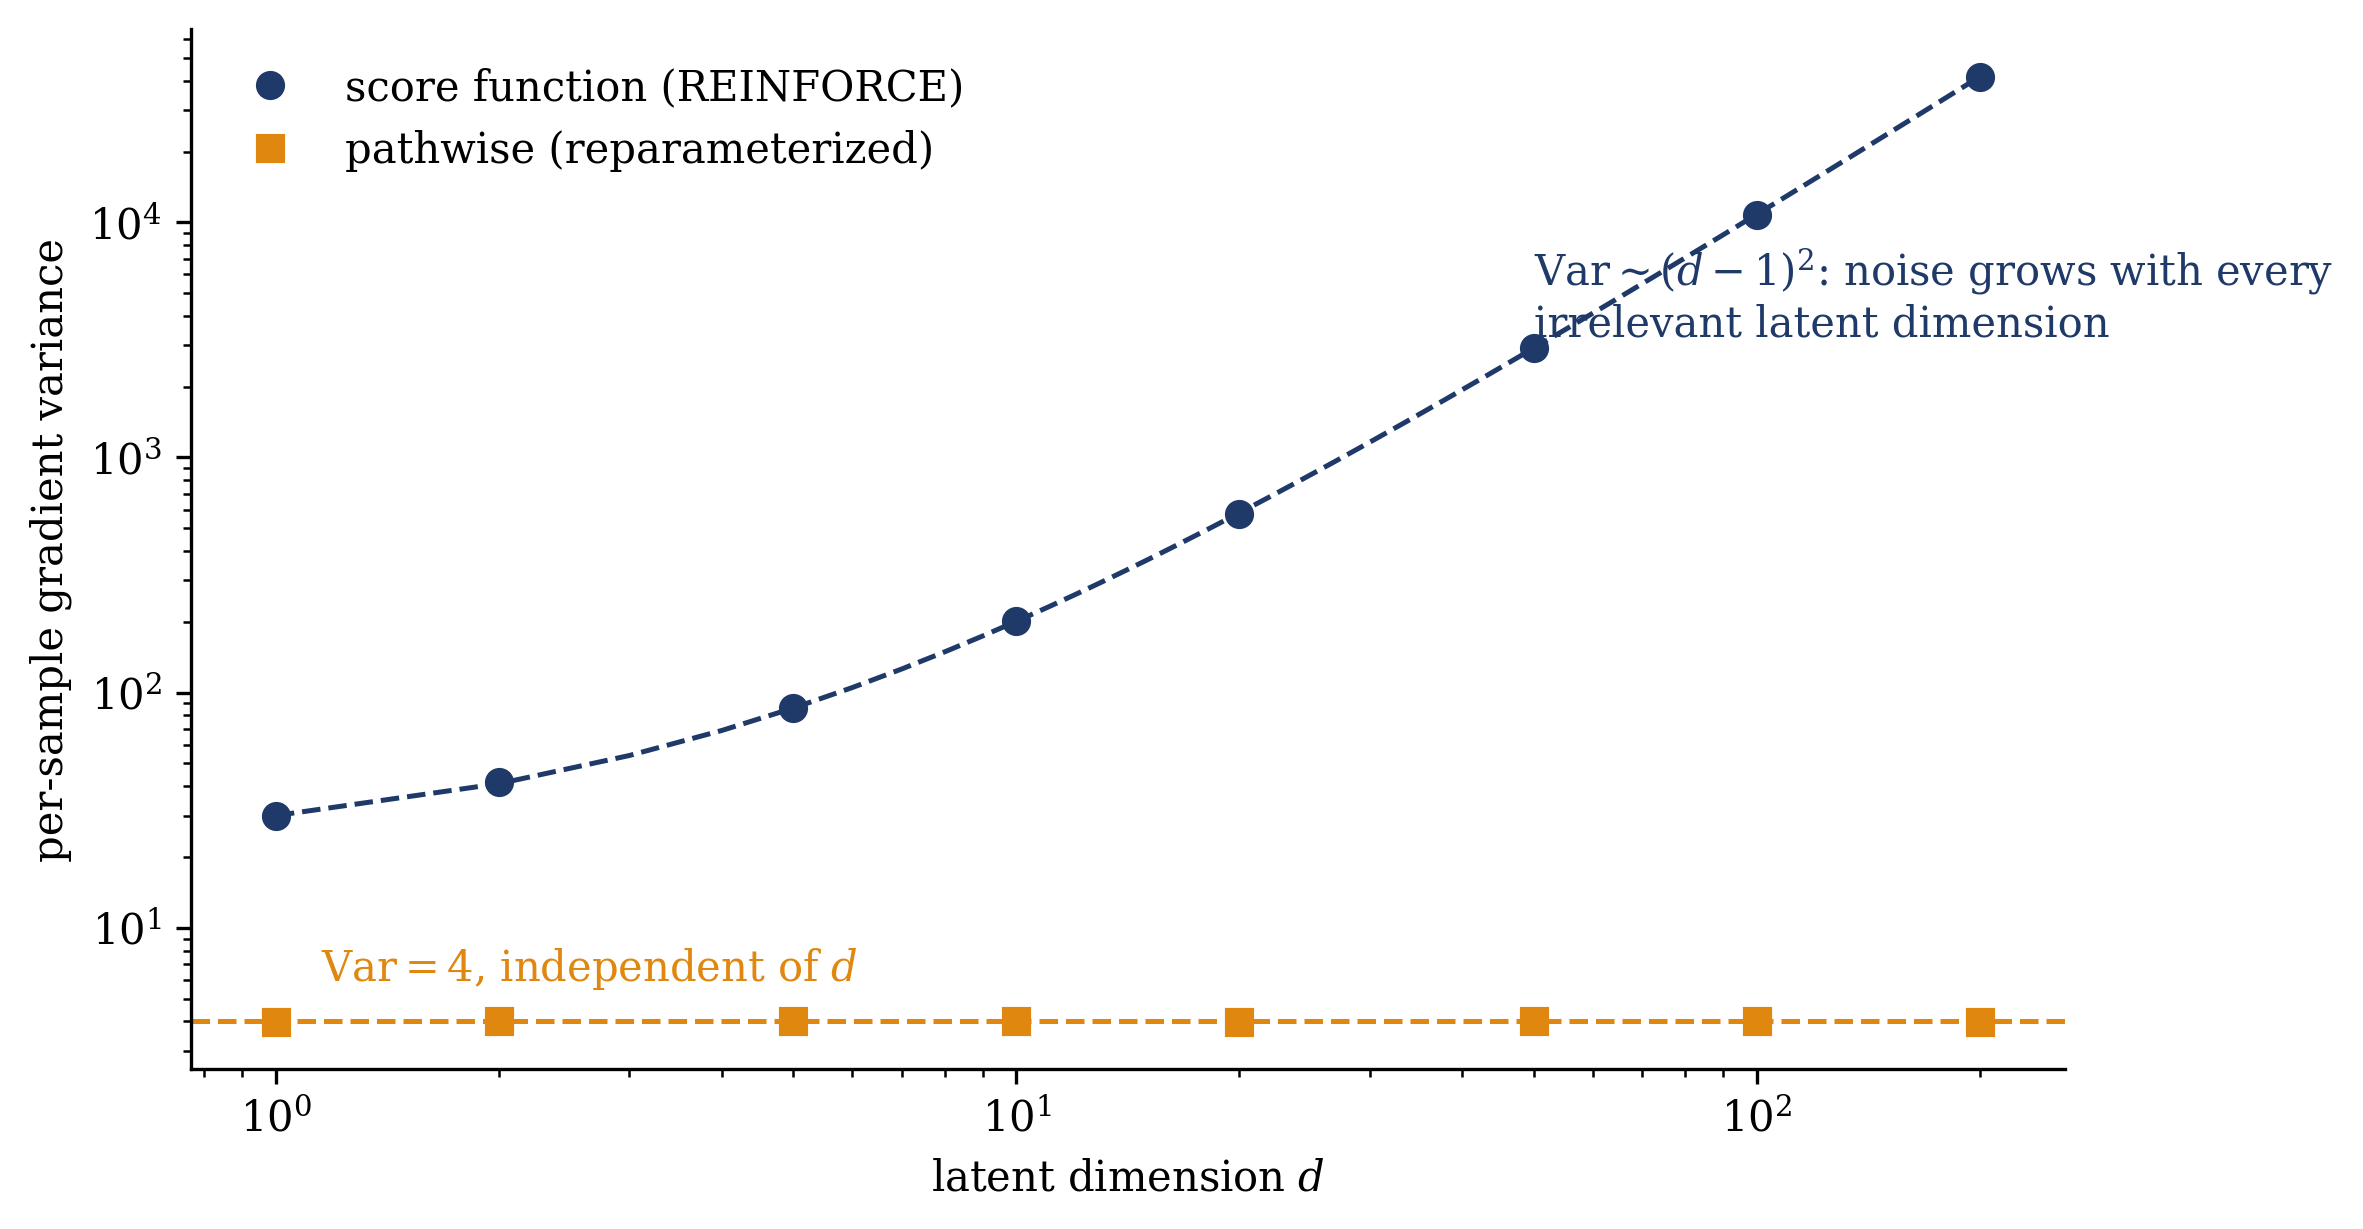
The variance claim can be made quantitative on a toy example. Take \(f(z) = \|z\|^2\) in \(d\) latent dimensions, \(q_\phi = \mathcal{N}(\mu, I)\) with \(\mu = (1, 0, \dots, 0)\), and estimate one gradient component, \(\partial_{\mu_1} \langle f \rangle = 2\mu_1 = 2\) — known exactly, so every estimator can be judged against the truth. Both estimators are unbiased; the question is their spread over single samples. A short calculation with Gaussian moments gives, per sample,
the pathwise variance is independent of dimension — the estimator \(2 z_1\) never sees the other \(d - 1\) coordinates — while the score-function estimator multiplies the full value \(\|z\|^2\), fluctuations of every irrelevant dimension included, by the score of \(z_1\), and its variance grows quadratically with \(d\). Figure 14.3 samples both. Already at \(d = 2\) the score-function estimator is ten times noisier (\(41\) against \(4\)); at \(d = 100\) its variance is \(1.08 \times 10^4\), a factor \(2{,}700\) above pathwise, and a latent of realistic size would need thousands of samples to match what reparameterization delivers with one.
Figure 14.3: One gradient, two estimators: the per-sample variance of \(\partial_{\mu_1}\langle\, \|z\|^2 \rangle_{q}\) for \(q = \mathcal{N}(\mu, I)\), \(\mu = (1, 0, \dots, 0)\), as a function of the latent dimension \(d\) (\(2 \times 10^5\) samples per point; dashed lines are the exact Gaussian-moment results). The score-function estimator \(\|z\|^2 (z_1 - \mu_1)\) (navy) multiplies the full value of \(f\) — every irrelevant dimension’s fluctuation included — by the score, and its variance grows as \((d-1)^2\): at \(d = 100\) it reaches \(1.08 \times 10^4\). The pathwise (reparameterized) estimator \(2 z_1\) (orange) uses the slope of \(f\) and stays at \(4\), independent of dimension — a factor \(2{,}700\) below score-function at \(d = 100\). Both estimators are unbiased; their variances differ by more than three orders of magnitude.
14.6 What we trained, in Week 5’s language
The correspondence with Week 5 is now direct. Fix a data point \(x\) and take the energy of Section 9.4, \(E(z) = -\log p_\theta(x, z)\) at \(T = 1\); then the variational free energy of the encoder is
\[
F_\mathrm{var}(q_\phi)
\;=\; \langle E \rangle_{q_\phi} - S[q_\phi]
\;=\; -\underbrace{\big\langle \log p_\theta(x \mid z) \big\rangle_{q_\phi}}_{\text{reconstruction (data part of } -\langle E \rangle)}
\;+\; \underbrace{D_\mathrm{KL}\big(q_\phi(z \mid x) \,\big\|\, p(z)\big)}_{\text{KL to prior} \;=\; \text{entropy/prior term}}
\;=\; -\,\mathrm{ELBO},
\tag{14.6}\]
the VAE loss is the variational free energy
term for term: the reconstruction is the data part of the energy, the KL regularizer bundles the prior part of the energy with the entropy of \(q_\phi\), and the training loss \(-\mathcal{L}\) of Equation 14.5is\(F_\mathrm{var}\) averaged over the dataset. Training a VAE is variational free-energy minimization with an amortized, neural \(q\) — the physicist minimizing \(F_\mathrm{var}\) over a trial family and the engineer running Equation 14.5 through an optimizer are performing the same optimization on the same functional.
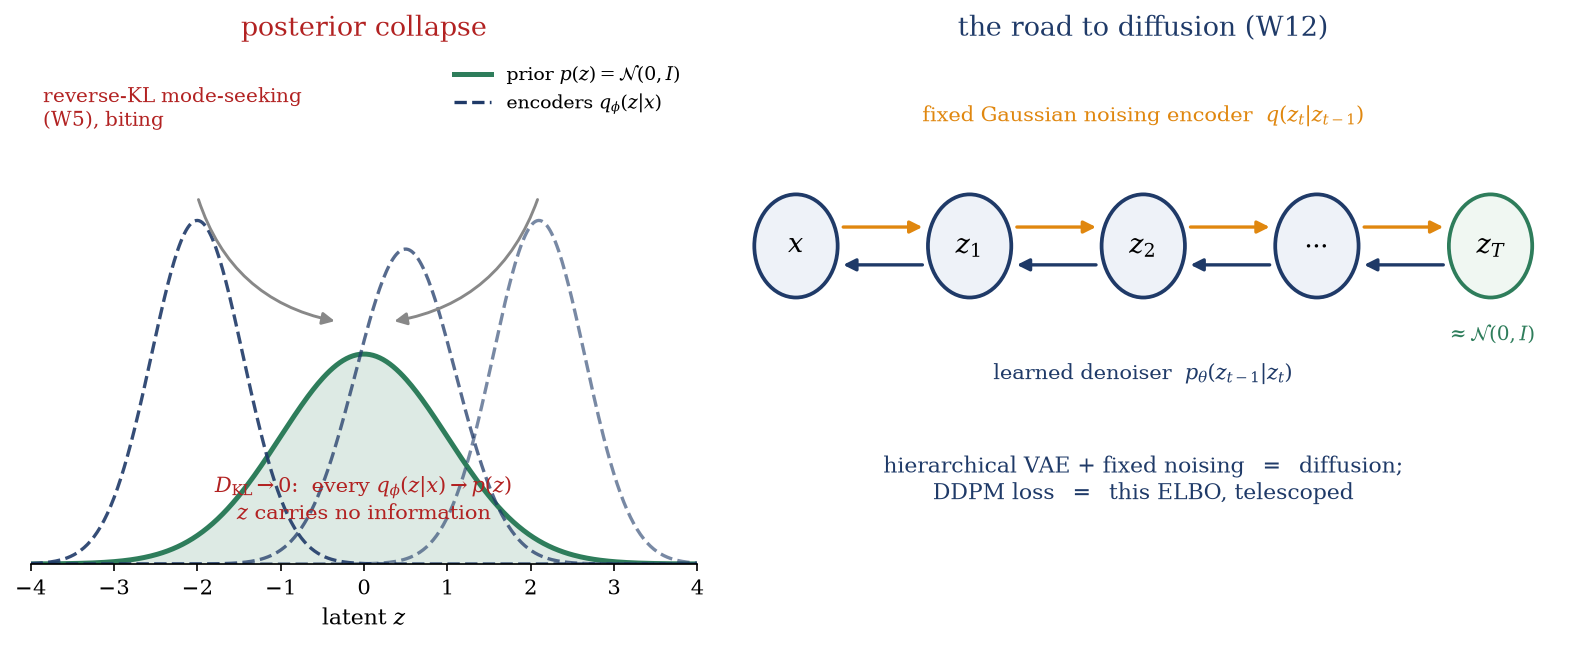
Posterior collapse. Suppose the decoder is expressive enough to model the data with no help from the latent — an autoregressive decoder on images can be. Then the reconstruction term no longer needs \(z\), the KL term is unopposed, and the optimum drives \(q_\phi(z \mid x) \to p(z)\) for every \(x\): the KL reaches zero, the latent carries no information, and the “generative model” degenerates into a decoder that ignores its own code (Figure 14.4, left). This is posterior collapse, the VAE’s characteristic failure. It is not the mode-seeking of Week 5’s reverse KL: a decoder that ignores \(z\) makes the true posterior equal to the prior, so the gap \(D_\mathrm{KL}(q_\phi \| p_\theta(z \mid x))\) is zero. The cause is the regularizer, which faces no opposing term once the decoder does not need the latent. The standard fixes reweight the balance: the β-VAE of Higgins et al. (2017) multiplies the KL term by a coefficient β (a KL weight — not an inverse temperature, despite this course’s reflexes), KL annealing ramps that weight from zero during training, and free bits exempt a per-dimension quota of KL from the loss. Each adjusts the same balance between reconstruction sharpness and latent structure.
Where the intractability went. Placing the VAE alongside Module 1’s models clarifies the comparison. The RBM (Chapter 6) is an undirected model: its \(Z\) runs over all configurations, the likelihood gradient needs the model average (Equation 5.5), and Week 3 approximated it by short Gibbs chains, accepting CD’s bias. The VAE is a directed model: the decoder conditional \(p_\theta(x \mid z)\) is normalized by construction and the prior is fixed, so there is no \(Z\) over \(x\) to fight — the hard object is now the posterior\(p_\theta(z \mid x)\), and the encoder approximates it variationally. The intractability was moved, not removed: undirected models meet it at the partition function, directed models at the posterior, and every generative-modeling method in this course is a choice of where to meet it.
Trap
Two KLs, one bound, and one trick leave three ways to slip. ① The ELBO’s own KL term is \(D_\mathrm{KL}(q_\phi(z \mid x) \| p(z))\) — encoder to prior, the regularizer inside the objective. The ELBO’s gap is \(D_\mathrm{KL}(q_\phi(z \mid x) \| p_\theta(z \mid x))\) — encoder to posterior, the distance to the evidence. Conflating them is the classic error; only the first is computable, and only the second measures approximation quality. ② The ELBO is a lower bound, not the likelihood: a trained VAE sits below its own model’s \(\log p_\theta(x)\) by the approximation gap plus the amortization gap. ③ The reparameterization trick requires a latent that is a differentiable transform of fixed noise — Gaussians qualify, discrete latents do not (Gumbel-softmax or score-function methods take over there).
Take-home 3
Training a VAE is amortized variational free-energy minimization. Its signature failure, posterior collapse, occurs when the KL regularizer is unopposed and the latent is ignored; β-VAE, KL annealing, and free bits reweight the balance.
The VAE is Week 5’s variational free energy, minimized by a neural network — reconstruction against a KL regularizer.
14.7 Outlook: the road to diffusion
Module 2 set out to approximate an intractable distribution and found four ways to do it: the factorized family (Week 5), the corrected expansion (Chapter 11), message passing on the graph (Chapter 12), and the decoupled latent-variable model (this week). They relate differently to Week 5’s functional. Mean field and the VAE optimize the variational free energy \(F_\mathrm{var}\) itself, over factorized distributions in Week 5 and over amortized Gaussian encoders today, and both keep its bound. TAP (Chapter 11) and the Bethe free energy (Chapter 12) modify the functional, the first by truncating an expansion and the second by replacing the entropy with a tree count, and both give up the bound. The Hubbard–Stratonovich saddle of the previous lecture is the leading order of an exact integral, which reaches the mean-field equation from the other side. The last method is, moreover, not an approximation scheme but a model class, trained by descending \(F_\mathrm{var}\) with a neural network.
The connection to the course’s title is direct. A VAE has one latent layer; nothing forbids a hierarchy, \(x \to z_1 \to \dots \to z_T\), each layer conditioned on the last. Now make one deliberately strange choice: fix the encoder to a chain of Gaussian noising steps \(q(z_t \mid z_{t-1})\) — no parameters, no learning, just incremental corruption of the data toward \(z_T \approx \mathcal{N}(0, I)\) — and learn only the decoder chain \(p_\theta(z_{t-1} \mid z_t)\) that runs the corruption backwards (Figure 14.4, right). That model is a diffusion model, and its training loss — the DDPM objective of Week 12 (Ho, Jain, and Abbeel 2020; Sohl-Dickstein et al. 2015) — is a reweighted form of this lecture’s ELBO, telescoped along the hierarchy into a sum of per-step denoising terms. The free energy that entered the course as a bound in Week 5 and became a training objective today therefore trains the generative models of Module 4 as well; from Boltzmann to diffusion is, at the level of the objective, one equation carried forward.
Figure 14.4: Left: posterior collapse. A powerful decoder leaves the KL term unopposed, and every encoder distribution \(q_\phi(z \mid x)\) (navy, dashed) is driven onto the prior \(p(z)\) (green): the KL reaches zero and the latent carries no information, while the gap to the true posterior is also zero. Right: the road to diffusion. Stack latents \(x \to z_1 \to \dots \to z_T\) with a fixed Gaussian noising encoder (orange) and a learned denoising decoder (navy): a hierarchical VAE whose ELBO, telescoped over the steps, is the DDPM training loss of Week 12.
Every method since Week 5 has approximated or transformed the distribution; none has drawn from it. Module 3 takes the complementary approach and samples: Monte Carlo and the Metropolis rule, annealing on rugged landscapes, and stochastic gradient descent read as a Langevin process — the machinery that turns Week 2’s energy landscapes and this module’s free energies into working algorithms.
Dayan, Peter, Geoffrey E. Hinton, Radford M. Neal, and Richard S. Zemel. 1995. “The Helmholtz Machine.”Neural Computation 7 (5): 889–904. https://doi.org/10.1162/neco.1995.7.5.889.
Higgins, Irina, Loic Matthey, Arka Pal, Christopher Burgess, Xavier Glorot, Matthew Botvinick, Shakir Mohamed, and Alexander Lerchner. 2017. “\(\beta\)-VAE: Learning Basic Visual Concepts with a Constrained Variational Framework.” In International Conference on Learning Representations (ICLR).
Hinton, Geoffrey E., Simon Osindero, and Yee-Whye Teh. 2006. “A Fast Learning Algorithm for Deep Belief Nets.”Neural Computation 18 (7): 1527–54. https://doi.org/10.1162/neco.2006.18.7.1527.
Ho, Jonathan, Ajay Jain, and Pieter Abbeel. 2020. “Denoising Diffusion Probabilistic Models.” In Advances in Neural Information Processing Systems. Vol. 33. https://arxiv.org/abs/2006.11239.
Kingma, Diederik P., and Max Welling. 2014. “Auto-Encoding Variational Bayes.” In International Conference on Learning Representations (ICLR).
———. 2019. “An Introduction to Variational Autoencoders.”Foundations and Trends in Machine Learning 12 (4): 307–92. https://doi.org/10.1561/2200000056.
Mehta, Pankaj, Marin Bukov, Ching-Hao Wang, Alexandre G. R. Day, Clint Richardson, Charles K. Fisher, and David J. Schwab. 2019. “A High-Bias, Low-Variance Introduction to Machine Learning for Physicists.”Physics Reports 810: 1–124. https://doi.org/10.1016/j.physrep.2019.03.001.
Rezende, Danilo Jimenez, Shakir Mohamed, and Daan Wierstra. 2014. “Stochastic Backpropagation and Approximate Inference in Deep Generative Models.” In Proceedings of the 31st International Conference on Machine Learning (ICML), 32:1278–86. PMLR.
Sohl-Dickstein, Jascha, Eric Weiss, Niru Maheswaranathan, and Surya Ganguli. 2015. “Deep Unsupervised Learning Using Nonequilibrium Thermodynamics.” In Proceedings of the 32nd International Conference on Machine Learning, 37:2256–65. Proceedings of Machine Learning Research. https://arxiv.org/abs/1503.03585.