Core (~1 h).Ramsauer et al. (2021) — the continuous modern Hopfield network: the log-sum-exp energy, the one-step softmax update, exponential storage, and the attention equivalence; read the energy, the update theorem, and the attention identification — this lecture makes them precise. Alongside it, Vaswani et al. (2017), §3.2 — scaled dot-product attention, the equation we collide with Ramsauer’s update. The transformer itself is assumed largely familiar from the companion Machine Learning and Physics course; re-read the attention section only.
Optional background.Krotov and Hopfield (2021) — the general “large associative memory” framework (visible/hidden neurons, general Lagrangians) containing both the previous lecture’s discrete network and today’s continuous one; Yuille and Rangarajan (2003) — the concave–convex procedure behind the update’s descent guarantee; Bahdanau, Cho, and Bengio (2015) — where attention entered machine learning, as an alignment mechanism for translation, some six years before it was read as a Hopfield update.
Prerequisite reminder. All of Chapter 7 — the dense-memory energy, the \(F'\)-filter, exponential capacity, and the mixture states of the tradeoff section — plus the softmax-is-Boltzmann corollary of Section 1.6 and scaled dot-product attention from the companion course. New today: the log-sum-exp energy, the one-step softmax update with its descent guarantee, and the identification with attention.
8.1 Two titles, one claim
The previous lecture ended by making the states continuous, so that retrieval collapses to a single step.
In 2017, Vaswani and coauthors announced to machine learning that Attention Is All You Need(Vaswani et al. 2017) — and the transformer architecture built on that paper came to dominate the entire field: language, vision, protein structure, code. In 2021, Ramsauer and coauthors — Hochreiter’s group in Linz — replied with a paper called Hopfield Networks is All You Need(Ramsauer et al. 2021), and showed that the two titles make the same claim. The attention mechanism at the center of modern AI is the retrieval update of a continuous Hopfield network — Week 2’s machine, scaled by the previous lecture’s dial and made smooth, written in an engineer’s notation. (Attention entered machine learning as a learned alignment for machine translation (Bahdanau, Cho, and Bengio 2015); nobody involved was thinking about spin systems. The identification came after the architecture had been adopted, as a property of its structure.)
An attention layer performs one retrieval step of a content-addressable memory descended from Hopfield (1982) — a step of energy descent when keys and values coincide. The energy-based view of computation, scaled in the previous lecture and made continuous today, is therefore the mechanism at the heart of the architecture that now dominates machine learning. Today’s only normalizer is a softmax denominator over a finite set of stored patterns, a sum of the same kind as the RBM’s \(Z(v)\) in Week 3 and as tractable; the partition function over the states themselves never appears. Module 2, which requires normalized distributions, reintroduces it.
Take-home 1
Give a continuous state one quadratic well per stored pattern and trace out which pattern it sits in: the result is the log-sum-exp energy, smooth and differentiable. Its gradient is a softmax average, the Boltzmann distribution over a finite set of stored patterns, so \(Z\) poses no difficulty.
8.2 From discrete flips to a continuous state
Two objects that look unrelated — a physicist’s associative memory (an energy over states, minimized to retrieve a stored pattern from a cue) and an ML engineer’s attention layer (a query, a stack of keys and values, a softmax-weighted readout) — are built below from their own sides and then compared. Both rest on the same picture: a query vector reaching into a cloud of stored patterns, a weight on each pattern proportional to how well it matches, and an output assembled as the weighted sum.
The previous lecture’s retrieval still ran by discrete spin flips, many of them, and a sequence of discrete flips passes no gradient. To place retrieval inside a network trained by backpropagation, we want the state itself to vary continuously and retrieval to be one differentiable map.
Setup. Stack the \(M\) stored patterns as the columns of a matrix, \(X = [\,x_1, \dots, x_M\,]\), each \(x_\mu \in \mathbb{R}^d\) — continuous vectors now, not spins. The state is a continuous query\(\xi \in \mathbb{R}^d\), and \(\beta > 0\) is an inverse temperature. (A notation flag, since we adopt Ramsauer’s: through Weeks 2–4 the symbol \(\xi^\mu\) was a stored pattern and the count was \(P\); from here \(\xi\) is the query state, the stored patterns are the \(x_\mu\), and their number is \(M\) — the relabeling brings us into line with the attention literature we are about to meet.)
One well per pattern. Every energy of Weeks 2–4 scored a state by its overlaps with the stored patterns. For a single pattern the simplest such energy, \(-x_\mu \cdot \xi\), was bounded on spins because the state could not leave the hypercube; a continuous state can, and the energy decreases without limit along \(x_\mu\). The simplest confinement is a quadratic bowl, which gives
a quadratic well with its minimum exactly at the stored pattern, the match still scored by the overlap alone.
Which pattern? A cue does not come labeled with the memory it belongs to, so the pattern index \(\mu\) is a variable the state does not fix. Week 3 met this situation with the RBM’s hidden units (Section 6.3): give each joint configuration its Boltzmann weight and trace out the variable that is not observed. Here the joint weight is \(e^{-\beta E(\xi, \mu)}\), the trace is a sum of \(M\) terms, and it leaves an effective energy for the state alone,
The pattern index plays the role of the RBM’s hidden units, and the sum over \(\mu\) plays the role of \(Z(v)\) of Section 5.6: a partition function with the visible state held fixed, here with \(M\) terms and computed exactly. As for the RBM, the sum that would be intractable is the one over the states, \(\int d\xi\, e^{-\beta E(\xi)}\), and retrieval never needs it. The same trace hands us the conditional law of the index,
a Boltzmann distribution over the \(M\) stored patterns with the overlap as the negative energy: Week 1’s distribution over a finite set of labels, and the reason \(Z\) poses no difficulty today.
The function that appeared. Write the overlaps as \(z_\mu = x_\mu \cdot \xi\). The trace produced the function \(\beta^{-1} \log \sum_\mu e^{\beta z_\mu}\), and differentiating it with respect to \(z_\mu\) returns \(p(\mu \mid \xi)\), the Boltzmann weight of pattern \(\mu\). As \(\beta \to \infty\) the largest term dominates the sum, so the function tends to \(\max_\mu z_\mu\) and the weights to a one-hot vector on the best-matching pattern: the hard selection of the previous lecture’s sharp limit. At finite \(\beta\) both are smooth. The function is the log-sum-exp, the smooth max, and its gradient is the softmax, the smooth argmax:
log-sum-exp: the smooth max; softmax: the smooth argmax
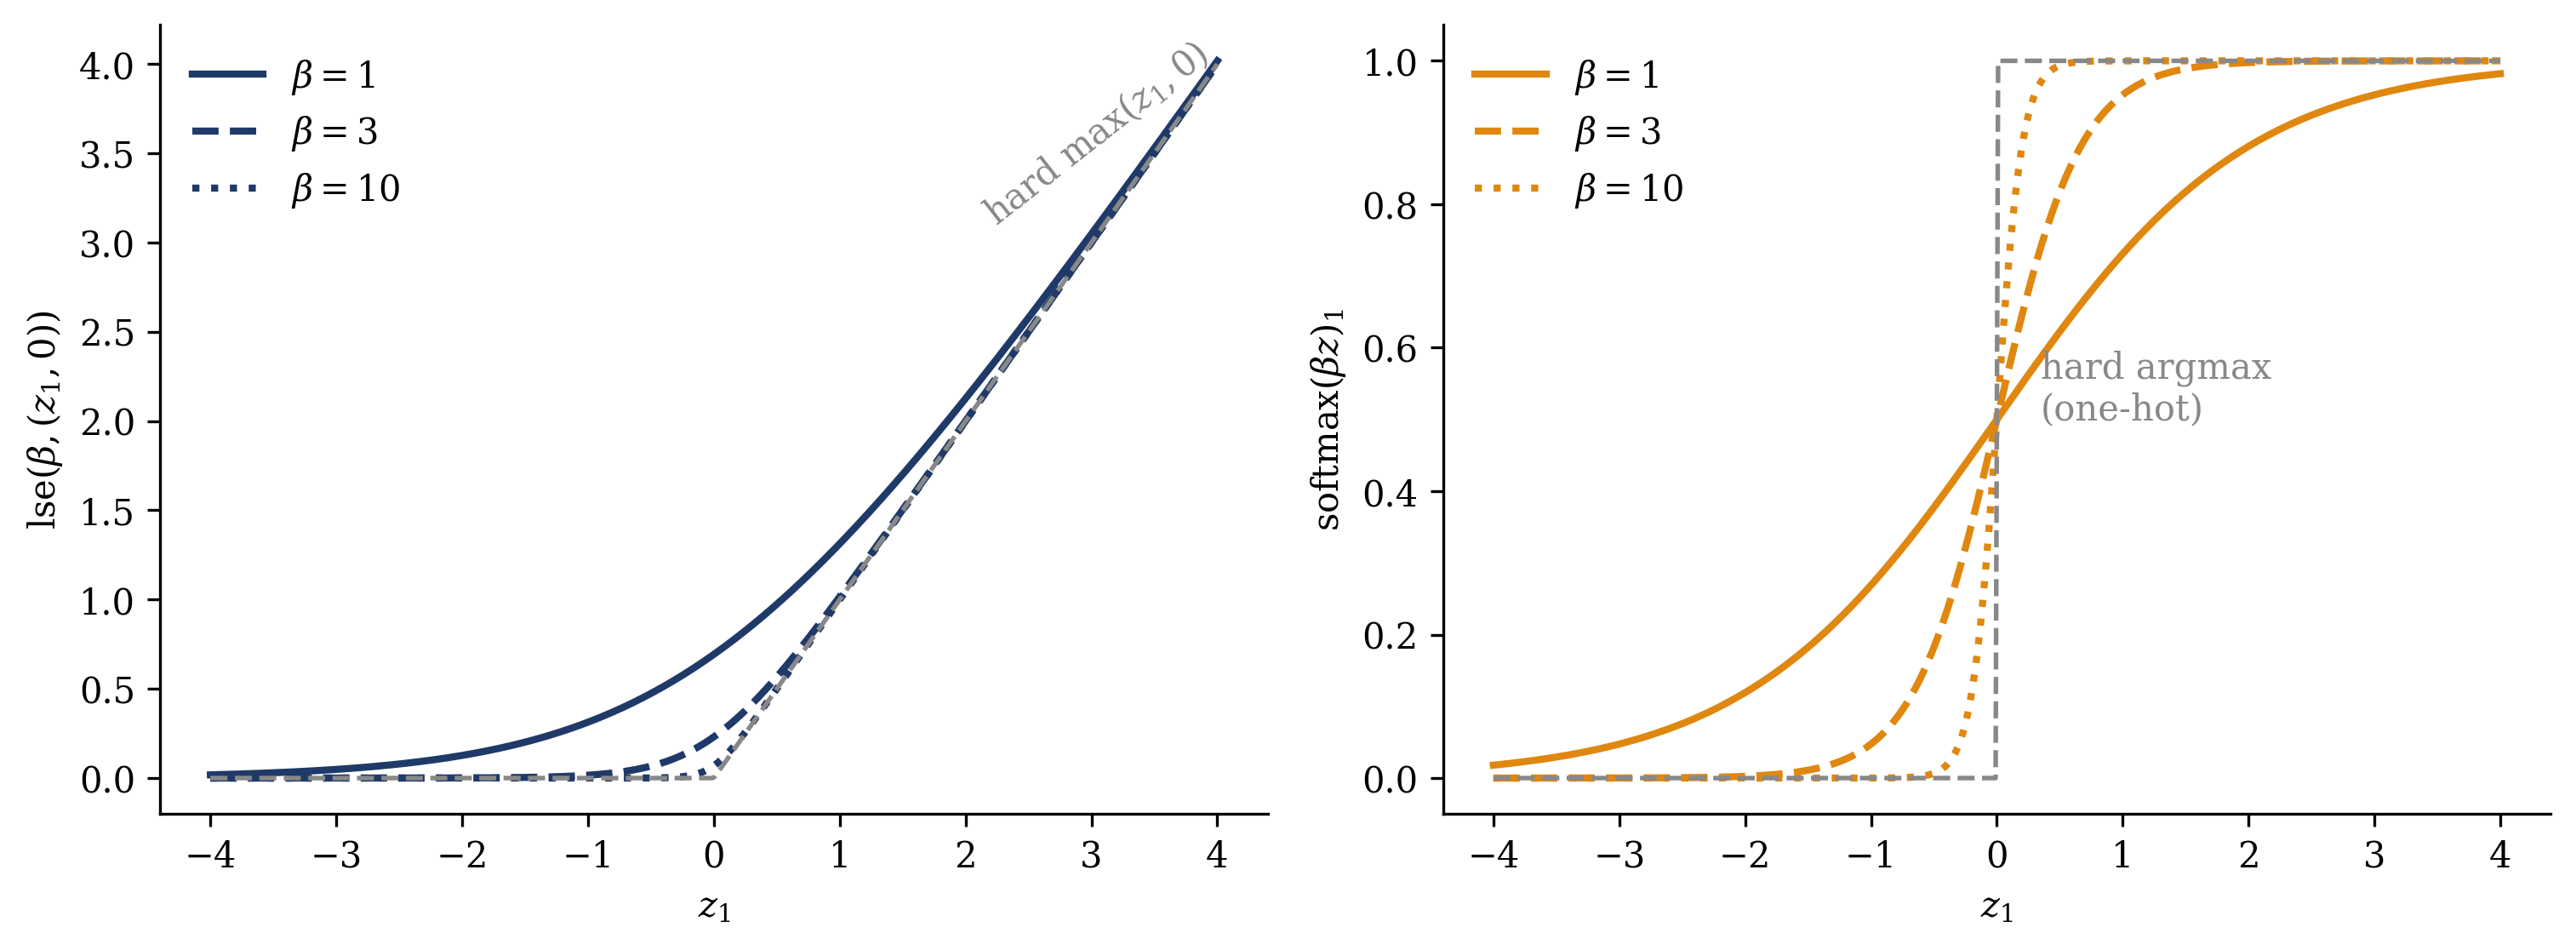
Figure 8.1 draws the pair. For two options, \(\operatorname{lse}\)is the softplus of Section 6.3, which is no coincidence: the RBM’s traced-out hidden unit was a two-state sum of exactly this kind. The relation to the previous lecture is also direct. In this notation its exponential interaction gives \(E_\text{dense}(\xi) = -\sum_\mu e^{\beta\, x_\mu \cdot \xi}\), and \(-\operatorname{lse}(\beta, X^T\xi) = -\beta^{-1}\log(-E_\text{dense})\) is an increasing function of \(E_\text{dense}\), so the traced energy ranks states exactly as the dense memory does. Because the log-sum-exp lies between \(\max_\mu x_\mu\cdot\xi\) and that maximum plus \(\beta^{-1}\log M\), it grows only linearly in the overlaps, and the quadratic bowl now bounds the energy from below, which the bare exponential on a continuous state did not allow.
Figure 8.1: The smooth max and the smooth argmax, drawn for two options \(z = (z_1, 0)\). Left: \(\operatorname{lse}(\beta, z) = \beta^{-1}\log(e^{\beta z_1} + 1)\) approaches the hard \(\max(z_1, 0)\) (dashed) as \(\beta\) grows — and the \(\beta = 1\) curve is exactly the softplus that appeared when Week 3 traced out an RBM’s hidden unit. Right: the corresponding weight \(\operatorname{softmax}(\beta z)_1 = \sigma(\beta z_1)\) sharpens from a gentle preference to the hard one-hot \(\operatorname{argmax}\) (dashed step). The trace over the pattern index produces these smooth versions directly, and \(\beta\) sets how close to the previous lecture’s hard selection they come.
Two steps remain: ① the one-step update that minimizes this energy; ② the identification of that update with attention.
8.3 The log-sum-exp energy and its one-step update
In the names just introduced, the traced energy is the one written by Ramsauer et al. (2021):
(The constant, \(\beta^{-1}\log M + \tfrac{1}{2} M_\text{max}^2\) with \(M_\text{max}\) the largest pattern norm, makes \(E \geq 0\); it carries no \(\xi\)-dependence and will not survive a gradient, so we drop it from every display that follows.) Before differentiating, consider the landscape: \(-\operatorname{lse}\) digs a well wherever \(\xi\) has a large overlap with some stored pattern — one well per pattern, deeper and narrower as \(\beta\) sharpens — and the quadratic term is the bowl that keeps a query from running off to infinity along a pattern direction. This is the previous lecture’s picture (Figure 7.1, right panel), drawn in a continuous space.
The gradient, in full. Since \(E(\xi)\) is a free energy with \(\mu\) traced out, its gradient is the conditional average of the joint energy’s gradient, \(\nabla_\xi E = \sum_\mu p(\mu \mid \xi)\, \nabla_\xi E(\xi, \mu) = \xi - \sum_\mu p(\mu \mid \xi)\, x_\mu\). The chain rule on \(\operatorname{lse}\) gives the same result, component \(i\):
In words: the retrieved state is a softmax-weighted average of the stored patterns, each weighted by how well it matches the current query. The weights are those of the previous lecture’s normalized filter Equation 7.7 — score every memory against the cue, exponentiate, normalize, and blend — and the continuous state takes the weighted average itself, where the binary network kept only its sign.
Three properties make this equation a usable neural-network layer.
First, iterating the update descends the energy. The energy Equation 8.1 splits by construction into a concave piece (\(-\operatorname{lse}\); the log-sum-exp is convex, so its negative is concave) plus a convex piece (\(\tfrac12\|\xi\|^2\)). For exactly such splittings, the concave–convex procedure of Yuille and Rangarajan (2003) supplies a descent scheme: at the current point, replace the concave piece by its tangent plane — which, by concavity, lies above it everywhere — and minimize the resulting convex upper bound exactly. Minimizing \(\tfrac12\|\xi\|^2\) minus the linearization \(\big(X\operatorname{softmax}(\beta X^T\xi^t)\big)\!\cdot\xi\) is a one-line quadratic problem, and its solution is precisely Equation 8.2. Each iterate therefore minimizes a surface that touches \(E\) at the current point and majorizes it elsewhere, so \(E\) can only decrease: the Lyapunov property of Section 3.4, carried over from discrete flips (W2) to a smooth map.
Second, one step is essentially enough.Ramsauer et al. (2021) make “well-separated” quantitative: define a pattern’s separation\(\Delta_\mu\) as the gap between its self-overlap and its largest rival overlap, \(\Delta_\mu = x_\mu \cdot x_\mu - \max_{\nu \neq \mu} x_\mu \cdot x_\nu\). For \(\Delta_\mu\) sufficiently large (relative to \(1/\beta\)), the update is a contraction near \(x_\mu\), a fixed point exists exponentially close to the pattern, and — the key consequence for practice — a single application of Equation 8.2, from any query in a small sphere around \(x_\mu\), lands exponentially close to that fixed point. Retrieval therefore requires one differentiable map, evaluated once, instead of Week 2’s long relaxation of single-spin flips, which is exactly the property that lets it sit as a layer inside a network trained end-to-end by backpropagation.
Third, the storage matches the previous lecture’s. The number of random patterns (say, placed on the sphere) that remain well-separated in the above sense — and hence individually retrievable — grows exponentially with the dimension\(d\)(Ramsauer et al. 2021): the continuous network inherits the exponential capacity of the \(F = e^x\) interaction it descends from, with \(d\) playing the role the previous lecture’s \(N\) played. (For the unified view of why the inheritance is exact — discrete and continuous networks as two choices of “Lagrangian” in one general framework, with the update rules and energies generated mechanically from that choice — see Krotov and Hopfield (2021), the general treatment behind both of this week’s lectures; a script-level pointer, not an examinable one.)
The inverse temperature \(\beta\) controls the behavior. Large \(\beta\): the softmax approaches a one-hot vector, and the update returns the single nearest pattern — exact retrieval, the previous lecture’s sharp limit. Small \(\beta\): the softmax spreads, and the update returns a broad weighted average of several patterns — the mixture states of the previous lecture, now produced deliberately; Ramsauer et al. (2021) call such averages metastable states. One parameter sweeps from lookup to blending, and it reappears in attention as \(1/\sqrt{d_k}\).
8.4 This update is attention
The update, read as an engineer would, is a matrix, a softmax, and a matrix — the structure of transformer attention.
Recall, from the companion course, the equation at the center of the transformer (Vaswani et al. 2017). Given a stack of queries\(Q\) (one per row), keys\(K\), and values\(V\) (one per row), scaled dot-product attention computes
Take our update Equation 8.2, transpose it into the same row-vector convention (a query is a row \(q = \xi^T\); the stored patterns are the rows of \(X^T\)), and it reads \(q^\text{new} = \operatorname{softmax}\big(\beta\, q\, (X^T)^T\big)\, X^T\). Set the two equations on one line:
\[
\boxed{\;
Q \leftrightarrow \text{the query state } \xi, \qquad
K \leftrightarrow \text{the stored patterns (keys)}, \qquad
V \leftrightarrow \text{the stored patterns (values)}, \qquad
\beta \leftrightarrow \frac{1}{\sqrt{d_k}}.
\;}
\tag{8.3}\]
attention = one step of Hopfield retrieval
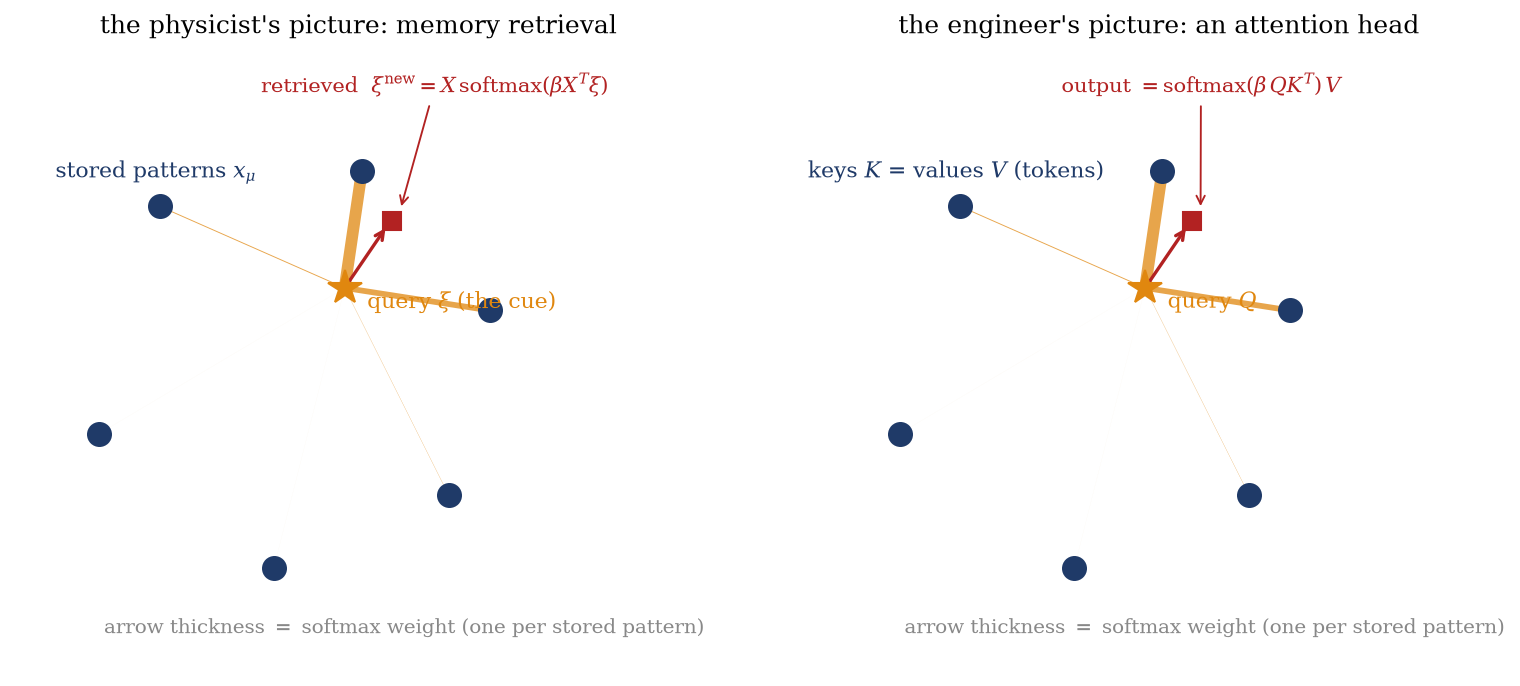
One transformer attention layer is one step of modern Hopfield retrieval. The queries are cues; the keys are the stored patterns the cue is matched against; the values are the stored patterns that get blended into the output; and \(1/\sqrt{d_k}\) is the inverse temperature of the lookup. Figure 8.2 draws the identification.
The dressed dictionary, as transformers actually implement it, follows. The correspondence above is the skeleton (\(K = V = X\), no learned parameters); a real attention layer inserts three linear maps: \(Q = \Xi\, W_Q\), \(K = Y\, W_K\), \(V = Y\, W_V\), where \(\Xi\) holds the querying tokens and \(Y\) the attended-to tokens. Read as memory, the projections have a natural interpretation: \(W_K\) chooses in which learned subspace the matching is scored (what counts as similar), \(W_V\) chooses what is returned when a pattern matches (the payload need not be the address), and \(W_Q\) maps the current token into the matching space — a content-addressable memory whose addressing scheme and stored content are themselves learned. Self-attention is the case \(Y = \Xi\): the sequence is its own memory, every token a query into all the others. Cross-attention stores one sequence and queries it with another — an encoder’s output retrieved by a decoder, which is exactly the alignment problem attention was invented for (Bahdanau, Cho, and Bengio 2015). Multi-head attention runs \(h\) such retrievals in parallel, each with its own projections — \(h\) associative memories reading the same tokens in different learned subspaces, their outputs concatenated — and stacking layers chains single retrieval steps through a sequence of different learned memories.
Figure 8.2: One calculation, two labelings. A query reaches into a cloud of six stored patterns; each pattern receives a softmax weight (arrow thickness) according to its overlap with the query; the output is the weighted average, pulled toward the best-matching pattern. Left, the physicist’s labels: cue, stored patterns, retrieval \(\xi^\text{new} = X\operatorname{softmax}(\beta X^T\xi)\). Right, the engineer’s labels: query, keys and values, attention output \(\operatorname{softmax}(\beta\, QK^T)V\). The geometry, the weights, and the output are identical.
The role of \(\sqrt{d_k}\). The scaling in Vaswani’s denominator is introduced, in the original paper, as a numerical fix: dot products of \(d_k\)-dimensional vectors with \(\mathcal{O}(1)\) components grow like \(\sqrt{d_k}\), and without the division the softmax saturates — one weight near \(1\), the rest near \(0\), gradients vanishing through the flat tails. Read through today’s dictionary, that fix is a temperature: \(\beta = 1/\sqrt{d_k}\) holds the retrieval at moderate sharpness as the dimension grows, deliberately keeping attention out of the hard-argmax regime. The scaling factor of Vaswani et al. (2017) is thus a statistical-mechanics temperature, made explicit by the Hopfield reading (Ramsauer et al. 2021). The effect is easily misread. At fixed overlaps, a larger \(d_k\) would mean a smaller \(\beta\) and a softer lookup; but the overlaps themselves grow like \(\sqrt{d_k}\), the two factors cancel, and the scaled logits stay of order one. Relative to unscaled attention the lookup is softer; across dimensions its sharpness is held fixed.
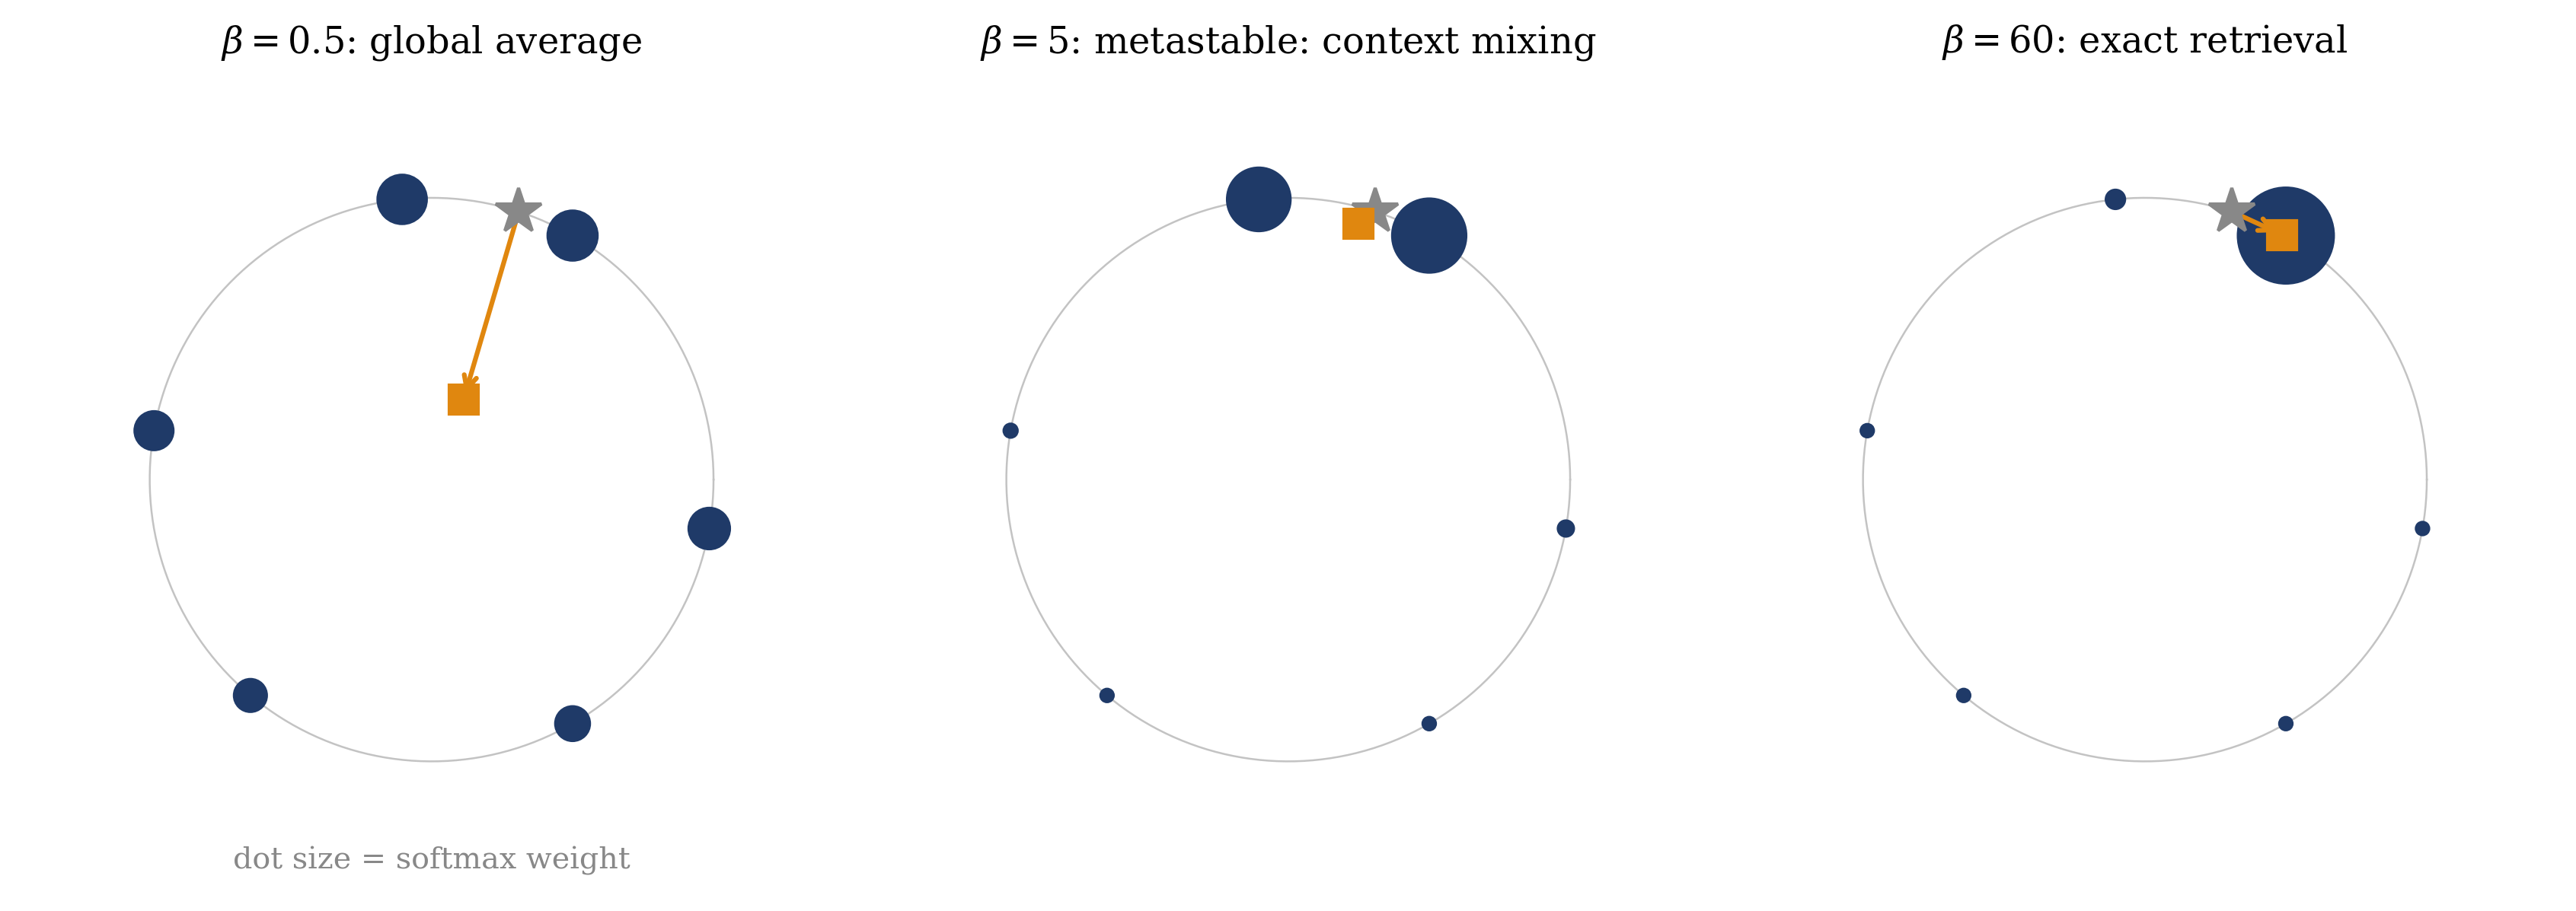
Metastable states in attention. The previous lecture’s mixture states — retrievals that blend several nearby patterns — were discussed as a cost of the exponential interaction. For an attention head they are the desired output: a query (a token in context) rarely wants a single stored pattern; it wants a weighted blend of everything relevant — several previous tokens, in proportion to their relevance. That is precisely a metastable average, produced at moderate \(\beta\): mixture states, a limitation for exact recall, are the intended output of an attention head. Figure 8.3 runs the three regimes on one query.
Figure 8.3: The three retrieval regimes of the one-step update Equation 8.2, computed exactly for a query (star) amid six stored patterns (dots, sized by their softmax weight; the orange square is the retrieved \(\xi^\text{new}\)). Two of the patterns are deliberately close, and the query sits near both. Left, \(\beta = 0.5\): weights nearly uniform — the update returns a global average, useless as memory. Center, \(\beta = 5\): the weight concentrates on the two matching patterns (\(w \approx 0.57\) and \(0.42\)) — a metastable average, blending exactly the relevant items, which is what an attention head does to its context. Right, \(\beta = 60\): one-hot weights — exact single-pattern retrieval, the previous lecture’s sharp limit.
Two qualifications apply. First, one layer is one step: a transformer does not iterate Equation 8.2 to a fixed point — it takes a single retrieval step per attention layer and stacks layers, each with its own learned memory. “Attention minimizes an energy” overclaims. For \(K = V\), attention takes one descent step on an energy is the theorem; with separate learned value projections, as in a trained transformer, the layer is a Hopfield retrieval in key space followed by a linear readout, and the descent guarantee does not carry over. Second, the softmax denominator here — the sum over the \(M\) stored patterns or tokens — is a partition function over a finite menu, Week 1’s tractable case (Section 1.6) and the analogue of the RBM’s \(Z(v)\), not the \(2^N\) configuration sum of Week 3. The configuration partition function is absent from every transformer forward pass, and Week 3’s obstruction has no counterpart in a lookup over \(M\) items.
Trap
Two common misreadings. ① \(\beta = 1/\sqrt{d_k}\) does not make attention softer as \(d_k\) grows: query–key overlaps grow like \(\sqrt{d_k}\), so the scaled logits stay of order one and the sharpness is independent of \(d_k\). The scaling makes attention softer than its unscaled version, which would saturate. ② One attention layer performs one retrieval step, not a relaxation to a fixed point; and in a trained transformer \(K \neq V\) in general (separate learned projections of the same tokens). The equivalence is exact about structure and about a single step.
8.5 Example: one calculation, two names
We store \(M = 4\) patterns in \(d = 3\) and compute the update by hand: the unit vectors \(x_1 = (1,0,0)\), \(x_2 = (0,1,0)\), \(x_3 = (0,0,1)\), and the blend \(x_4 = (0, 1, 1)/\sqrt{2}\). The query is a corrupted version of the first memory, leaning toward the second: \(\xi = 0.8\, x_1 + 0.2\, x_2\), with overlaps \(X^T\xi = (0.8,\ 0.2,\ 0,\ 0.14)\). Compute \(w = \operatorname{softmax}(\beta X^T \xi)\) and \(\xi^\text{new} = Xw\) at three temperatures:
regime
\(\beta\)
weights \(w\)
\(\xi^\text{new}\)
reading
soft
\(1/\sqrt{3} \approx 0.58\)
\((0.33,\ 0.23,\ 0.21,\ 0.23)\)
\((0.33,\ 0.39,\ 0.37)\)
global average — everything blended
moderate
\(3\)
\((0.72,\ 0.12,\ 0.07,\ 0.10)\)
\((0.72,\ 0.19,\ 0.14)\)
metastable: \(x_1\) dominant, context mixed in
sharp
\(20\)
\((1.00,\ 0.00,\ 0.00,\ 0.00)\)
\((1.00,\ 0.00,\ 0.00) = x_1\)
exact retrieval — the previous lecture’s hard limit
At \(\beta = 20\) the memory returns its first pattern exactly (the weight on \(x_1\) is \(0.99999\)); at \(\beta = 3\) it returns “mostly \(x_1\), with the relevant neighbors mixed in”; at \(\beta = 0.58\) it returns an undifferentiated average of everything. The first row’s temperature, \(1/\sqrt{3}\), is the transformer’s own \(\beta = 1/\sqrt{d_k}\) for \(d_k = 3\). While the toy’s unit-norm patterns place this temperature deep in the averaging regime, a transformer’s query–key overlaps grow like \(\sqrt{d_k}\), so its logits are \(\mathcal{O}(1)\) after the scaling, and the same \(\beta\) operates at moderate sharpness.
Set \(Q = \xi\) as a row, \(K = V =\) the patterns as rows, \(d_k = 3\); then \(\operatorname{softmax}(QK^T/\sqrt{d_k})\,V\) is — symbol for symbol — the first row of the table. The memory retrieval at soft temperature and the attention head are the same arithmetic.
A transformer attention layer is one step of Hopfield retrieval.
8.6 Module 1 in retrospect
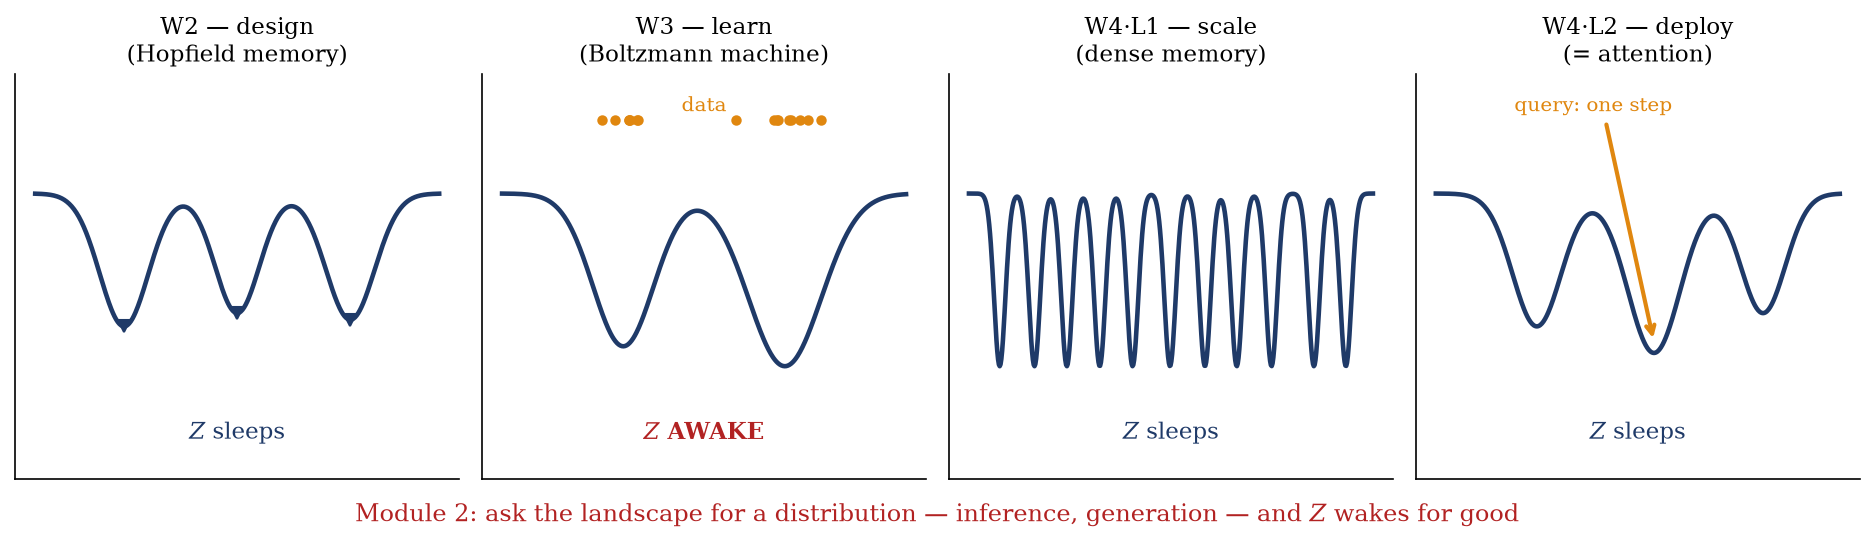
Module 1 began with an energy landscape over configuration space. Week 2 designed the landscape: Hopfield’s memory, with minima placed at the data by Hebb’s rule and retrieval as descent, capped at \(0.138\,N\), with nothing normalized. Week 3 learned it: heated, the network becomes a probability model, and fitting its couplings by maximum likelihood brings in \(\nabla_\theta \log Z\), a sum over \(2^N\) states that contrastive divergence approximates but does not remove. The previous lecture scaled it: the interaction function sets the capacity, which rises from \(138\) patterns to beyond the atom count of the universe. Today the landscape became continuous, and its one-step retrieval is the attention layer of the transformer architectures that now dominate language and vision. Figure 8.4 draws the four panels in a row, with the role of \(Z\) marked week by week.
Figure 8.4: Module 1 in four panels — one landscape, four verbs. Week 2 designs it (memory basins, nothing normalized); Week 3 learns it (basins molded under data, and the partition function enters as the training obstruction); Week 4 scales it (dense memory, exponentially many wells) and deploys it (a query descending in one step: attention).
Hopfield’s 1982 landscape and Vaswani’s 2017 attention are thus one picture, thirty-five years apart (Equation 8.3).
\(Z\) was absent in Week 2 (\(T = 0\), nothing normalized), central in Week 3 (learning a distribution), and absent again all through Week 4, where the only normalizers are finite: a softmax over patterns, which plays the role of the RBM’s tractable \(Z(v)\), never a sum over configurations. Whenever the landscape only retrieves, \(Z\) plays no role; whenever it must carry a normalized distribution, \(Z\) returns. Module 2 asks for distributions everywhere — inference over hidden variables, marginals of rugged systems, generative modeling proper — so from next week \(Z\) is present throughout, and the response changes from Week 3’s approximation of a gradient to the first principled approximation of the distribution itself. Week 5 builds mean-field theory and the variational free energy — the Gibbs–Bogoliubov bound that turns “compute \(\log Z\)” into “optimize over tractable families”; Week 6 sharpens it (TAP corrections, belief propagation); Week 7 carries it to latent-variable models and the variational autoencoder. Week 10 then removes the obstruction for generative modeling through \(\nabla_x \log Z = 0\), the derivative with respect to the configuration rather than the parameters.
Take-home 2 — the Module 1 capstone
The energy landscape, designed in Week 2, learned in Week 3 and scaled in Week 4, is the substrate of modern generative AI, and transformer attention is its retrieval step. The recurring obstruction is \(Z\), which appears exactly when the landscape must carry a normalized distribution; taming it — by approximation (M2), by sampling (M3), by elimination (M4) — is the rest of the course.
Bahdanau, Dzmitry, Kyunghyun Cho, and Yoshua Bengio. 2015. “Neural Machine Translation by Jointly Learning to Align and Translate.” In International Conference on Learning Representations (ICLR).
Hopfield, John J. 1982. “Neural Networks and Physical Systems with Emergent Collective Computational Abilities.”Proceedings of the National Academy of Sciences 79 (8): 2554–58. https://doi.org/10.1073/pnas.79.8.2554.
Krotov, Dmitry, and John J. Hopfield. 2021. “Large Associative Memory Problem in Neurobiology and Machine Learning.” In International Conference on Learning Representations (ICLR).
Ramsauer, Hubert, Bernhard Schäfl, Johannes Lehner, Philipp Seidl, Michael Widrich, Thomas Adler, Lukas Gruber, et al. 2021. “Hopfield Networks Is All You Need.” In International Conference on Learning Representations (ICLR).
Vaswani, Ashish, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017. “Attention Is All You Need.” In Advances in Neural Information Processing Systems (NeurIPS), 30:6000–6010.