Core (~1 h).Opper and Saad (2001), the editors’ introduction — the physics↔︎ML mean-field bridge in one book, and the variational-free-energy framing this lecture follows. Alongside it, Wainwright and Jordan (2008), §5 (with §3 for the exponential-family setup) — the machine-learning telling: variational inference as free-energy minimization over a tractable family; read for the ELBO/mean-field correspondence we make exact below. (For a shorter statistician’s account, Blei, Kucukelbir, and McAuliffe (2017).)
Optional background.Mehta et al. (2019), the variational-methods sections, in the course’s notation; MacKay (2003), Ch. 33, for the KL bound done cleanly from the inference side; Sethna (2021), the mean-field Ising sections, for the physics lineage — Weiss’s molecular field and the self-consistent equation; Jordan et al. (1999), the founding machine-learning reference for naive mean field.
Prerequisite reminder. The Boltzmann distribution and \(F = -T\log Z\) (Week 1); the Ising energy and the \(\langle\cdot\rangle\) bookkeeping (Weeks 2–3); \(D_\mathrm{KL}(q\|p) \geq 0\), flagged in Week 1 and used in earnest today; the two-state \(\tanh\)/sigmoid average (Section 1.6, Section 5.3). New content: the variational bound as a controlled approximation, its identity to the ELBO, and the mean-field self-consistent equations.
9.1 The normalizer returns
Module 1 closed with a pattern (Figure 8.4): the partition function plays no role whenever an energy landscape only retrieves, and becomes unavoidable whenever it must carry a normalized distribution. Module 2 begins where the partition function is unavoidable. Inference over hidden variables, marginals of an interacting model, the likelihood of data under an energy-based model — every one of these asks for \(p(x) = e^{-\beta E(x)}/Z\) as a distribution, and therefore for \(Z = \sum_x e^{-\beta E(x)}\) over \(2^N\) configurations, and therefore for the free energy \(F = -T \log Z\) that Week 1 identified as the central object and Week 3’s ledger (Section 5.7) showed to be intractable. Week 3 approximated the gradient\(\nabla_\theta \log Z\) by short sampling chains, accepting a bias. Now we face \(\log Z\) itself — and a different strategy is required.
We will not compute \(p\). We will pick a tractable distribution \(q\) and make it the best possible stand-in, and we will do it with a bound, so that the sign of the error is always known. Approximations whose error has a known sign are rare and valuable: they can be optimized, since pushing the bound further can only bring us closer to the truth, and they can be trusted, since the truth never lies on the excluded side.
The method has a double lineage, and the two lines turn out to be one. On the physics side, Weiss (1907) replaced each spin’s fluctuating neighbors by an average “molecular field” and obtained the self-consistent equation that predicts ferromagnetism — mean-field theory, the workhorse approximation of a century of statistical physics, later dignified into a variational bound by Bogoliubov, Peierls, and Feynman. On the inference side, machine learning adopted the same construction from the late 1980s, first to train Boltzmann machines, and developed it through the 1990s into variational inference(Jordan et al. 1999; Wainwright and Jordan 2008): approximate an intractable posterior by a tractable family, optimize a lower bound on the evidence. The physicist’s free-energy minimization and the machine-learner’s ELBO maximization are the same optimization of the same functional.
Since Week 3 we have absorbed \(\beta = 1\) into the couplings; from today temperature is a live control parameter again, written explicitly. Mean-field theory’s central application in physics is to locate phase transitions — and a transition lives at a critical temperature, which requires an explicit \(\beta\).
Take-home 1
When \(Z\) is intractable, do not compute \(p\) — approximate it by a tractable \(q\), chosen to minimize a bound on the free energy. Because \(F \leq F_q\) always holds, the approximation is controlled, and optimizing it can only approach the truth. Mean field is the simplest instance of this strategy, which runs through Module 2.
9.2 Two roads, and one picture
Week 3 identified two obstructions — normalization, and the sampling hardness that enforces it — and they now index the course’s two escape roads. Road one approximates the distribution: replace \(p\) by a tractable \(q\) and optimize — deterministic, fast, and equipped with a bound, with a bias fixed by the chosen family. That is this module. Road two samples the distribution: draw configurations from \(p\) without ever normalizing it — asymptotically exact, but stochastic and limited by mixing time on rugged landscapes. That is Module 3. Today we take road one, where any trial \(q\) yields the variational bound and the factorized\(q\) yields mean-field theory.
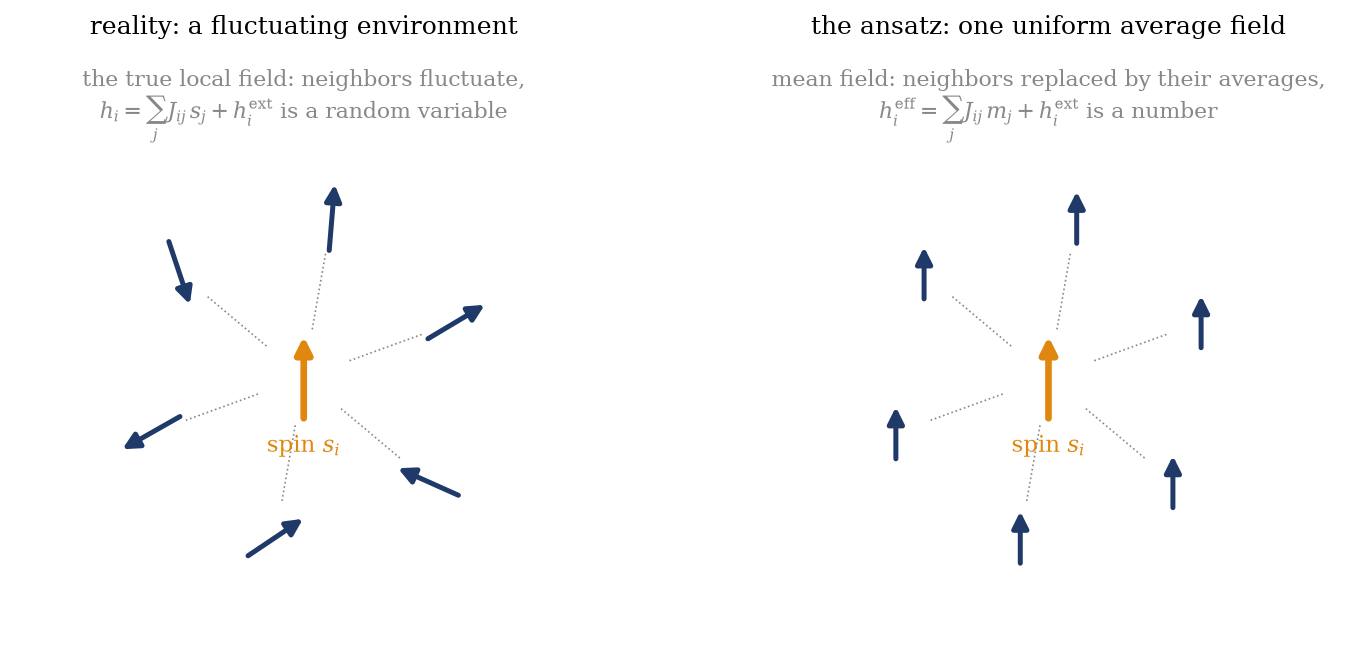
Figure 9.1 draws the physical idea. A spin in an interacting system feels the field of its neighbors — a fluctuating field, different in every configuration, correlated with the spin itself. Mean field replaces that fluctuating environment by its average: every neighbor \(s_j\) is frozen to its mean \(m_j\), and the spin responds to a single, deterministic effective field\(h_i^\text{eff} = \sum_j J_{ij} m_j + h_i\). The substitution would be exact if the neighbors did not fluctuate; its error is the fluctuation. Everything the approximation gets wrong, including the location and character of a phase transition in the next lecture, follows from this substitution.
Figure 9.1: The mean-field ansatz. Left: reality — a spin’s local field is built from neighbors that fluctuate, so the field is a random variable, correlated with the spin it acts on. Right: the mean-field ansatz — every neighbor is replaced by its average magnetization, and the spin sits in a single deterministic effective field \(h_i^{\text{eff}} = \sum_j J_{ij} m_j + h_i\). The substitution is exact if the neighbors do not fluctuate; the error is precisely the fluctuation — which is why mean field improves with connectivity (many neighbors average sharply) and fails where fluctuations dominate.
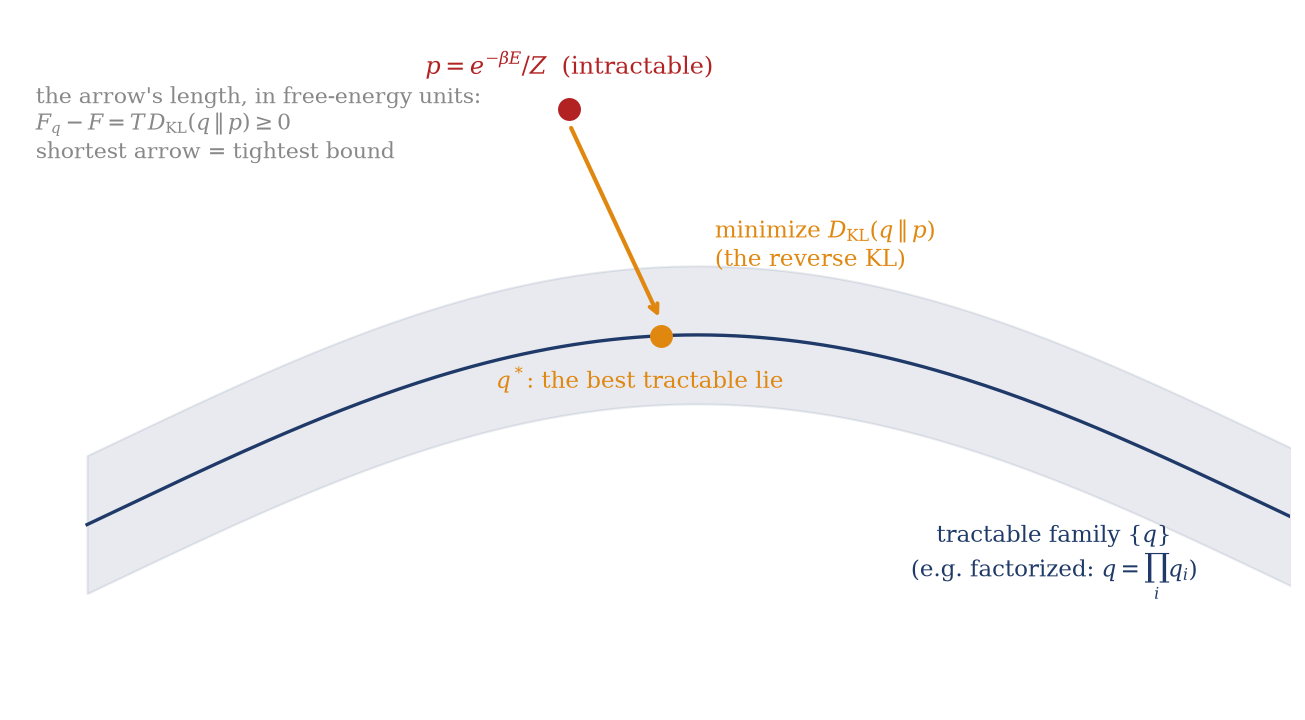
The formal version of the same move is a projection, and Figure 9.2 draws its geometry. The intractable \(p\) is a point in the space of distributions; the tractable candidates \(\{q\}\) — say, all factorized distributions — form a surface that does not contain it. Variational inference finds the point on the surface closest to \(p\), with distance measured by the Kullback–Leibler divergence — in a specific argument order with definite consequences. The next section supplies what the picture cannot: that the projection distance is exactly a free-energy difference, computable up to a constant without knowing \(Z\).
Figure 9.2: The variational principle as geometry: project the intractable \(p\) onto a tractable family. The triangle is the space of all distributions over \(x \in \{\pm 1\}^N\), and each point in it is one whole distribution — \(2^N\) probabilities summing to one — so the picture has no axes and plots neither energy nor configuration. For \(N = 2\) the space is a tetrahedron, and the factorized \(q_1(s_1)\,q_2(s_2)\) form a curved two-dimensional surface inside it, parametrized by \((m_1, m_2)\). The projection minimizes the reverse KL divergence \(D_\mathrm{KL}(q\|p)\) — the only order we can average under — and the gap it leaves, in free-energy units, is \(F_q - F = T\,D_\mathrm{KL}(q\|p) \geq 0\). The KL divergence is not a distance (it is asymmetric), so \(q^*\) need not be the point that looks closest in the drawing. Minimizing the variational free energy over the family therefore does two jobs at once: it finds the best tractable stand-in for \(p\), and it tightens a one-sided bound on the true free energy.
9.3 The Gibbs–Bogoliubov bound
We want a functional of \(q\) that ① is computable whenever \(q\) is tractable, ② upper-bounds the intractable \(F\), and ③ touches it exactly at \(q = p\). Week 1 supplied every ingredient.
Define the variational free energy of an arbitrary trial distribution \(q(x)\) over the configurations:
\[
F_q \;\equiv\; \langle E \rangle_q \;-\; T\, S[q]
\;=\; \sum_x q(x)\, E(x) \;+\; T \sum_x q(x) \log q(x).
\]
This is Week 1’s free energy \(F = \langle E \rangle - TS\) with the Boltzmann distribution replaced by \(q\) in both terms — an energy term and an entropy term, evaluated under the wrong distribution. Note what is absent: no \(Z\). Every term is an average under \(q\), computable exactly for any tractable family.
Compute the gap to the true \(F = -T \log Z\). Insert \(\log Z\) under the \(q\)-average (it is a constant), and reassemble:
\[
F_q - F
\;=\; \big\langle E + T \log q \big\rangle_q + T \log Z
\;=\; T \Big\langle \log q + \beta E + \log Z \Big\rangle_q
\;=\; T \Big\langle \log \frac{q(x)}{e^{-\beta E(x)}/Z} \Big\rangle_q
\;=\; T \Big\langle \log \frac{q}{p} \Big\rangle_q .
\]
Recognize the object on the right — it is the Kullback–Leibler divergence, and it is non-negative:
\[
\boxed{\; F_q - F \;=\; T\, D_\mathrm{KL}(q \,\|\, p) \;\geq\; 0,
\qquad\text{so}\qquad F \;\leq\; F_q, \quad \text{with equality iff } q = p. \;}
\tag{9.1}\]
Gibbs–Bogoliubov variational bound
As a bound, the variational free energy never dips below the truth — equivalently \(\log Z \geq -F_q / T\), a lower bound on the log-partition function, the first quantitative grip the course has had on the normalizer. As an objective, minimizing \(F_q\) over a tractable family simultaneously tightens the bound on \(F\)and finds the member of the family closest to \(p\) in KL — one optimization serving both goals, which is why the method took hold in both fields. As a diagnostic, the gap is a named information-theoretic quantity, and when we can compute it (as in the example below) it tells us exactly how much distribution we have thrown away. (The classic physics statement of the same inequality — \(F \leq F_0 + \langle H - H_0 \rangle_0\) for a trial Hamiltonian \(H_0\), the Peierls–Bogoliubov form — is the special case \(q = e^{-\beta H_0}/Z_0\), traditionally proved from the convexity of the exponential, \(\langle e^X \rangle \geq e^{\langle X \rangle}\); the KL route above is the same mathematics with the inference reading built in.)
Trap
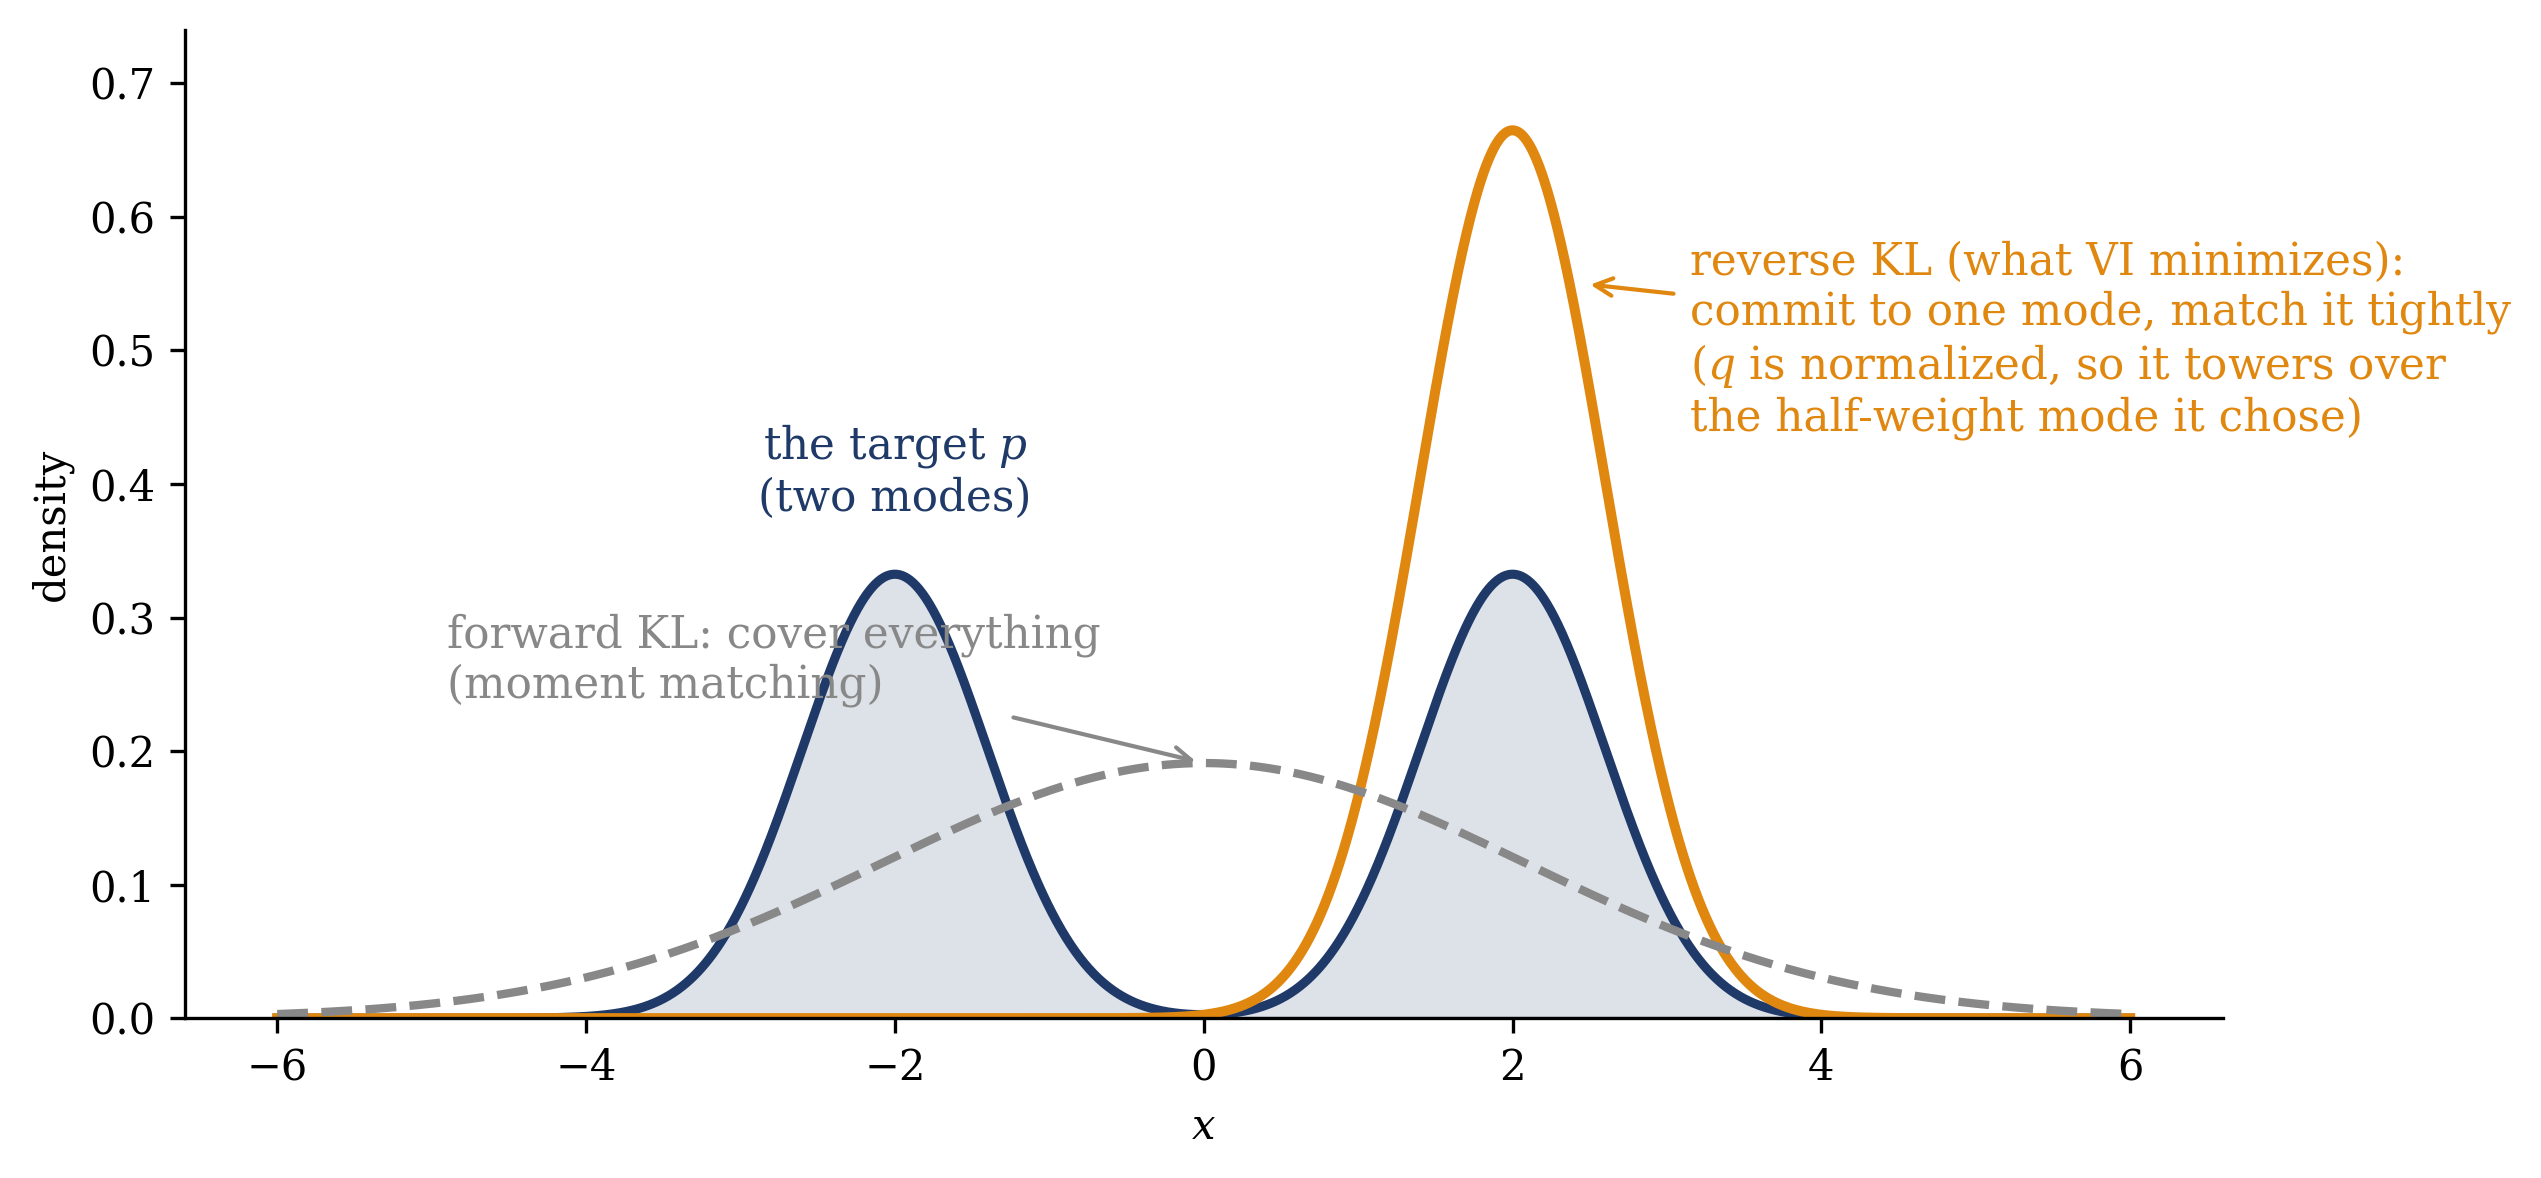
It is the reverse KL. The gap is \(D_\mathrm{KL}(q\|p)\) — averaged under \(q\) — not \(D_\mathrm{KL}(p\|q)\). The order is forced on us: we can only compute averages under the tractable distribution. The two divergences penalize different errors. The reverse KL explodes where \(q\) puts mass and \(p\) has none, so the optimal \(q\) is mode-seeking: it commits to one region of high \(p\) and is penalized little for ignoring the others, and it systematically underestimates variance. The forward KL would instead spread \(q\) to cover everything (Figure 9.3). Mean field’s overconfident magnetizations, below, are this asymmetry in another form.
Figure 9.3: The asymmetry of the two KL divergences, on the simplest instructive case: fit a single Gaussian \(q\) to a bimodal \(p\) (equal-weight modes at \(\pm 2\), width \(0.6\)). Minimizing the forward KL \(D_\mathrm{KL}(p\|q)\) (gray dashed) matches moments: the optimum straddles both modes, centered at zero with \(\sigma \approx 2.1\) — mass-covering, and placing much of its probability where \(p\) has almost none. Minimizing the reverse KL \(D_\mathrm{KL}(q\|p)\) (orange) — the divergence variational inference is forced to use — commits to a single mode and matches it tightly, ignoring the other. Mean field’s overconfidence is this picture at scale.
9.4 The bound is the ELBO
Week 3 left a second intractable sum behind. To make a Boltzmann machine expressive, we added degrees of freedom that are never observed, hidden units \(h\) beside the visible units \(v\) that carry the data, and traced them out (Section 5.6). The probability the model assigns to an observation is then a ratio of two partition functions,
where \(Z(v)\) is the partition function of the hidden units with the visibles clamped at \(v\), and \(F(v) = -T \log Z(v)\) is its free energy. An observation is improbable in proportion to the free energy it costs to hold the system at it. The distribution of the hidden units given the observation is the Boltzmann distribution of the clamped system, the global \(Z\) cancelling between numerator and denominator:
the probability of an observation is a free-energy cost
For a general Boltzmann machine the clamped hidden units stay coupled to one another, so \(Z(v)\) is a sum over \(2^{N_h}\) interacting configurations: the obstruction of this lecture, on a smaller system. The clamped system is, however, a Boltzmann system in its own right, with energy \(E(v, h)\) over the configurations \(h\), and Equation 9.1 applies to it unchanged. For any trial distribution \(q(h)\) over the hidden units,
Inserting the bound into Equation 9.2, and using \(\log p(v, h) = -\beta E(v, h) - \log Z\) to collect terms, turns it into a statement about the probability of the observation:
The right-hand side is a lower bound on the log-probability of the data, the evidence in the inference vocabulary, and machine learning calls it the evidence lower bound, or ELBO. Nothing was constructed to produce it: it is the Gibbs–Bogoliubov bound of the clamped system, read as a statement about how probable the observation is. The trial \(q(h)\) is an approximate posterior over the unobserved units, and the bound is tight exactly when \(q\) equals the true posterior \(p(h \mid v)\).
The argument used the Boltzmann form only to name the energy. A general latent-variable model, with data \(x\) and hidden variables \(z\) (cluster labels, latent codes, a layer of hidden units), specifies a joint \(p(x, z)\), and any normalized joint is a Boltzmann distribution at \(T = 1\) with energy \(-\log p(x, z)\) and \(Z = 1\). Clamping the data, the hidden variables see the energy \(E(z) = -\log p(x, z)\); their partition function is the evidence, their Boltzmann distribution the posterior, and their free energy the negative log-evidence,
So \(F \leq F_q\)is\(\log p(x) \geq \mathrm{ELBO}\): maximizing the evidence lower bound is minimizing a variational free energy, the same functional under a substitution of symbols. Since \(\log p(x)\) does not depend on \(q\), maximizing the ELBO over \(q\) both tightens the lower bound on the log-evidence and drives \(q\) towards the true posterior. The physicist bounding \(\log Z\) from below and the machine-learner bounding the log-evidence from below are running one optimization; Weiss’s molecular field and the inference step inside every VAE are one method, a century apart.
The two cases differ in the global normalizer. For the Boltzmann machine, \(\log p(v, h)\) contains \(-\log Z\), so the ELBO is known only up to that constant: enough to optimize \(q\), which is inference over the hidden units, but not to evaluate \(\log p(v)\), and the negative phase of learning still needs the sampling of Week 3. The latent-variable models of Week 7 are built from normalized pieces, \(p(z)\,p(x \mid z)\), so that \(Z = 1\) and the ELBO is a number one can compute and maximize over the model parameters as well. Table 9.1 collects the correspondence used for the next three weeks, at \(T = 1\).
Table 9.1: The physics ⇄ inference dictionary, at \(T = 1\). For a normalized model, \(Z = 1\) and \(F = 0\).
statistical physics (clamped system)
variational inference
observed units \(v\)
data \(x\)
hidden configuration \(h\)
latent variable \(z\)
energy \(E(v, h) + \log Z\)
\(-\log p(x, z)\)
clamped Boltzmann distribution \(e^{-E(v,h)}/Z(v)\)
posterior \(p(z \mid x)\)
clamped partition function, \(Z(v)/Z\)
evidence \(p(x)\)
free-energy cost \(F(v) - F\)
negative log-evidence \(-\log p(x)\)
trial distribution \(q(h)\)
variational posterior \(q(z)\)
variational free energy \(F_q(v) - F\)
\(-\,\mathrm{ELBO}(q)\)
gap \(F_q(v) - F(v) = D_\mathrm{KL}(q\|p)\)
\(\log p(x) - \mathrm{ELBO}\)
minimize the free energy
variational inference
9.5 Mean field: the factorized ansatz
The bound holds for any\(q\); it becomes a method the moment we commit to a family. Take the simplest tractable one: complete independence,
for Ising variables \(s_i = \pm 1\), parameterized by the per-spin magnetizations \(m_i = \langle s_i \rangle_q \in [-1, 1]\) — these are the variational parameters we will optimize. (A hygiene note: this \(m_i\) is a variational per-site magnetization, a knob we turn; Week 2’s overlap \(m\) was an order parameter of the true dynamics. Same letter, same physical flavor, different formal role.)
Evaluate the two halves of \(F_q\) for the Ising energy \(E = -\tfrac12 \sum_{i \neq j} J_{ij} s_i s_j - \sum_i h_i s_i\). The energy term is where the approximation acts: under a factorized \(q\), expectations of products split,
The first equality is the approximation itself: the factorization sets every connected correlation \(\langle s_i s_j \rangle - \langle s_i \rangle \langle s_j \rangle\) identically to zero. That is the entire price of tractability, localized in one line. The entropy term, by contrast, is exact for the family and splits by independence into a sum of binary entropies,
Now minimize \(F_q = \langle E \rangle_q - T \sum_i s(m_i)\) over each \(m_i\). The energy contributes \(\partial \langle E \rangle_q / \partial m_i = -\big( \sum_j J_{ij} m_j + h_i \big) \equiv -h_i^\text{eff}\) (the \(\tfrac12\) canceling the \(ij\)/\(ji\) double count, the same bookkeeping as Week 3’s gradient); the entropy contributes \(\partial s(m_i)/\partial m_i = -\operatorname{artanh}(m_i)\) (differentiate the binary entropy and the logs collapse). Stationarity, \(-h_i^\text{eff} + T \operatorname{artanh}(m_i) = 0\), then inverts to
— the mean-field equations, which derive the cartoon of Figure 9.1. Each spin responds — with Week 1’s exact two-state Boltzmann average, the \(\tanh\) — to the average field of its neighbors rather than their fluctuating states. And the equations are self-consistent: the magnetizations determine the effective fields that determine the magnetizations, a loop closed on itself. That loop is where all the physics of the next lecture lives — a closed loop can sustain a solution with no external cause, which is what spontaneous magnetization is.
In physical terms this is Weiss’s molecular-field equation of 1907 (Weiss 1907) — but where Weiss posited the average field, we have derived it as the optimum of a variational bound, so we know exactly what was discarded (the correlations) and in which direction the answer errs (\(F_q \geq F\)). To solve the equations, sweep the sites and update each \(m_i \leftarrow \tanh(\beta h_i^\text{eff})\) from the current neighbors. Each update is an exact minimization of \(F_q\) in that coordinate with the others frozen, so the sweep is coordinate descent on \(F_q\): the variational free energy never increases, and the lower bound \(\log Z \geq -\beta F_q\) never loosens. In the Ising model as written nothing is observed, so there is no evidence to bound; the object being bounded is the log-partition function of the whole system.
The clamped case. The ELBO of Section 9.4 appears as soon as part of the system is observed. Split the spins of a Boltzmann machine into visible units \(v_i\), clamped at the data, and hidden spins \(s_a\) (the hidden configuration \(h\) of Section 9.4, renamed so that \(h\) keeps its meaning of a field), with hidden–hidden couplings \(J_{ab}\), hidden fields \(h_a\) and visible–hidden couplings \(W_{ia}\). With \(v\) fixed, the terms of \(E(v, s)\) that involve only visibles are constants, and the coupling term \(-\sum_{i,a} W_{ia} v_i s_a\) is linear in each \(s_a\): the observation acts on the hidden spins as an additional external field. The factorized \(q(s) = \prod_a q_a(s_a)\) applied to the clamped system therefore gives the same equations with that field added,
and the same sweep is now coordinate descent on \(F_q(v)\). Since \(\log p(v) \geq -\beta\,[F_q(v) - F]\) with \(F\) independent of \(q\), lowering \(F_q(v)\) is raising the ELBO, and here the sweep is what machine learning calls naive mean-field variational inference: coordinate ascent on the ELBO, with \(m_a\) the approximate posterior mean of hidden unit \(a\) given the observation. The general-family version of the update, \(q_a \propto \exp \langle \log p(v, s) \rangle_{q_{\setminus a}}\), is the CAVI algorithm of the ML textbooks (Blei, Kucukelbir, and McAuliffe 2017; Jordan et al. 1999). For a restricted Boltzmann machine, \(J_{ab} = 0\), the right-hand side no longer contains the \(m_b\): the equations are solved in one step, the factorized \(q\) equals the true posterior (Week 3’s conditional independence of the hidden units), and the gap vanishes. The approximation acts only through the couplings among the unobserved units.
When is the approximation accurate? The cartoon answers: mean field is the exact theory of a system whose spins do not fluctuate about their means, so its quality is set by the sharpness of the average field. A spin with \(z\) neighbors feels an effective field that is a sum of \(z\) terms; its relative fluctuation scales as \(1/\sqrt{z}\). High connectivity — high dimension, dense graphs, the fully-connected models of Weeks 2–4, and (not coincidentally) the wide dense layers of modern machine learning — is where mean field is most accurate. Low dimension and the vicinity of a critical point, where fluctuations are the whole story, are where it fails — instructively, as the next lecture will show. And one more standing warning: the self-consistent equations may have several solutions (that multiplicity is exactly how the phase transition will appear); the variational principle selects the solution with the lowest \(F_q\).
Take-home 2
The factorized ansatz \(q = \prod_i q_i\) turns the bound into mean-field theory, with each spin in the average field of its neighbors. The price is exact and structural: all connected correlations are set to zero. Iterating the equations is coordinate descent on \(F_q\), monotonically tightening the bound on \(\log Z\); with visible units clamped at data, the same sweep is naive mean-field variational inference, coordinate ascent on the ELBO. The approximation is best at high connectivity (\(1/\sqrt{z}\) field fluctuations) and worst near criticality.
9.6 Example: the bound in action
We take one small model where the truth is computable, so that the bound, the gap, and the discarded correlations are all visible: \(N = 6\) spins, fully connected with ferromagnetic couplings \(J_{ij} = J_0/N\) (\(J_0 = 1\) — the model the next lecture pushes to its \(N \to \infty\) limit), plus a small symmetry-breaking field \(h = 0.05\). With \(2^6 = 64\) states, exact enumeration gives \(Z\), \(F\), and every moment; solving Equation 9.5 by iteration gives the mean-field \(m_i\) and \(F_q\). The comparison, across temperature:
\(T\)
exact \(F\)
mean-field \(F_q\)
gap \(= T\,D_\mathrm{KL}(q\|p)\)
exact \(\langle s_i \rangle\)
mean-field \(m_i\)
\(3.0\)
\(-12.561\)
\(-12.480\)
\(0.081\)
\(0.022\)
\(0.023\)
\(1.0\)
\(-4.514\)
\(-4.201\)
\(0.313\)
\(0.131\)
\(0.262\)
\(0.7\)
\(-3.519\)
\(-3.214\)
\(0.305\)
\(0.263\)
\(0.742\)
\(0.3\)
\(-2.844\)
\(-2.805\)
\(0.039\)
\(0.754\)
\(0.994\)
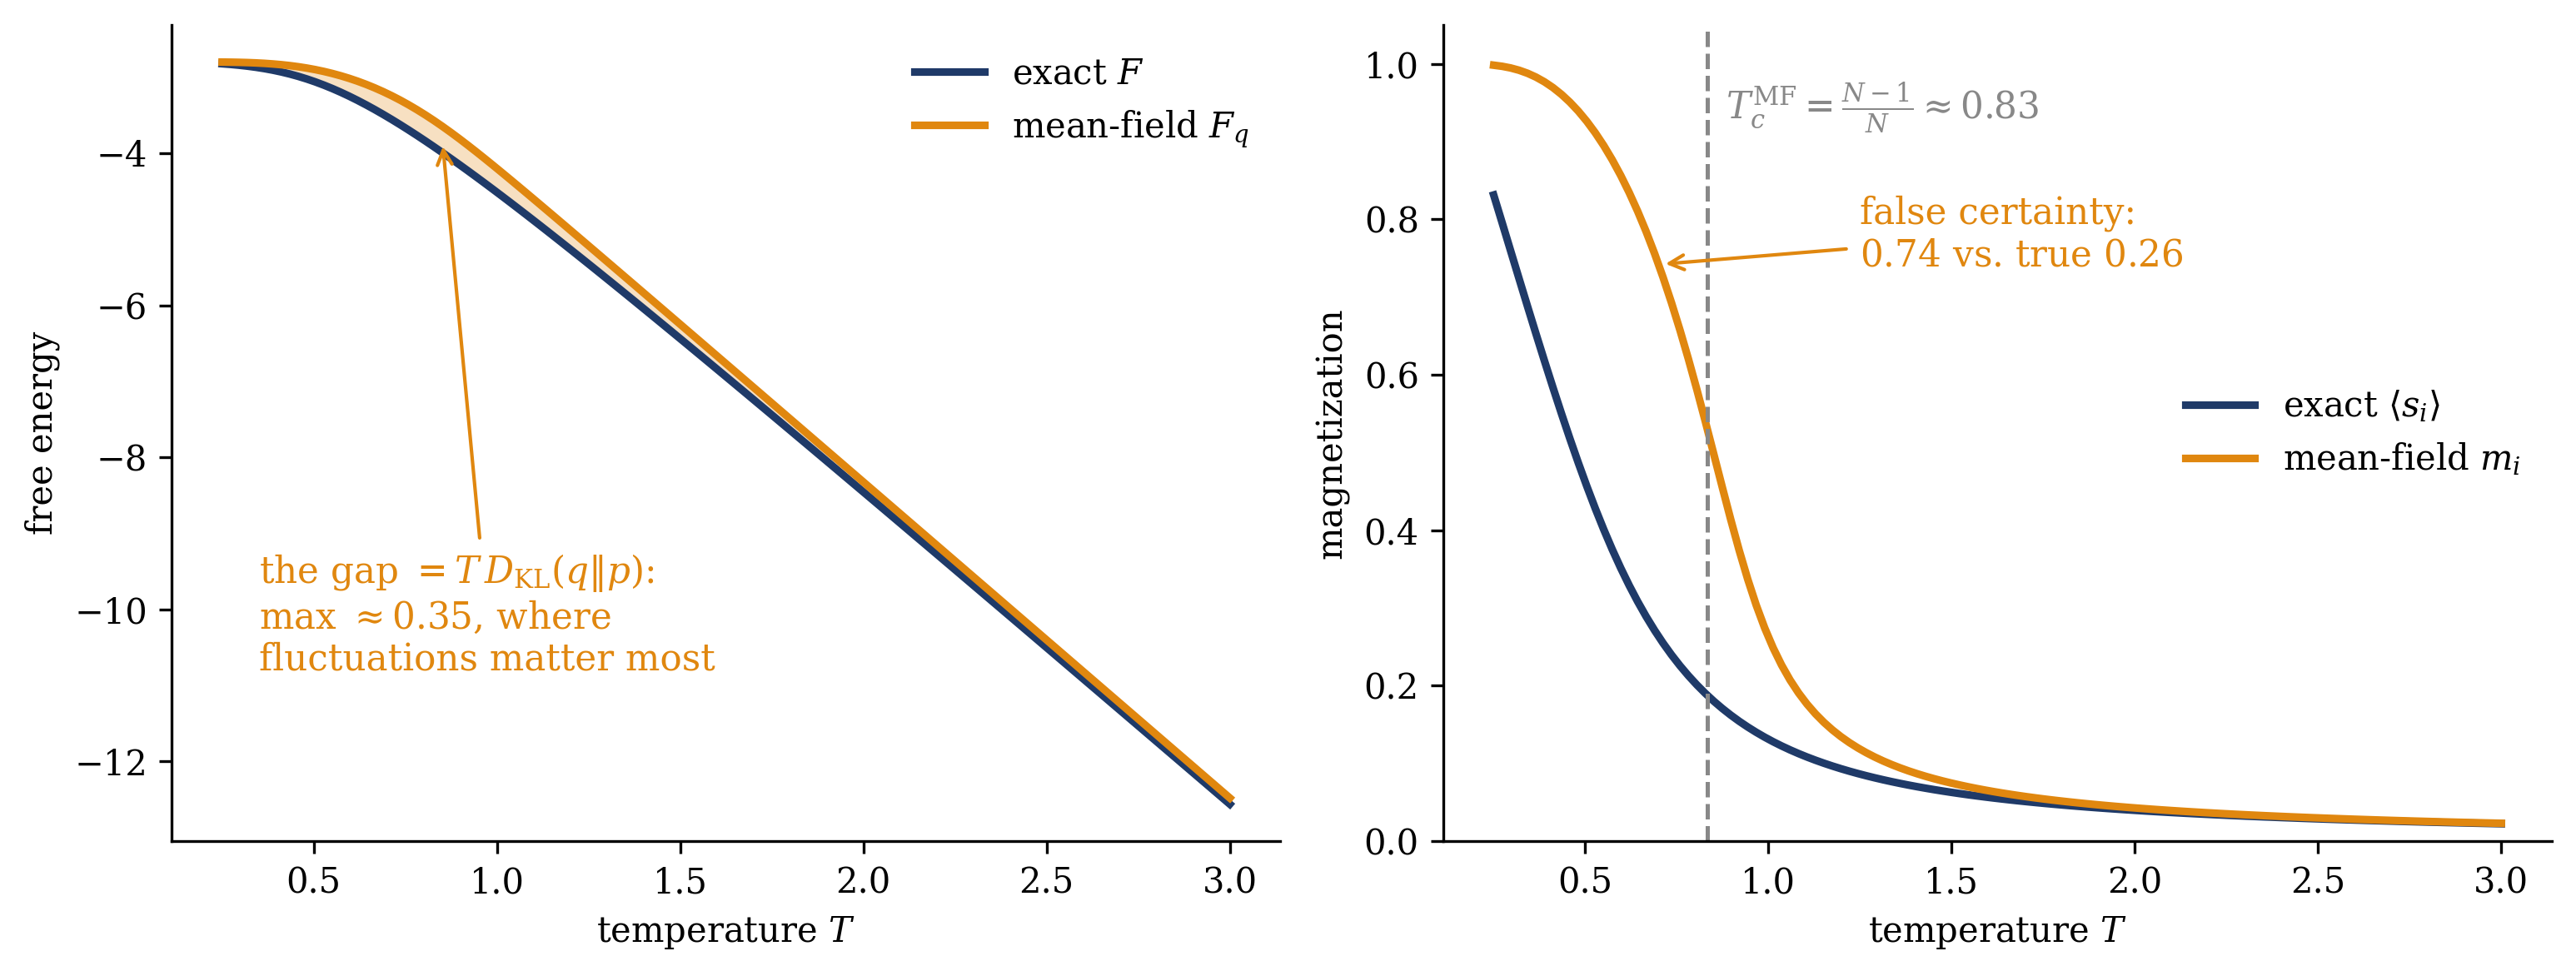
Each column tests one claim of the lecture. The gap column is never negative — the bound Equation 9.1, made numerical (and computed two independent ways in the code below: as \(F_q - F\), and directly as \(T \sum_s q \log(q/p)\) over all \(64\) states; they agree to machine precision). The gap is small at high temperature, where spins are nearly independent and the factorized family nearly contains the truth; small again at very low temperature, where the system freezes into an essentially factorized ordered state; and largest in between — peaking at \(0.35\) near \(T \approx 0.85\), about a tenth of the free energy — precisely where correlated fluctuations are strongest. The magnetization columns show the reverse-KL signature: at \(T = 0.7\) the exact magnetization is \(0.26\), but mean field reports \(0.74\). The factorized \(q\) cannot represent correlated fluctuations and lowers \(F_q\) by overcommitting to order, the mode-seeking of Figure 9.3 realized in spins. Figure 9.4 draws both columns as curves, and marks the temperature \(T_c^\text{MF} = (N-1)J_0/N \approx 0.83\) where the next lecture will have much to say: mean field predicts a sharp onset of order there, while the exact six-spin system — which, being finite, has no phase transition at all — crosses over smoothly. The gap peaks in exactly that neighborhood. The approximation is least trustworthy where it predicts a sharp transition, a diagnosis the next lecture turns into theory.
Show code
N, J0, h =6, 1.0, 0.05J = J0 / N * (np.ones((N, N)) - np.eye(N))S = np.array([[(c >> i &1) *2-1for i inrange(N)] for c inrange(2**N)], dtype=float)E =-0.5* np.einsum("ci,ij,cj->c", S, J, S) - h * S.sum(axis=1)def exact(T): w = np.exp(-E / T) Z = w.sum(); p = w / Zreturn-T * np.log(Z), (p[:, None] * S).sum(axis=0)[0], pdef meanfield(T): m = np.full(N, 0.9)for _ inrange(5000): m_new = np.tanh((J @ m + h) / T)if np.abs(m_new - m).max() <1e-12:break m =0.7* m +0.3* m_new Eq =-0.5* m @ J @ m - h * m.sum() Sq = np.sum(-(1+ m) /2* np.log((1+ m) /2) - (1- m) /2* np.log((1- m) /2))return Eq - T * Sq, mTs = np.linspace(0.25, 3.0, 120)Fex, Fq, mex, mmf = [], [], [], []for T in Ts: F, m0, p = exact(T) Fqv, m = meanfield(T) q = np.prod((1+ S * m) /2, axis=1) # the factorized q, enumeratedassertabs((Fqv - F) - T * (q * np.log(q / p)).sum()) <1e-8# gap = T*KL, verified Fex.append(F); Fq.append(Fqv); mex.append(m0); mmf.append(m[0])Fex, Fq, mex, mmf =map(np.array, (Fex, Fq, mex, mmf))Tc = (N -1) * J0 / Nfig, (a1, a2) = plt.subplots(1, 2, figsize=(10.4, 4.0))a1.plot(Ts, Fex, color=NAVY, lw=2.2, label=r"exact $F$")a1.plot(Ts, Fq, color=ORANGE, lw=2.2, label=r"mean-field $F_q$")a1.fill_between(Ts, Fex, Fq, color=ORANGE, alpha=0.25)k = np.argmax(Fq - Fex)a1.annotate(rf"the gap $= T\,D_{{\rm KL}}(q\|p)$:"f"\nmax $\\approx {np.max(Fq-Fex):.2f}$, where""\nfluctuations matter most", xy=(Ts[k], (Fex[k] + Fq[k]) /2), xytext=(0.35, -10.8), color=ORANGE, fontsize=10.5, arrowprops=dict(arrowstyle="->", color=ORANGE, lw=1))a1.set_xlabel(r"temperature $T$"); a1.set_ylabel("free energy")a1.legend(frameon=False, fontsize=10, loc="upper right")a2.plot(Ts, mex, color=NAVY, lw=2.2, label=r"exact $\langle s_i\rangle$")a2.plot(Ts, mmf, color=ORANGE, lw=2.2, label=r"mean-field $m_i$")a2.axvline(Tc, color=GRAY, ls="--", lw=1.2)a2.text(Tc +0.05, 0.93, r"$T_c^{\rm MF} = \frac{N-1}{N} \approx 0.83$", color=GRAY, fontsize=10.5)a2.annotate("overconfident:\n$0.74$ vs. true $0.26$", xy=(0.7, 0.742), xytext=(1.25, 0.74), color=ORANGE, fontsize=10.5, arrowprops=dict(arrowstyle="->", color=ORANGE, lw=1))a2.set_xlabel(r"temperature $T$"); a2.set_ylabel("magnetization")a2.set_ylim(0, 1.05)a2.legend(frameon=False, fontsize=10, loc="center right")fig.tight_layout(); plt.show()
Figure 9.4: The bound in action: exact versus mean-field thermodynamics of a fully-connected \(N = 6\) ferromagnet (\(J_{ij} = 1/N\), \(h = 0.05\)), exact values from enumeration of all \(64\) states. Left: the true free energy \(F\) (navy) and the variational \(F_q\) (orange) — \(F_q\) never dips below \(F\), and the shaded gap, equal to \(T\,D_\mathrm{KL}(q\|p)\) by Equation 9.1 (verified in the code by direct enumeration of the KL), peaks at \(\approx 0.35\) near the mean-field critical temperature and closes at both ends. Right: the magnetizations. Mean field (orange) switches on sharply near \(T_c^{\mathrm{MF}} = (N{-}1)/N \approx 0.83\) (dashed) — a transition the finite system does not have — while the exact finite system (navy) crosses over smoothly; at \(T = 0.7\) the approximation reports \(m = 0.74\) against a true \(0.26\). Overconfident order is the reverse-KL signature: the factorized family has no room for fluctuations and compensates with spurious order.
The mean-field free energy is never below the truth — that is the guarantee: we are always wrong in one known direction, by exactly a KL divergence.
The next lecture takes Equation 9.5 to the ferromagnet proper — uniform couplings, \(h = 0\), \(N \to \infty\) — where a nonzero magnetization appears spontaneously below a critical temperature: a phase transition, falling out of a variational approximation, with an order parameter and a critical exponent.
Take-home 3
On a brute-forceable model the guarantee is visible: \(F_q \geq F\) at every temperature, by exactly \(T\,D_\mathrm{KL}(q\|p)\), with the gap largest where correlated fluctuations are strongest, near the transition mean field predicts. There the mean-field magnetizations are overconfident, the reverse-KL mode-seeking in spins; at weak coupling the approximation is nearly exact.
9.7 Outlook: a phase transition from an approximation
Confronted with an intractable \(Z\), we replaced the true distribution by a tractable approximation, chosen by minimizing a one-sided bound whose gap is a KL divergence, and found that the physicist’s version of this construction (Gibbs–Bogoliubov, Weiss’s molecular field) and the machine-learner’s (the ELBO, variational inference) are one functional. The dictionary of Table 9.1 applies throughout Module 2.
The next lecture applies the method to the uniform ferromagnet: the self-consistency \(m = \tanh(\beta z J m)\)breaks symmetry — below \(T_c = zJ\) the disordered solution destabilizes and the system magnetizes spontaneously, with the square-root onset \(m \sim (T_c - T)^{1/2}\) — a genuine collective phase transition, predicted by an approximation that ignores every correlation. But the same approximation overestimates \(T_c\) (it ignores the fluctuations that fight order), predicts a transition even in one dimension where none exists, and gets the critical exponents wrong — because at criticality fluctuations are not a correction but the dominant effect. Restoring the discarded correlations systematically is Week 6’s agenda: the TAP correction (Thouless, Anderson & Palmer 1977, who corrected the very Sherrington–Kirkpatrick model Week 2 leaned on) and belief propagation, which is exact on trees. The machine-learning arrow runs parallel: naive mean-field VI is the workhorse of scalable Bayesian inference, and Week 7 builds the variational autoencoder on the same bound.
Blei, David M., Alp Kucukelbir, and Jon D. McAuliffe. 2017. “Variational Inference: A Review for Statisticians.”Journal of the American Statistical Association 112 (518): 859–77. https://doi.org/10.1080/01621459.2017.1285773.
Jordan, Michael I., Zoubin Ghahramani, Tommi S. Jaakkola, and Lawrence K. Saul. 1999. “An Introduction to Variational Methods for Graphical Models.”Machine Learning 37 (2): 183–233. https://doi.org/10.1023/A:1007665907178.
MacKay, David J. C. 2003. Information Theory, Inference, and Learning Algorithms. Cambridge: Cambridge University Press.
Mehta, Pankaj, Marin Bukov, Ching-Hao Wang, Alexandre G. R. Day, Clint Richardson, Charles K. Fisher, and David J. Schwab. 2019. “A High-Bias, Low-Variance Introduction to Machine Learning for Physicists.”Physics Reports 810: 1–124. https://doi.org/10.1016/j.physrep.2019.03.001.
Opper, Manfred, and David Saad, eds. 2001. Advanced Mean Field Methods: Theory and Practice. Cambridge, MA: MIT Press.
Sethna, James P. 2021. Statistical Mechanics: Entropy, Order Parameters, and Complexity. 2nd ed. Oxford: Oxford University Press.
Wainwright, Martin J., and Michael I. Jordan. 2008. “Graphical Models, Exponential Families, and Variational Inference.”Foundations and Trends in Machine Learning 1 (1–2): 1–305. https://doi.org/10.1561/2200000001.
Weiss, Pierre. 1907. “L’hypothèse Du Champ Moléculaire Et La Propriété Ferromagnétique.”Journal de Physique Théorique Et Appliquée 6 (1): 661–90. https://doi.org/10.1051/jphystap:019070060066100.