27Synthesis: thirteen weeks, one variational principle
Recommended reading
Core (light).Jaynes (1957) §1–4, re-read. The paper that Week 1 leaned on for the maximum-entropy derivation of Equation 1.2 is also the origin of today’s frame: the Boltzmann distribution as the solution of a variational problem, with everything else a consequence. Alongside it, Welling, Lu, and Holdijk (2026), the companion text, which tells the same story from the free-energy face rather than the \(Z\) face; reading the two against each other is good preparation for the synthesis.
Optional (retrospective pointers, not new reading). The Gibbs–Bogoliubov section of Week 5 (Section 9.3), where the identity derived below first appeared as a tool. The ELBO identity (Equation 9.4) and its VAE incarnation (Equation 14.6). The six-station spine figure of Week 12 (Figure 24.4), which Figure 27.1 completes. Tishby, Pereira, and Bialek (1999) — the seventh stance.
Prerequisite reminder. Everything the course boxed. New content: none. The lecture shows that the identity \(F = -T \log Z\) and the variational free energy \(F[q]\) underlie all thirteen weeks, and collects the course’s methods in a single table.
27.1 The whole map
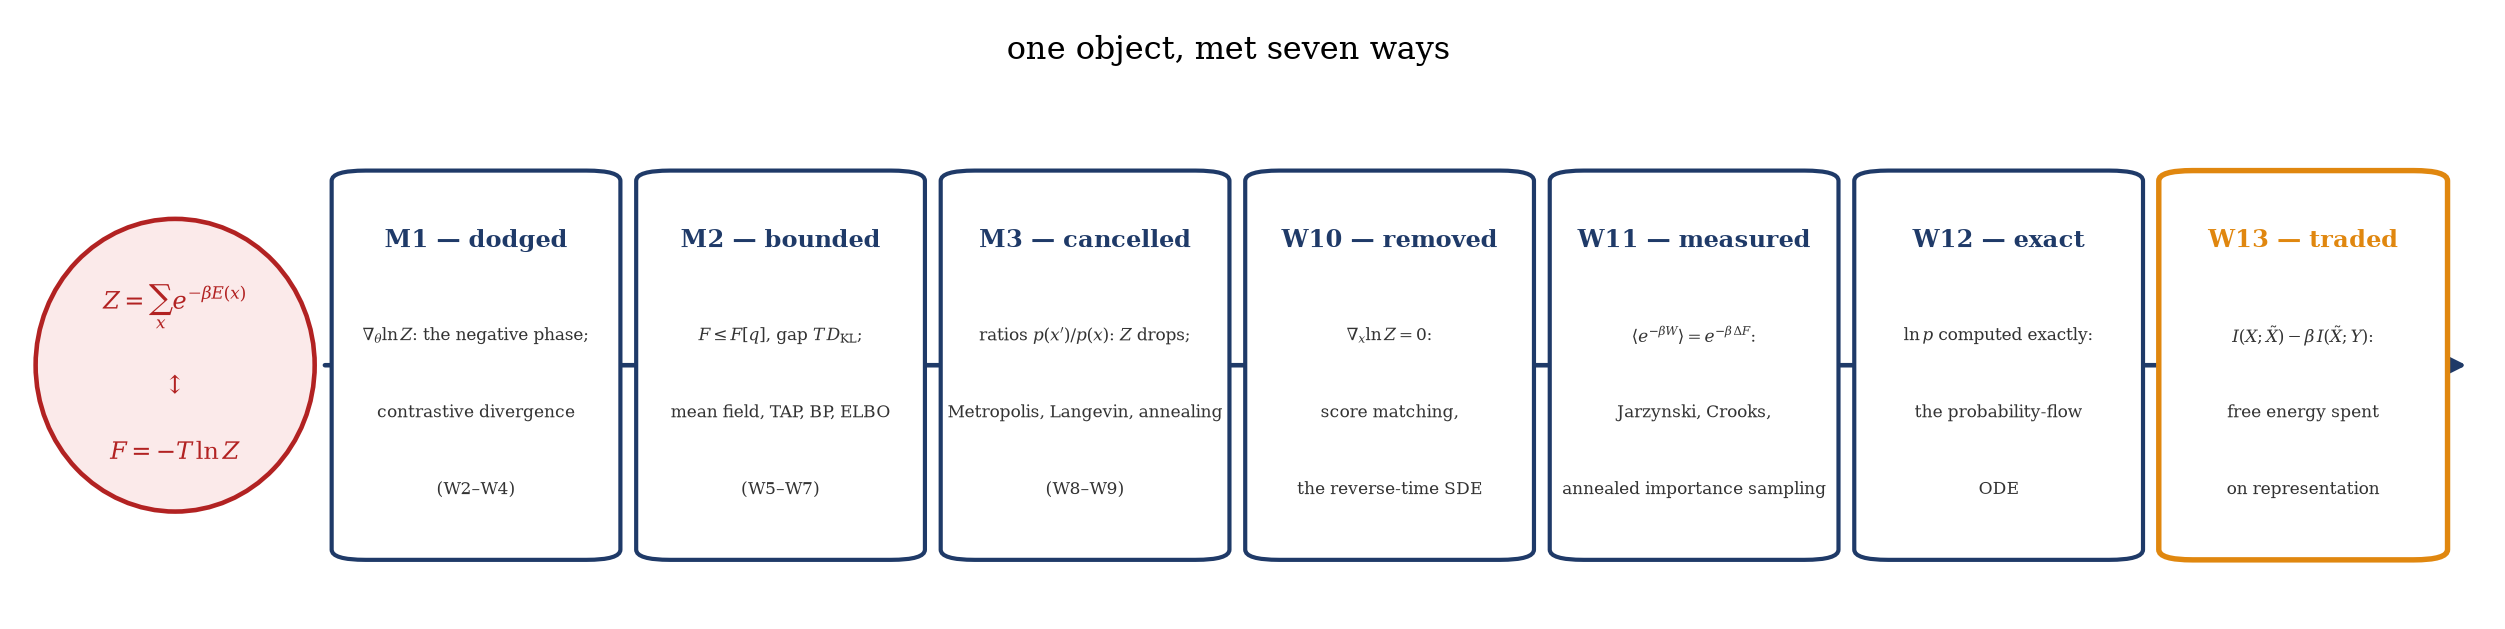
Week 1 opened with a thesis: statistical physics supplied machine learning with much of its modeling and inferential machinery, and the course would demonstrate the claim method by method. Thirteen weeks later the demonstration is complete, and like any demonstration by cases it risks reading as a catalog. We built energy-based memories, a variational toolbox, samplers, a nonequilibrium theory of generative models, and an information-theoretic coda, and each module closed with its own boxed results. Whether these are thirteen techniques or one idea worked out thirteen times is decided by the organizing object, the partition function \(Z = \sum_x e^{-\beta E(x)}\), easy to write and generally hard to compute. The modules form a sequence of stances toward it, and the sequence has a logic. Figure 27.1 draws it, extending the six-station figure that closed Week 12 (Figure 24.4) by the station Module 5 added.
Figure 27.1: The completed spine of the course: one object, met seven ways. Module 1 dodged the obstruction — the negative phase \(\nabla_\theta \log Z\) of Equation 5.5 blocked maximum-likelihood training, and contrastive divergence sidestepped it with a short chain (Week 3). Module 2 bounded it: \(F \leq F[q]\) for every trial distribution, with mean field and the ELBO as choices of family, and TAP and belief propagation as corrections of the functional that trade the bound for accuracy (Weeks 5–7). Module 3 cancelled it inside Metropolis ratios and Fokker–Planck stationary measures, at the price of mixing time (Weeks 8–9). Week 10 removed it from the learning problem altogether, since \(\nabla_x \log Z = 0\). Week 11 measured it, delivering \(\log Z\) as a nonequilibrium free-energy difference. Week 12 made the likelihood exact through the probability-flow ODE. Week 13 traded compression against relevance inside it, minimizing the free energy of a representation under an information budget. The red ellipse is the claim of Section 27.5 — the two faces at the left are one object.
The map also settles a motif the course has used once per module and never yet named as a theme. Three times, a statistical-physics result sat in the literature for decades until machine learning needed it: Onsager’s reaction field of 1936 (Onsager 1936) became the TAP correction of spin-glass theory (Thouless, Anderson, and Palmer 1977) and then the stabilizing term of approximate message passing (Week 6); Bethe’s 1935 superlattice approximation (Bethe 1935) became belief propagation’s free energy (Yedidia, Freeman, and Weiss 2003); and Anderson’s 1982 reverse-time diffusion theorem (Anderson 1982) became the generative half of every diffusion model (Week 10). Jarzynski’s 1997 work relation (Jarzynski 1997) is the exception: Neal reached the same identity inside MCMC within a year (Neal 2001), and the path-space reasoning around it was the starting point of the first diffusion model (Sohl-Dickstein et al. 2015), whose bound Week 12 obtained as Week 5’s clamped construction on paths. The pattern is the practical content of the course’s thesis: the methods transfer because the problem transfers: a Boltzmann distribution with an intractable normalizer is the same mathematical object whether \(x\) is a spin configuration or an image, and results proved about the object travel with it.
27.2 Two faces of one object
The course has appeared to run on two rails. The narrative rail is \(Z\): the normalization that made Boltzmann-machine training intractable (Equation 5.5), the constant that Metropolis ratios cancel (Equation 15.3), the term whose configuration-gradient vanishes for score matching (Equation 19.1). The methodological rail is the free energy: Module 2 minimized a variational \(F[q]\), Week 8 cooled one, Week 11 measured differences of one, Week 13 traded compression against relevance inside one. The two rails are connected by an identity the course has carried since its first lecture,
\[
\boxed{\; F \;=\; -\,T \log Z \;=\; \langle E \rangle - T\,S, \;}
\tag{27.1}\]
the two faces of the spine
The partition function and the free energy are therefore a single object. Whenever a week led with \(Z\), it was because the obstruction was easiest to point at on that face; whenever a week led with \(F\), it was because the variational structure was easiest to state there.
Week 1 obtained the Boltzmann distribution Equation 1.2 by maximizing the entropy \(S = -\sum_x p(x) \log p(x)\) at fixed mean energy (Jaynes 1957) — a variational statement. Since our entropies are in nats (\(k_B = 1\)), the \(S\) of that derivation is simultaneously the information entropy of Week 13; there is no conversion factor anywhere in the course. The whole spine therefore descends from one variational principle, and the derivation below runs that principle in reverse: instead of maximizing entropy to find\(p\), we minimize free energy to approach it.
27.3 The variational free energy as the frame
Week 5 met the Gibbs–Bogoliubov bound as the license for mean-field theory, derived it (Equation 9.1), and spent a module exploiting it. Every subsequent method of the course either tightens, saturates, or sidesteps that inequality, and we derive it once more here as the frame of the course.
We fix notation for the whole course. The trial distribution is \(q\) throughout — always the variational object, never a data distribution — and we write \(F[q]\) for what Week 5 called \(F_q\), to emphasize that it is a functional on distributions; the one exception is the previous lecture, where \(q\) counted the groups of the block model. The letter \(T\) is a temperature again (Week 12’s use of \(T\) as the diffusion horizon is retired), and the course has now used three distinct \(\beta\)’s: the thermal \(\beta = 1/T\) of every module, the noise schedule \(\beta_t\) of the diffusion weeks, and the information-bottleneck trade-off multiplier \(\beta\) of Week 13. Each enforces a constraint, but they are distinct quantities and must not be conflated. Sums over \(x\) carry over to integrals \(\int \mathrm{d}x\) everywhere, as they have since Module 3.
For any distribution \(q(x)\), define the variational free energy by transplanting the equilibrium formula \(F = \langle E \rangle - TS\) onto the trial state:
\[
F[q] \;=\; \langle E \rangle_q \;-\; T\,S[q]
\;=\; \sum_x q(x)\,E(x) \;+\; T \sum_x q(x) \log q(x).
\]
The target of every inference problem in this course is the Boltzmann distribution \(p(x) = e^{-\beta E(x)}/Z\) (Equation 1.2). Inverting it expresses the energy in terms of the target, \(E(x) = -T\big[\log p(x) + \log Z\big]\), and substituting into \(F[q]\) is the entire derivation:
\[
\begin{aligned}
F[q]
&= -\,T \sum_x q(x) \big[ \log p(x) + \log Z \big] \;+\; T \sum_x q(x) \log q(x) \\[2pt]
&= -\,T \log Z \, \underbrace{\sum_x q(x)}_{=\,1} \;+\; T \sum_x q(x) \log \frac{q(x)}{p(x)} \\[2pt]
&= -\,T \log Z \;+\; T\, D_\mathrm{KL}(q \,\|\, p).
\end{aligned}
\]
The Kullback–Leibler term is nonnegative — Gibbs’ inequality, proved in two lines: since \(\log u \leq u - 1\) with equality only at \(u = 1\),
with equality if and only if \(q = p\) everywhere. Combining the two displays gives the master result:
\[
\boxed{\; F[q] \;=\; -\,T \log Z \;+\; T\, D_\mathrm{KL}(q \,\|\, p) \;\;\geq\;\; -\,T \log Z \;=\; F[p], \qquad \text{equality iff } q = p. \;}
\tag{27.2}\]
Gibbs–Bogoliubov, as the frame of the course
⇒ The variational free energy of any trial state sits above the true free energy by exactly \(T\) times the information-theoretic distance to the target — the approximation error of a variational method is not vague; it is a KL divergence you can name before you compute anything.
Equation 27.2 admits three readings. Read as a bound, it says \(\log Z \geq -F[q]/T\): any tractable \(q\) yields a certificate on the log-partition function, which is Module 2. Read as an objective, it says that minimizing \(F[q]\) over a family simultaneously tightens the bound and finds the family member closest to \(p\) in KL — the dual role that connects magnetism (Week 5) with Bayesian inference (Week 7). Read as a limit, it says the floor is reached only at \(q = p\) itself: a method that insists on zero gap must produce the exact Boltzmann distribution, which is what sampling does and why Module 3 exists.
Take-home 1
The partition function and the free energy are one object (Equation 27.1), and Equation 27.2 names the error of every variational method as a KL divergence. Minimizing \(F\) over a restricted family bounds \(\log Z\); saturating the bound is exact sampling; and a method that differentiates \(\log p\) only with respect to \(x\) never sees \(Z\).
27.4 The read-off
A method is a specialization of Equation 27.2 when it supplies the identity’s ingredients: a family in which the trial \(q\) may live, a target \(p\) with its energy, and a statement of what is held fixed while \(F[q]\) is pushed down. Its error is then the gap \(T\,D_\mathrm{KL}(q\|p)\), named before anything is computed. Not every method of the course has this form, and Table 27.1 sorts them by how they relate to the identity. Five methods bound: they are specializations, and their rows give the family and the gap. Two saturate: they aim at the equality case \(q = p\), and their error is a gap that vanishes, in time or along a schedule. Two more do neither. Contrastive divergence runs the saturating sampler for only \(k\) steps and uses the result inside a gradient, and score matching removes\(Z\) by differentiating with respect to configuration; neither minimizes \(F[q]\) over anything, and their errors are of another kind. The table is finer than the stations of Figure 27.1, and two stations have no row, for reasons given under ⑨.
Table 27.1: The course’s methods sorted by stance. The bound rows are specializations of Equation 27.2, with a family for \(q\), what is held fixed, and a gap that is a KL divergence; the saturating rows approach its equality case; contrastive divergence and score matching are not bounds on \(F[q]\), and their errors are of another kind.
method (home)
stance
family for \(q\); held fixed
the error
mean field (W5)
bound
products \(\prod_i q_i(x_i)\); \(E\), \(T\)
\(T\,D_\mathrm{KL}(q\|p)\): the discarded correlations
belief propagation (W6)
bound, on a tree
beliefs consistent on the graph; the factor graph
zero on a tree; off trees the Bethe error, of either sign
ELBO, VAE (W5, W7)
bound, clamped
amortized \(q_\phi(z \mid x)\); data \(x\), decoder
\(D_\mathrm{KL}(q_\phi \| p(z \mid x))\): posterior \(+\) amortization gap
diffusion, DDPM (W12)
bound, clamped on paths
\(q\) is the corruption chain \(q(x_{1:T} \mid x_0)\), itself fixed; the model \(p_\theta\) is fitted
\(\tfrac{1}{\beta}\,D_\mathrm{KL}(q \| p_\beta)\), to the Boltzmann encoder \(p_\beta(\tilde{x} \mid x)\)
MCMC (W8–W9)
saturate
the chain’s law \(q_t\) after \(t\) steps; the target \(p\)
\(T\,D_\mathrm{KL}(q_t\|p)\), decaying at the mixing rate
simulated annealing (W8)
saturate, along a schedule
the equilibria \(p_T\); \(E\)
zero at each rung; the error moves to the schedule
contrastive divergence (W3)
saturate, truncated
not a specialization: \(k\) sweeps from the data replace an equilibrium sample
a bias in the gradient, not a KL gap
score matching (W10)
remove \(Z\)
not a specialization: \(\nabla_x \log Z = 0\), no \(F[q]\)
the Fisher divergence between scores
① Mean field and TAP (Weeks 5–6). Restrict \(q\) to a product \(\prod_i q_i(x_i)\) and minimize: stationarity gives the self-consistency equations Equation 9.5, and the gap \(T\,D_\mathrm{KL}\) is exactly the correlation structure the factorization cannot carry — largest near criticality, where correlations are long-ranged, which is why mean field fails worst there. TAP (Equation 11.2) keeps the trial magnetizations and corrects the functional instead, adding the Onsager reaction term as the next order of the Plefka expansion (Plefka 1982). The truncated expansion is the functional of no family, so TAP leaves the bound row: its estimate is far closer to the truth and can sit on either side of it. Week 6’s AMP transplanted the same correction to compressed sensing.
② Belief propagation (Week 6). Widen the family from single-site products to locally consistent pair beliefs and replace \(F\) by its Bethe approximation (Equation 12.3): the stationary points are exactly the fixed points of the message-passing equations (Yedidia, Freeman, and Weiss 2003). On a tree the beliefs define a normalized distribution, the Bethe functional is \(F[q]\) for it, and the gap closes at the fixed point. On loopy graphs the beliefs need not belong to any distribution, the Bethe functional is not a bound, and the loops set an error of either sign.
③ The ELBO (Weeks 5 and 7). Clamp the observed variables and the hidden ones form a Boltzmann system of their own, whose partition function is the probability of the observation (Equation 9.2, Equation 9.3). Equation 27.2 applied to that clamped system is Equation 9.4: the evidence lower bound is \(-F[q]\), so maximizing a likelihood bound is minimizing a free energy, term for term (Equation 14.6). The VAE’s amortized family \(q_\phi(z \mid x)\) makes the minimization a single neural-network pass (Kingma and Welling 2014), and its training curve is a free-energy descent whose remaining height above \(-\log p(x)\) is a KL (Equation 14.1).
④ Diffusion models (Week 12). The DDPM bound is ③ once more, on paths. The generative chain defines a joint \(p_\theta(x_{0:T})\); clamping the data \(x_0\) leaves the path \(x_{1:T}\) as the hidden variable, whose partition function is the model likelihood \(p_\theta(x_0) = \sum_{x_{1:T}} p_\theta(x_{0:T})\). Gibbs–Bogoliubov with the trial \(q(x_{1:T} \mid x_0)\), the corruption chain, gives Equation 23.3, and its gap is the posterior gap of the clamped path ensemble, \(D_\mathrm{KL}\big(q(x_{1:T} \mid x_0) \,\|\, p_\theta(x_{1:T} \mid x_0)\big)\). Two features distinguish the row. The trial distribution has no parameters, since the corruption chain contains nothing to learn, so the descent moves the model \(p_\theta\), that is, the energy of the path ensemble, toward the fixed trial rather than the trial toward the target. And Anderson’s theorem (Equation 20.2) guarantees that a Gaussian reverse chain can close the gap in the small-step limit. The per-step terms of the bound are the denoising score matching of Week 10, which is how the score enters a likelihood bound.
⑤ The information bottleneck (Week 13). For each input \(x\), the braced quantity of Week 13’s rearranged Lagrangian is a free energy over representations, \(F_x[q] = \langle d(x, \tilde{x}) \rangle_q + \tfrac{1}{\beta}\,D_\mathrm{KL}[q \,\|\, p(\tilde{x})]\), with the distortion as energy, \(1/\beta\) as temperature, and the entropy measured relative to the marginal. At fixed marginal and decoder, the substitution that produced Equation 27.2, now with \(\log p_\beta = \log p(\tilde{x}) - \beta d - \log Z(x, \beta)\), gives \[
F_x[q] \;=\; f(x, \beta) \;+\; \tfrac{1}{\beta}\, D_\mathrm{KL}\big(q \,\big\|\, p_\beta(\cdot \mid x)\big),
\] with \(f\) the per-input free energy Equation 25.3 and \(p_\beta\) the Boltzmann encoder of Equation 25.2. The gap is the KL divergence to that encoder, and it closes at each encoder update of Blahut–Arimoto. The mean distortion \(\langle d \rangle = I(X;Y) - I(\tilde{X};Y)\) is the energy term of \(F_x\), not its gap: it stays positive at the optimum, as the price of compression at finite \(\beta\). Because the marginal and decoder move with the encoder, the joint problem is not convex, and the specialization holds one step of the alternation at a time.
⑥ MCMC (Weeks 8–9). Refuse any restriction and demand the saturating \(q = p\): detailed balance (Equation 15.1) builds a chain whose stationary state is exactly the Boltzmann distribution, with \(Z\) cancelling in every acceptance ratio (Equation 15.3). The law of the chain after \(t\) steps is a trial \(q_t\), and its gap decays at the mixing rate; the bias is exchanged for mixing time. Week 9 read SGD itself in this row: a discretized Langevin equation whose stationary measure (Equation 17.4), for isotropic noise, is a Boltzmann distribution on weight space — real SGD noise is state-dependent and generically misaligned with the curvature, hence generically out of equilibrium (Chaudhari and Soatto (2018)), so the identification is the leading approximation, not an equality.
⑦ Simulated annealing (Week 8). Hold the family at the exact equilibria \(p_T\) and move the temperature: in \(F = \langle E \rangle - TS\), high \(T\) weights the entropy (broad, easy to sample) and \(T \to 0\) concentrates all probability on the energy minima (Equation 16.1) (Kirkpatrick, Gelatt, and Vecchi 1983). The gap is zero at every rung; the limitation is instead the schedule, since cooling faster than the mixing time of ⑥ quenches into metastable states (Figure 16.1).
⑧ Contrastive divergence (Week 3). The maximum-likelihood gradient needs a sample of \(p\) in its negative phase (Equation 5.5). CD-\(k\) (Equation 6.5) takes the sampler of ⑥, starts it at the data, and stops after \(k\) sweeps. The chain’s law \(q_k\) obeys Equation 27.2 like any distribution, but no \(F[q]\) is minimized: \(q_k\) only stands in for \(p\) inside a gradient, and the error is the bias of that gradient, which no KL divergence bounds.
⑨ Score matching (Week 10). Differentiate the logarithm with respect to configuration and \(Z\) leaves the problem: \(\nabla_x \log p = -\beta \nabla_x E\) (Equation 19.1), a training target that needs no normalizer, and Anderson’s reverse SDE (Equation 20.2) turns the learned score into a generator. The objective is the Fisher divergence between model and data scores (Equation 19.2), not a KL to a target, and nothing in it is a free energy. Two stations of Figure 27.1 have no row because they approximate no distribution. Week 11’s Jarzynski equality and AIS measure\(Z\), without bias (and \(\log Z\) consistently), as an average over driven paths (Equation 21.1, Equation 22.3); Week 12’s probability-flow ODE makes the likelihood of a trained score model exact (Equation 24.2).
27.5 One obstruction, two faces
The read-off resolves two questions that have recurred since Week 1. The first asked whether the spine of the course is the partition function or the variational free-energy principle. By Equation 27.1 they are the same object, and the course simply used whichever face made the current obstruction visible — \(Z\) when the problem was normalization, \(F\) when the method was variational. The second asked whether the course has one recurring obstruction or two, since normalization blocks training (Module 1) while sampling hardness blocks estimation (Module 3). These are also one wall seen from two sides: if \(Z\) were cheap, \(p\) could be normalized and sampled directly; if \(p\) were cheap to sample, \(Z\) could be estimated by the free-energy methods of Week 11; and both statements are the assertion that \(F[q]\) is hard to push to its floor. The bound of Module 2, the sampler of Module 3, and the removal of Module 4 are three escapes from the same wall, priced respectively in bias (a KL gap), in time (mixing), and in scope (the score gives generation and likelihood, but never a thermodynamic potential unless Week 11’s machinery is added).
Since \(F = -T \log Z\), the partition function and the free energy are one spine, and every method the course built either bounds \(F\) over a family, samples the \(q = p\) that saturates the bound, or removes \(Z\) by differentiating a logarithm.
27.6 Example: a double well
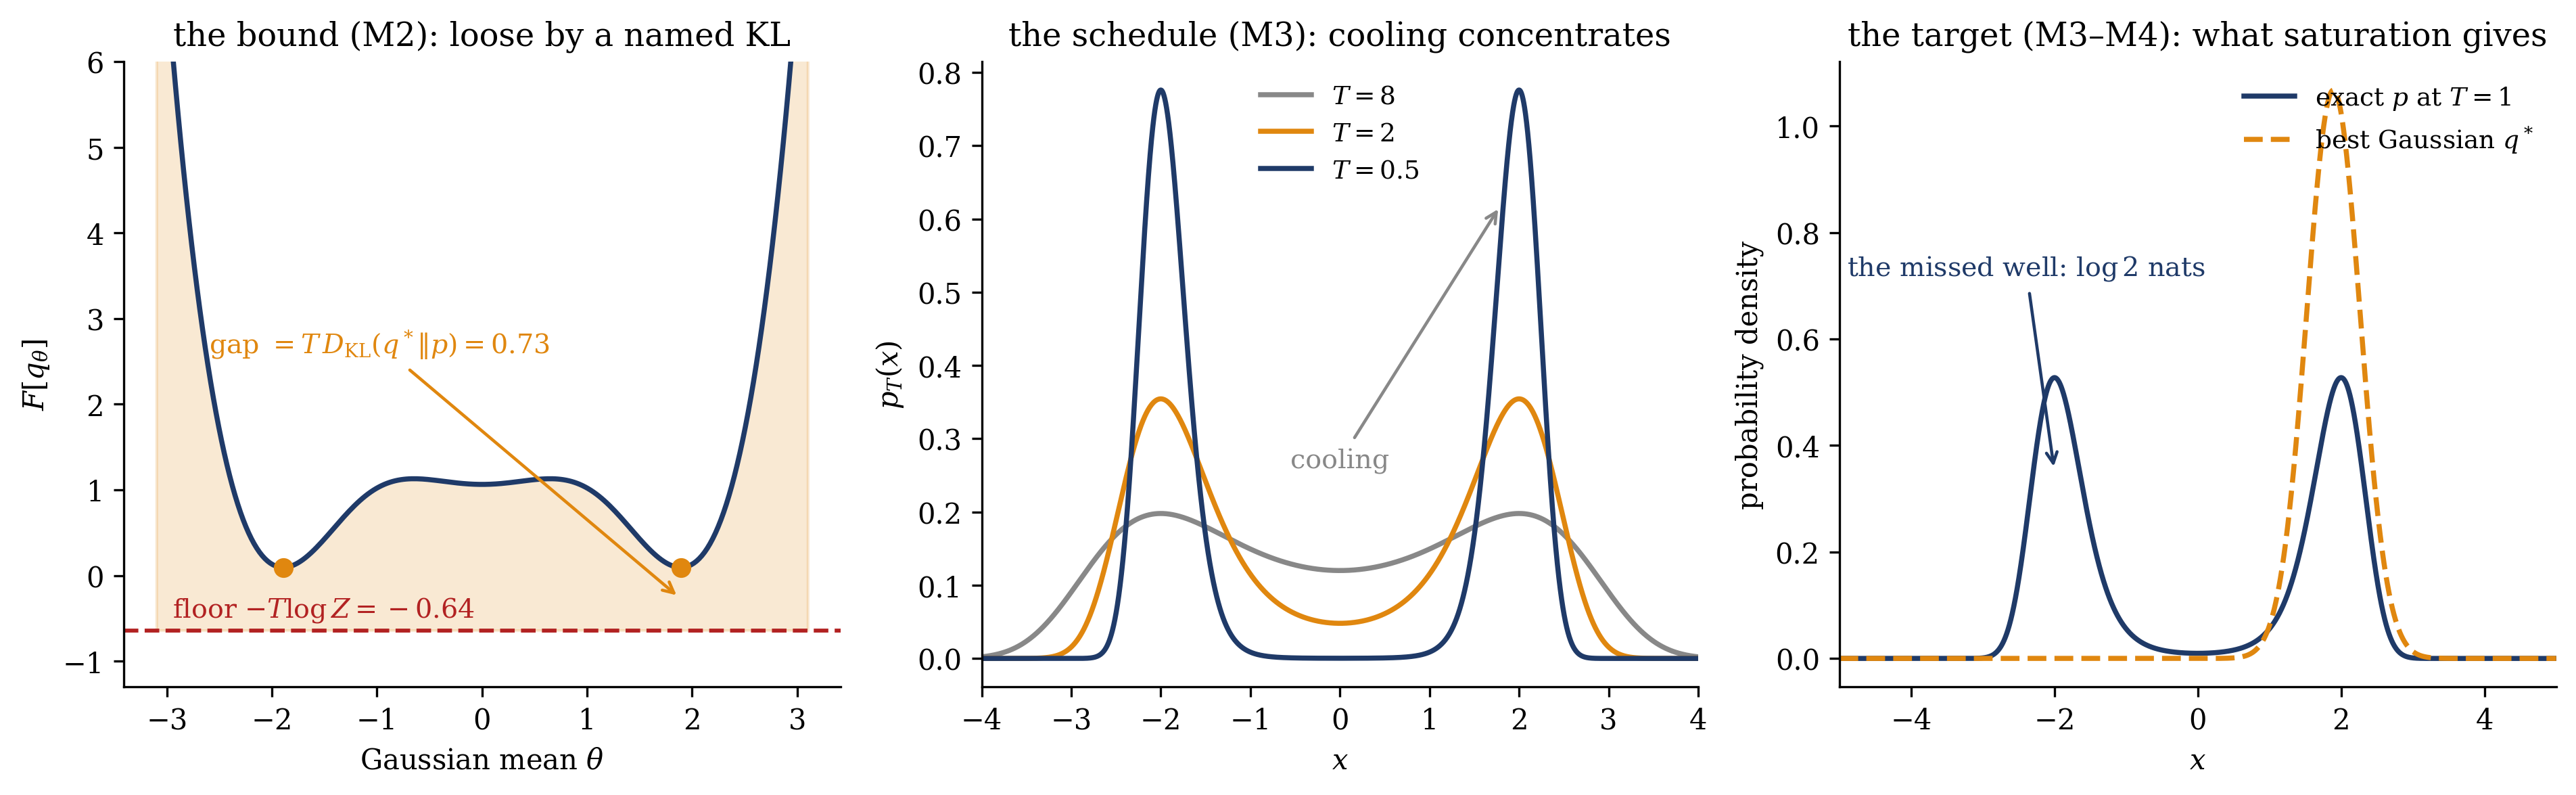
We illustrate the synthesis on the course’s recurring stage set: a bistable energy, the continuous cousin of the two-mode target that Modules 3 and 4 sampled all semester. Take the double well \(E(x) = (x^2 - a^2)^2/4\) with \(a = 2\), so the wells sit at \(x = \pm 2\) and the barrier is \(4\) (in units of \(T\) at \(\beta = 1\)). Everything below is deterministic grid quadrature — no sampling, so every number is exact to plotting accuracy and the whole cell runs in seconds. We compute the floor \(-T \log Z\) once, then put three stances on it: the bound of Module 2, evaluated for the family of single Gaussians \(q_{\theta} = \mathcal{N}(\theta, \sigma^2)\) with \(\sigma\) optimized at each mean \(\theta\) (the moments of a quartic energy under a Gaussian are analytic, so \(F[q_\theta]\) needs no integrals at all); the cooling of Module 3, as the exact Boltzmann distribution \(p_T\) along a temperature ladder; and the target itself, which the sampling and score routes reach and the restricted family cannot.
Figure 27.2: The bound, the schedule, and the target on one landscape (double well \(E(x) = (x^2 - a^2)^2/4\), \(a = 2\), barrier \(= 4T\) at \(T = 1\); deterministic grid quadrature). Left: the variational free energy \(F[q_\theta]\) of the best Gaussian \(\mathcal{N}(\theta, \sigma^2(\theta))\) against its mean \(\theta\), with the exact floor \(-T\log Z = -0.640\) (red dashed) and the gap \(T\,D_\mathrm{KL}(q_\theta \| p)\) shaded. The bound Equation 27.2 holds everywhere; the best single Gaussian (\(\theta^* = \pm 1.89\), \(\sigma^* = 0.37\)) stops \(0.734\) nats above the floor; approximately \(\log 2 = 0.693\) of that gap is the well the ansatz cannot represent, the remaining \(0.041\) the shape mismatch inside the well it keeps. The variational landscape has three minima: the two one-well Gaussians at \(\pm\theta^*\) and, \(0.97\) nats higher, a broad Gaussian (\(\sigma = 1.24\)) straddling both wells at \(\theta = 0\), separated by maxima at \(\theta \approx \pm 0.65\). The restricted family breaks the symmetry it cannot describe, while the symmetric solution survives as a metastable state. Center: the exact Boltzmann \(p_T \propto e^{-E/T}\) at \(T = 8, 2, 0.5\) — cooling concentrates the target onto its wells (the barrier-to-well probability ratio falls from \(0.61\) to \(3\times 10^{-4}\)), the annealing mechanism of Equation 16.1, with the mixing cost of Week 8 visible in the vanishing weight between the wells. Right: at \(T = 1\), the exact bimodal target (navy) against the best single Gaussian (orange dashed) — the panel-left gap made visible as the missing mode, which the sampling route (Week 8) and the score route (Weeks 10 and 12) recover because neither restricts the family.
Figure 27.2 places three stances on one landscape, and its numbers can be checked by hand. The left panel is Week 5’s projection made quantitative on a target where we can check everything: the best single-Gaussian member stops at \(F[q^*] = 0.095\), which is \(0.734\) nats above the floor \(-T \log Z = -0.640\). For well-separated wells, a unimodal family loses approximately the \(\log 2 = 0.693\) nats of the abandoned mode, and the remaining \(0.041\) nats is the shape mismatch between a Gaussian and one quartic well. The variational curve \(F[q_\theta]\) has three minima in \(\theta\): the global pair at \(\pm 1.89\), where a narrow Gaussian commits to one well, and a shallow local minimum at \(\theta = 0\) (\(F = 1.064\)), where a broad Gaussian with \(\sigma = 1.24\) straddles both wells and fits neither, separated from the global pair by maxima at \(\theta \approx \pm 0.65\) (\(F = 1.130\)). The restricted family therefore breaks the symmetry it cannot represent, but discontinuously: the symmetric solution does not become unstable, as \(m = 0\) did at the continuous pitchfork of Equation 10.2, and instead survives as a metastable state above the symmetry-broken optimum. That is the coexistence picture of a first-order transition, the same structure as the uninformative and informative minima of Week 13’s hard phase (Section 26.4), here in a one-parameter fit. The center panel is the annealing mechanism with no algorithm attached: the exact minimizer of \(F[q]\) at each temperature is \(p_T\) itself, broad and barrier-crossing at \(T = 8\), essentially two disconnected wells by \(T = 0.5\); the vanishing of the between-well weight is exactly why Week 8’s chains mix exponentially slowly when quenched. The right panel is what the unrestricted stances deliver: MCMC (Week 8) and the learned score with its reverse SDE (Weeks 10 and 12) both target the navy curve, both wells included, because neither method ever wrote down a family — one saturates the bound by construction, the other bypasses \(Z\) by differentiation. The mixture \(0.7\,\mathcal{N}(-3, 0.5^2) + 0.3\,\mathcal{N}(3, 0.5^2)\) that served as Week 10’s standing target is this panel with unequal wells.
Trap
Four ways to misread the synthesis. ① The bound runs opposite to the ELBO by a sign.\(F[q] \geq -T\log Z\) is minimized; the ELBO \(= -F[q]\) is maximized and lower-bounds the log-evidence (Equation 9.4). They are the same inequality read from opposite faces — keep the convention \(p \propto e^{-\beta E}\) fixed and state which face you are on before manipulating signs. ② The gap is a KL divergence, not hand-waving. “Mean field is approximate” means precisely \(F[q] - F[p] = T\,D_\mathrm{KL}(q\|p) \geq 0\), computable in principle and computed above (\(0.734\) nats); an answer that treats the error as unquantifiable has missed the point of Equation 27.2. ③ Saturation has a cost in time. Reaching \(q = p\) exactly (Module 3) replaces the bound’s bias with mixing time; on the landscape above, the same barrier that starves the between-well weight is what traps the sampler. ④ Removed is not measured. Score matching makes \(Z\) irrelevant because \(\nabla_x \log Z = 0\) (Equation 19.1); it does not deliver \(\log Z\). Producing the number took Week 11’s work relations (Equation 21.1) — the stances “removed” and “measured” are distinct stations of Figure 27.1, and collapsing them is a category error.
Take-home 2
On one double-well landscape, the variational bound is visibly loose for a single-Gaussian family (a gap of \(0.734\) nats, of which \(\log 2\) is the missed mode), tightens to the floor only at \(q = p\), and is walked downhill by cooling \(T\) — mean field, annealing, and the exact target are three readings of Equation 27.2.
27.7 Outlook: the frontier and the title
The next lecture is structured exam preparation: question-driven, with two or three derivations worked end to end in the format of the written exam. For revision, the scaffold of Table 27.1 applies to any method: state its stance (bound, saturate, or remove \(Z\)); for a bound, what family \(q\) is restricted to and what is held fixed; and what its error is, the gap \(T\,D_\mathrm{KL}\) for a specialization and something else otherwise. Those answers locate the method on Table 27.1 and on Figure 27.1.
Alongside the \(Z\) spine, a second thread ran the length of the semester — phase transitions in learning systems: the capacity \(\alpha_c\) at which memory retrieval fails (Equation 4.6), the \(T_c\) at which mean field orders (Equation 10.2), the convergence boundaries of message passing, and finally Week 13’s detectability threshold (Equation 26.4), where the thread became the subject. That is the course’s live frontier, surveyed in Section 26.7: neural-tangent-kernel and feature-learning theory (Jacot, Gabriel, and Hongler 2018), random-matrix analyses of learning curves, the spin-glass picture of deep loss landscapes (Choromanska et al. 2015), and the statistical-physics-of-inference programme (Zdeborová and Krzakala 2016).
The title of the course names the route from Boltzmann to diffusion. The Boltzmann distribution entered as a modeling choice in Week 1 (Equation 1.2); the methods that followed span 1953 (Metropolis) to 2021 (probability-flow ODE). The pointers above, together with the free-energy synthesis of Welling, Lu, and Holdijk (2026), are where a student of this course can begin research with this toolkit.
Bethe, Hans A. 1935. “Statistical Theory of Superlattices.”Proceedings of the Royal Society of London A 150 (871): 552–75. https://doi.org/10.1098/rspa.1935.0122.
Chaudhari, Pratik, and Stefano Soatto. 2018. “Stochastic Gradient Descent Performs Variational Inference, Converges to Limit Cycles for Deep Networks.” In International Conference on Learning Representations (ICLR).
Choromanska, Anna, Mikael Henaff, Michael Mathieu, Gérard Ben Arous, and Yann LeCun. 2015. “The Loss Surfaces of Multilayer Networks.” In AISTATS 2015, PMLR, 38:192–204.
Jacot, Arthur, Franck Gabriel, and Clément Hongler. 2018. “Neural Tangent Kernel: Convergence and Generalization in Neural Networks.” In NeurIPS. Vol. 31.
Kingma, Diederik P., and Max Welling. 2014. “Auto-Encoding Variational Bayes.” In International Conference on Learning Representations (ICLR).
Kirkpatrick, Scott, C. Daniel Gelatt, and Mario P. Vecchi. 1983. “Optimization by Simulated Annealing.”Science 220 (4598): 671–80. https://doi.org/10.1126/science.220.4598.671.
Onsager, Lars. 1936. “Electric Moments of Molecules in Liquids.”Journal of the American Chemical Society 58 (8): 1486–93. https://doi.org/10.1021/ja01299a050.
Plefka, Timm. 1982. “Convergence Condition of the TAP Equation for the Infinite-Ranged Ising Spin Glass Model.”Journal of Physics A: Mathematical and General 15 (6): 1971–78. https://doi.org/10.1088/0305-4470/15/6/035.
Sohl-Dickstein, Jascha, Eric Weiss, Niru Maheswaranathan, and Surya Ganguli. 2015. “Deep Unsupervised Learning Using Nonequilibrium Thermodynamics.” In Proceedings of the 32nd International Conference on Machine Learning, 37:2256–65. Proceedings of Machine Learning Research. https://arxiv.org/abs/1503.03585.
Thouless, David J., Philip W. Anderson, and Richard G. Palmer. 1977. “Solution of ’Solvable Model of a Spin Glass’.”Philosophical Magazine 35 (3): 593–601. https://doi.org/10.1080/14786437708235992.
Tishby, Naftali, Fernando C. Pereira, and William Bialek. 1999. “The Information Bottleneck Method.” In Proc. 37th Allerton Conference on Communication, Control, and Computing, 368–77.
Welling, Max, Sirui Lu, and Lars Holdijk. 2026. Generative AI and Stochastic Thermodynamics: A Tale of Free Energies. Cambridge: Cambridge University Press. https://doi.org/10.1017/9781009709071.
Yedidia, Jonathan S., William T. Freeman, and Yair Weiss. 2003. “Understanding Belief Propagation and Its Generalizations.” In Exploring Artificial Intelligence in the New Millennium, edited by Gerhard Lakemeyer and Bernhard Nebel, 239–69. San Francisco: Morgan Kaufmann.
Zdeborová, Lenka, and Florent Krzakala. 2016. “Statistical Physics of Inference: Thresholds and Algorithms.”Advances in Physics 65 (5): 453–552. https://doi.org/10.1080/00018732.2016.1211393.